Section 1: Understanding Traditional Compiler Optimization and Its Limitations
How Traditional Compilers Optimize Source Code
A compiler transforms a program written in a high-level language into a lower-level representation that a processor can execute. This process involves several stages, including lexical analysis, parsing, semantic analysis, intermediate representation generation, optimization, and machine-code generation.
Modern optimizing compilers typically use an intermediate representation (IR) to describe program operations independently of the original source language and, to some extent, the target hardware.
LLVM IR is a prominent example. It provides a representation of operations such as arithmetic, memory access, function calls, and control flow. Compiler optimization passes operate on this representation before the backend translates it into target-specific instructions.
Consider a simple function:
int calculate(int x) {
int result = x * 2;
return result + 0;
}
A compiler can recognize that adding zero does not change the result and remove the unnecessary operation. It may also simplify multiplication by a constant or replace it with a more efficient instruction, depending on the target processor.
This is an example of a local optimization. More complex optimizations involve analyzing relationships across multiple instructions, functions, or entire program regions.
Common compiler optimizations include constant propagation, dead-code elimination, loop unrolling, common subexpression elimination, function inlining, instruction scheduling, and register allocation.
These transformations can improve execution efficiency, but their benefits depend on context. Unrolling a loop may reduce branching overhead but increase code size. Inlining a function may eliminate call overhead but increase instruction-cache pressure. Reordering instructions may improve processor utilization but create new dependencies or scheduling constraints.
The compiler must therefore decide not only which transformations are legal, but also which transformations are likely to produce the best outcome.
Why Compiler Heuristics Cannot Always Predict Performance
Traditional compilers use heuristics because evaluating every possible optimization sequence is usually impractical.
A heuristic is a decision rule that estimates which action is likely to produce a useful result without exhaustively exploring every alternative.
For example, a compiler may use function size, call frequency estimates, and other features to determine whether a function should be inlined. It may use estimated register pressure and variable live ranges to guide register allocation.
These rules are often effective because compiler engineers encode extensive knowledge about program behavior and processor characteristics.
However, heuristics can struggle with complex interactions.
Suppose a function is slightly larger than the compiler's inlining threshold. Inlining it may initially appear expensive because it increases the caller's code size. However, after inlining, the compiler may discover that several branches become unnecessary because their conditions are known at compile time.
The combined effect of inlining and subsequent constant propagation could produce a smaller or faster program than the original version.
A simple threshold-based heuristic may not anticipate this interaction.
The same issue occurs in register allocation. A decision that appears locally beneficial may create additional register spills later. These spills can increase memory traffic and reduce execution performance.
The central problem is that compiler optimizations are interdependent. The outcome of one transformation can change the value of another transformation.
This makes compiler optimization a decision problem involving multiple interacting variables rather than a collection of independent rules.
Learned Query Optimization and the Broader Shift Toward Learned Systems
The use of machine learning in compilers is part of a broader trend in systems engineering: replacing selected manually designed decision rules with models trained from execution data.
Database query optimization provides a useful parallel. A database optimizer estimates the cost of alternative query execution plans and selects one expected to perform well. Traditional systems rely on statistics and cost models, but inaccurate estimates can lead to poor plan selection.
Machine learning can help predict query costs or guide the selection of execution strategies using information collected from previous workloads.
Compiler optimization faces a similar challenge. Instead of selecting a database execution plan, the compiler chooses transformations that influence the final machine code.
Both problems involve searching a large decision space under imperfect performance estimates.
The connection is explored in “Learned Query Optimization: How Machine Learning Is Changing Database Query Execution”, which discusses how learned models can improve optimization decisions in database systems. The same broad engineering principle applies to compilers: machine learning can complement established optimization algorithms when manually designed cost models cannot capture every relevant interaction.
The important distinction is that learning-based optimization should not be confused with unrestricted code generation. The compiler still needs reliable semantic analysis and correctness-preserving transformations. Machine learning primarily helps decide which legal transformations are likely to produce better results.
Key Takeaway
Traditional compilers already perform sophisticated optimization, but many decisions rely on manually designed heuristics and cost models. These rules cannot always predict the combined effects of interacting transformations or the performance characteristics of different programs and hardware. Learning-based compilation addresses this limitation by using models trained on program features and optimization outcomes to guide selected decisions while preserving the compiler's existing correctness guarantees.
Section 2: How Machine Learning Models Guide Compiler Optimization
Learning-Based Optimization Through Program Features
A learning-based compiler needs a representation of the program that a machine learning model can analyze.
The model cannot simply receive an entire source file as unstructured text and make reliable optimization decisions without considering the compiler's internal representation.
Instead, compiler systems can extract features from source code, intermediate representations, control-flow graphs, instruction sequences, and other program structures.
For example, a model deciding whether to inline a function might receive features describing the caller, the callee, and the call site. These could include function size, instruction counts, call frequency estimates, control-flow characteristics, and information about optimization opportunities.
A simplified feature vector could look like this:
features = {
"caller_instruction_count": 120,
"callee_instruction_count": 18,
"call_frequency_estimate": 250,
"loop_depth": 2,
"branch_count": 4,
"estimated_code_growth": 18
}
These values are illustrative. A production compiler uses features defined by its specific optimization problem and available analysis information.
The feature vector is passed to a trained model, which predicts a decision or score. For example, the model may estimate whether inlining is likely to improve code size or execution performance.
A simplified decision function is:
[
a^* = \arg\max_{a \in A} Q_\theta(s,a)
]
Here, (s) represents the current compiler state, (A) represents the available optimization actions, and (Q_\theta(s,a)) estimates the value of choosing action (a).
Not every learning-based compiler uses a Q-function. Some use classification models, regression models, policy networks, or ranking models. The appropriate model depends on whether the optimization task involves selecting a category, estimating a cost, ranking alternatives, or learning a sequence of decisions.
The important requirement is that program features must capture information relevant to the optimization objective without creating excessive inference overhead.
Reinforcement Learning for Compiler Decisions
Reinforcement learning is particularly relevant when compiler optimization involves a sequence of decisions whose outcomes depend on earlier actions.
In reinforcement learning, an agent interacts with an environment and learns a policy that selects actions to maximize cumulative reward.
Compiler optimization can be represented in a similar way.
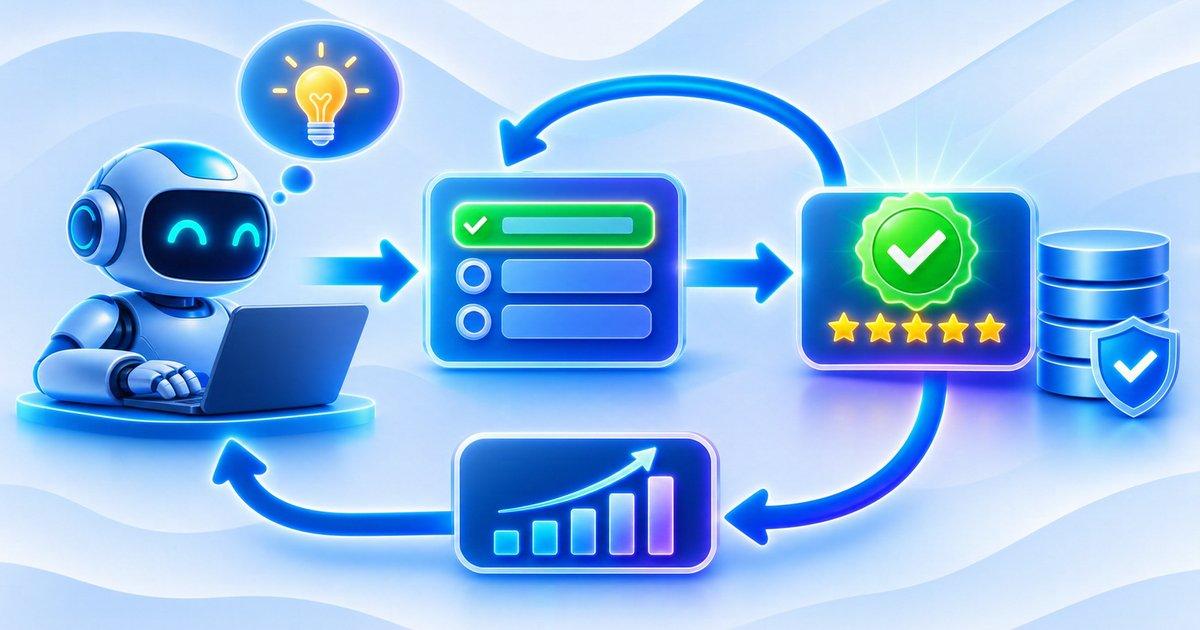
The compiler's current program representation acts as the state. An optimization pass or transformation represents an action. The resulting intermediate representation becomes the next state. The reward measures the quality of the final compiled program.
A simplified formulation is:
[
R = \alpha \Delta P - \beta \Delta S - \gamma C
]
Here, (\Delta P) represents improvement in performance, (\Delta S) represents the change in code size, and (C) represents the cost of compilation or another operational constraint. The weights (\alpha), (\beta), and (\gamma) express the relative importance of these objectives.
In practice, the reward function must be carefully designed. A model optimizing only instruction count may produce a smaller program that executes more slowly. A model optimizing only execution time may generate a binary that is too large for an embedded device.
The reward should therefore reflect the actual deployment objective.
For example, a compiler optimizing an application for a mobile device may need to balance execution latency, binary size, energy consumption, and memory usage. A compiler optimizing a server workload may prioritize throughput and CPU utilization.
Reinforcement learning can also be used for compiler auto-tuning, where an agent experiments with optimization-pass sequences and receives feedback based on the resulting program.
CompilerGym provides research environments for compiler optimization tasks. Its LLVM instruction-count environment, for example, exposes optimization passes as actions and allows agents to search for sequences that reduce instruction count.
This makes compiler optimization a practical reinforcement learning research problem rather than merely a theoretical analogy.
MLGO: Bringing Machine Learning Into LLVM
One of the most important examples of learning-based compiler optimization is MLGO, or Machine Learning Guided Optimization.
Developed through work involving Google and LLVM, MLGO provides a framework for integrating machine learning models into compiler optimization decisions.
The framework initially focused on two important areas: inlining for code size and register allocation for performance.
Function inlining replaces a function call with the body of the called function. This can reduce call overhead and expose additional optimization opportunities, but it can also increase binary size.
MLGO uses learned models to guide inlining-for-size decisions. Instead of relying exclusively on fixed thresholds, the model can consider features describing the caller, callee, and call site.
Register allocation presents a different problem. A compiler must assign program variables and intermediate values to a limited set of physical registers. When there are more live values than available registers, the compiler must decide which values to evict or spill.
These decisions affect memory traffic and execution performance. MLGO integrates learned decision-making into LLVM's register-allocation workflow to guide selected eviction decisions.
The original MLGO research described a learned inlining-for-size model that achieved up to a 7% code-size reduction compared with LLVM's state-of-the-art -Oz optimization pipeline in the reported evaluation. This is a result from that particular study and should not be interpreted as a universal improvement across all programs or targets.
LLVM's documentation also describes how models are integrated into compilation and how training and inference workflows interact with compiler infrastructure.
The significance of MLGO is architectural as well as experimental. It demonstrates that machine learning can be introduced into an established industrial compiler through defined interfaces and controlled optimization decisions.
Combining Learned Models With Intermediate Representations
The quality of a learning-based compiler depends heavily on how it represents programs.
Source code contains useful information, but it also contains syntactic details that may not directly correspond to machine-level behavior. Intermediate representations provide a more structured view of program operations.
LLVM provides embedding frameworks such as IR2Vec and MIR2Vec that generate vector representations of LLVM IR and Machine IR entities. These representations can capture information about instructions, types, operands, and program structure, supporting downstream machine learning tasks.
A learned compiler could use these embeddings to identify similarities between program fragments or estimate the likely effects of optimization decisions.
For example, two functions may have different source code but exhibit similar control-flow patterns and instruction structures. An embedding model could potentially represent these functions in a way that helps an optimization model transfer knowledge between them.
However, learned representations must preserve the information required for the target decision. A compact embedding may lose details that matter for register pressure, memory dependencies, or target-specific instruction selection.
There is also an important distinction between semantic representation and optimization prediction. An embedding can describe similarities between program fragments, but it does not automatically determine whether a transformation is legal or beneficial.
A reliable architecture therefore separates compiler correctness checks from learned optimization guidance. The compiler verifies that a transformation is permitted, while the model estimates whether choosing it is likely to improve the desired objective.
Key Takeaway
Learning-based compilers use program features, intermediate representations, and trained models to guide optimization decisions. Reinforcement learning can explore sequences of compiler transformations, while supervised models can predict the value of individual decisions. MLGO demonstrates how these techniques can be integrated into LLVM for tasks such as function inlining and register allocation without removing the compiler's underlying correctness mechanisms.
Section 3: Real-World Applications of Learning-Based Compiler Optimization
Compiler Auto-Tuning and Optimization-Pass Selection
Compiler auto-tuning is one of the most direct applications of machine learning in code optimization.
A compiler exposes multiple optimization passes, each of which transforms the intermediate representation in a particular way. The challenge is selecting a sequence that produces the best result for a specific program and target.
Traditional compilers use predefined optimization pipelines. Auto-tuning systems explore alternatives and evaluate their impact on code size, execution time, or other performance metrics.
Machine learning can make this exploration more efficient by learning which sequences are promising.
For example, an agent might discover that a particular sequence of loop transformations and constant propagation passes works well for a numerical workload. Another program may benefit from a different combination.
Instead of evaluating every possible sequence, the model can use previous observations to prioritize promising candidates.
CompilerGym provides an environment for studying this problem through reinforcement learning. Its LLVM instruction-count task allows optimization passes to be selected as actions, with rewards based on the resulting instruction count.
Research such as Compiler-R1 has also explored reinforcement-learning-driven compiler auto-tuning using an agent that interacts with a compilation environment. The 2025 preprint reports an average 8.46% reduction in intermediate-representation instruction count compared with opt -Oz across its evaluated datasets. These findings are specific to its experimental setup and are not a general guarantee of runtime improvement.
The broader opportunity is that compiler optimization can become more adaptive. Rather than applying the same pipeline to every program, the compiler can use learned information to select transformations based on program characteristics.
Hardware-Aware Optimization for CPUs, GPUs, and Accelerators
Modern processors have very different execution characteristics.
A CPU may benefit from instruction-level parallelism, efficient branch prediction, cache locality, and effective register usage. A GPU is designed to execute many operations in parallel, but its performance can depend heavily on memory access patterns, thread organization, and occupancy.
Specialized accelerators introduce additional constraints involving supported operations, data layouts, memory movement, and execution scheduling.
A learning-based compiler can use hardware-specific features to predict which transformations are likely to work well on a particular platform.
For example, a model could estimate whether loop unrolling will improve performance on a target CPU or whether a particular tiling strategy will improve memory access efficiency on a GPU.
The model might consider:
- Target instruction set and processor characteristics.
- Estimated instruction count.
- Memory access patterns.
- Register pressure.
- Loop structure and nesting depth.
- Vectorization opportunities.
- Cache behavior estimates.
- Parallel execution characteristics.
These features can be used to predict performance or rank alternative compilation strategies.
However, hardware-aware optimization requires reliable feedback. A transformation that looks favorable from static program features may behave differently when executed on real hardware due to cache misses, contention, thermal limits, or runtime variability.
This is why learning-based optimization often benefits from combining static analysis with measured execution results.
The most useful models are not necessarily those that make the most complex predictions. They are the models that improve decisions while keeping inference overhead and compilation cost under control.
Kernel Optimization and Machine Learning Workloads
Machine learning applications frequently depend on computational kernels that perform operations such as matrix multiplication, convolution, tensor transformations, and attention.
These kernels must be optimized for the target hardware to achieve high throughput and low latency.
A compiler that generates GPU kernels may need to select tile sizes, thread configurations, memory layouts, fusion strategies, and instruction sequences. The best configuration depends on tensor dimensions, hardware capabilities, precision, and memory constraints.
Machine learning can support this process by predicting promising kernel configurations or searching through alternative implementations.
For example, a learned tuning model could analyze a matrix multiplication workload and estimate which tile dimensions are likely to achieve good performance on a particular GPU.
The compiler or tuning system can then benchmark selected configurations and use the measurements to update its predictions.
This is related to auto-tuning systems used in high-performance computing, where the goal is to identify efficient implementations for a given workload and hardware configuration.
Learning-based optimization is particularly useful when the search space is too large for exhaustive testing. However, the model must account for the cost of exploration. Running thousands of kernel configurations can take longer than the performance benefit justifies.
A practical system should therefore use learned predictions to reduce the number of candidates that require expensive execution.
Database Engines, Storage Systems, and Specialized Software
Learning-based compiler optimization is relevant beyond traditional application compilation.
Database engines, storage systems, scientific computing frameworks, and high-performance networking software often contain performance-critical code with complex execution characteristics.
A database engine, for example, may generate or compile query execution plans. The performance of these plans depends on data distribution, memory access patterns, operator selection, and hardware behavior.
A learning-based compiler or code-generation system could help optimize specialized execution paths for recurring query patterns.
Similarly, a storage engine may benefit from specialized code for compression, indexing, and data transformation. A learned model could guide the selection of code-generation strategies based on data characteristics and hardware constraints.
These applications share a common requirement: optimization decisions must be made using information about both the program and its execution environment.
However, learning-based optimization should not be confused with replacing database query planning, operating-system scheduling, or storage algorithms entirely. It is more realistic to use machine learning to improve selected decisions within existing systems.
For developers interested in the relationship between learned representations and data-system performance, “Learned Index Structures: Replacing Traditional Database Indexes With Machine Learning” provides a related example of how machine learning can guide performance-sensitive systems decisions.
The broader pattern is consistent: machine learning is most valuable when a system repeatedly makes complex decisions that can be evaluated through measurable outcomes.
Key Takeaway
Learning-based compiler optimization has practical applications in compiler auto-tuning, hardware-aware code generation, GPU kernel optimization, and specialized systems software. These applications share a common opportunity: use data and learned predictions to identify better optimization choices than fixed rules can consistently provide. The most effective implementations combine model-guided exploration with actual compilation and performance measurement.
Section 4: Engineering Challenges, Correctness, and the Future of Learning-Based Compilers
Preserving Program Correctness
Compiler optimization is fundamentally different from many other machine learning prediction tasks because incorrect decisions can change program behavior.
A model predicting an incorrect category in a recommendation system may produce a poor recommendation. A compiler transformation that changes program semantics can cause incorrect calculations, memory corruption, security vulnerabilities, or application failures.
For this reason, correctness must remain a strict requirement.
A learning-based compiler should separate legal transformation decisions from performance decisions.
The compiler's existing analyses and transformation rules determine whether an operation is valid. The machine learning model helps choose among permitted alternatives.
For example, a learned inlining model can decide whether a legal call site should be inlined. It should not override language or compiler constraints that prohibit inlining a function.
Similarly, a learned register-allocation model can help choose which live range to evict, but it must not violate the correctness requirements of register allocation.
This separation is explicitly reflected in LLVM's MLGO documentation, which distinguishes correctness-preserving decisions from optimization decisions.
Testing is still essential. Generated programs should be checked using compiler validation, differential testing, regression suites, and workload-specific correctness tests.
A model that improves average performance but introduces even rare correctness failures is not suitable for production use.
Training Data, Benchmark Diversity, and Generalization
Learning-based compiler models depend on training data that represents the programs they will encounter.
A model trained on a narrow set of applications may learn patterns that work well for those programs but fail when presented with unfamiliar code.
For example, a model trained primarily on numerical workloads may learn optimization patterns that do not transfer well to database engines, networking software, or cryptographic applications.
This is a generalization problem.
Compiler training data should therefore cover a diverse collection of programs, optimization configurations, and target environments.
The training corpus should also represent the actual optimization objective. A model trained to minimize code size may not produce the best runtime performance. A model trained on one processor architecture may not generalize to another architecture with different execution characteristics.
Data quality is equally important. Performance measurements can be affected by system load, cache state, thermal behavior, background processes, and benchmark configuration.
If these effects are not controlled, the model may learn noise rather than useful optimization patterns.
Engineers should use reproducible compilation environments, multiple benchmark runs, appropriate statistical summaries, and separate training and evaluation datasets.
A model should also be tested against programs that were not present in its training corpus. This helps determine whether it has learned general optimization behavior or merely memorized patterns from familiar workloads.
Compilation Overhead and Production Integration
A compiler is expected to produce executable code within a reasonable amount of time. Adding a machine learning model introduces additional computation during compilation.
If a model takes too long to make an optimization decision, it may eliminate the benefits of the transformation it recommends.
For example, spending several seconds exploring optimization alternatives may be reasonable when compiling a large, performance-critical application. It may be unacceptable for a small function compiled repeatedly during an interactive development workflow.
The engineering objective is therefore to balance optimization quality against compilation overhead.
This requires evaluating both the cost of inference and the value of the resulting code.
Production integration also introduces model-versioning and deployment requirements. Compiler builds must use compatible model artifacts, feature definitions, and inference implementations. A model trained using one representation of LLVM IR may not work correctly when the compiler's feature extraction changes.
Engineers need reproducible model packaging, version compatibility checks, fallback mechanisms, and performance monitoring.
A practical deployment strategy is to retain the traditional heuristic as a fallback. If the learned model is unavailable, fails validation, or produces an invalid response, the compiler can continue using its established optimization behavior.
The principles discussed in “MLOps for Software Engineers: Building, Deploying, and Monitoring Machine Learning Models in Production” are relevant here. Learned compiler components require version control, reproducible training, evaluation pipelines, and reliable deployment practices just like other production machine learning systems.
Measuring Success: Runtime, Code Size, Energy, and Reliability
A learning-based compiler should not be judged by a single optimization metric.
Reducing instruction count does not automatically improve execution time. Reducing binary size does not necessarily reduce memory traffic. Increasing compilation time may be acceptable for a long-running server application but undesirable for a frequently rebuilt development project.
The optimization objective must reflect the deployment context.
For a mobile application, binary size and energy consumption may be important. For a cloud service, throughput and latency may dominate. For an embedded device, memory usage and predictable execution time may be essential.
Engineers should measure several dimensions:
| Metric | What it evaluates |
| Runtime latency | Time required to execute the compiled program |
| Throughput | Amount of work completed per unit of time |
| Binary size | Storage required by the generated executable |
| Instruction count | Number of generated or executed instructions, depending on measurement |
| Memory usage | Runtime and compiler memory consumption |
| Energy consumption | Power or energy required to execute workloads |
| Compilation time | Time required to produce the executable |
| Correctness | Whether the optimized program preserves expected behavior |
| Generalization | Whether improvements transfer to unseen programs and workloads |
A reliable evaluation process should compare the learned compiler against a strong traditional baseline under identical conditions.
It should also use multiple workloads, repeated measurements, and clear reporting of the optimization objective.
Testing should include not only average performance but also regressions and worst-case behavior. An optimization that improves most programs while causing a severe slowdown in a critical workload may not be acceptable.
Key Takeaway
Learning-based compilers must satisfy stricter engineering requirements than ordinary predictive systems because their decisions influence executable program behavior. Correctness must remain enforced by compiler mechanisms, while learned models guide performance-related choices. Training data must generalize across programs and hardware, inference overhead must remain controlled, and production deployments must include reproducible evaluation and reliable fallback behavior.
Conclusion: The Future of Compiler Optimization Is Data-Driven
Compilers have traditionally depended on carefully designed algorithms, cost models, and optimization heuristics. These techniques remain essential, but modern software and hardware introduce increasingly complex optimization decisions.
Machine learning offers a way to improve selected parts of this process.
By analyzing program features, learning from compilation outcomes, and exploring optimization alternatives, learned models can help compilers make more informed decisions about function inlining, register allocation, optimization-pass selection, and hardware-specific code generation.
Frameworks such as LLVM MLGO demonstrate that this approach can be integrated into established compiler infrastructure. Research environments such as CompilerGym provide ways to investigate reinforcement learning for optimization-pass selection, while newer work on agentic compiler auto-tuning explores how models can interact with compilation environments and learn from measured outcomes.
However, learning-based compilation is not a replacement for compiler engineering. A model cannot be trusted to preserve program semantics merely because it predicts a favorable performance result. Correctness checks, reliable intermediate representations, reproducible benchmarking, and target-specific validation remain essential.
For software engineers, the most important shift is conceptual: compiler optimization can become more adaptive and data-driven without abandoning the deterministic mechanisms that make compilers reliable.
As software continues to run across increasingly diverse hardware platforms, learning-based compilers may help bridge the gap between general-purpose optimization rules and the specific performance requirements of individual applications.
The future of code optimization will likely combine the strengths of traditional compiler algorithms with machine learning models that learn when, where, and how particular transformations are most useful.
Frequently Asked Questions (FAQs)
1. What is a learning-based compiler?
A learning-based compiler uses machine learning models to guide selected compilation and optimization decisions. It can learn from program features, compilation outcomes, or performance measurements to improve choices such as function inlining, register allocation, and optimization-pass selection.
2. How is machine learning used in compiler optimization?
Machine learning models analyze information about programs and predict which optimization decisions are likely to produce better results. Depending on the system, models may use supervised learning, reinforcement learning, ranking, or regression to guide compiler behavior.
3. What is LLVM MLGO?
MLGO stands for Machine Learning Guided Optimization. It is a framework for integrating machine learning models into LLVM compiler optimization, including inlining-for-size and register-allocation-for-performance decisions.
4. What is compiler auto-tuning?
Compiler auto-tuning explores different compiler configurations or optimization-pass sequences to identify implementations that perform well for a particular program and hardware target. Machine learning can make this search more efficient by predicting promising configurations.
5. Can reinforcement learning optimize compiler passes?
Yes. Reinforcement learning can treat the current program representation as a state and compiler optimization passes as actions. The agent receives rewards based on outcomes such as instruction-count reduction, execution performance, or code-size improvement.
6. What is CompilerGym?
CompilerGym is a research framework that provides environments for studying compiler optimization using machine learning and reinforcement learning. It includes LLVM optimization tasks where agents can select passes and evaluate their impact on program representations.
7. Does a learning-based compiler replace traditional compiler algorithms?
No. Learning-based compilers generally use machine learning to guide selected decisions within existing compiler infrastructure. Traditional compiler analyses, transformation rules, semantic checks, and code-generation mechanisms remain essential.
8. How can machine learning improve function inlining?
A learned model can analyze features of the caller, callee, and call site to predict whether inlining is likely to improve code size or performance. This can provide more context-sensitive decisions than relying exclusively on fixed thresholds.
9. How is machine learning used in register allocation?
A learned model can help guide decisions about which live ranges should remain in physical registers and which should be evicted or spilled. The objective is to improve register-allocation decisions and reduce performance costs such as unnecessary memory operations.
10. What is the role of intermediate representation in learning-based compilers?
Intermediate representation provides a structured view of program operations that can be analyzed independently of the original source syntax. Machine learning models can use features or embeddings derived from IR to understand program structure and guide optimization decisions.
11. Can learning-based compilers optimize GPU programs?
Yes. Machine learning can help select GPU kernel configurations, tile sizes, memory layouts, and optimization strategies. These decisions can be evaluated against hardware-specific performance measurements to identify promising configurations.
12. What are the main challenges of learning-based compiler optimization?
Important challenges include preserving program correctness, obtaining diverse training data, generalizing across hardware, controlling inference overhead, measuring performance reliably, and maintaining compatibility between compiler versions and trained models.
13. How do learning-based compilers measure optimization quality?
They can use metrics such as execution time, throughput, instruction count, binary size, memory consumption, energy usage, and compilation time. The appropriate metric depends on the application's deployment requirements.
14. Can large language models optimize compiler code?
Large language models can assist with generating code, analyzing compiler transformations, suggesting optimization strategies, and interacting with compiler tools. However, proposed transformations must be compiled, tested, and benchmarked. Natural-language reasoning alone does not establish that an optimization is correct or faster.
15. Will machine learning replace compiler engineers?
No. Machine learning is more likely to change the tools and decision-making processes used by compiler engineers. Understanding program semantics, hardware behavior, optimization constraints, and correctness remains essential for designing and validating learning-based compiler systems.