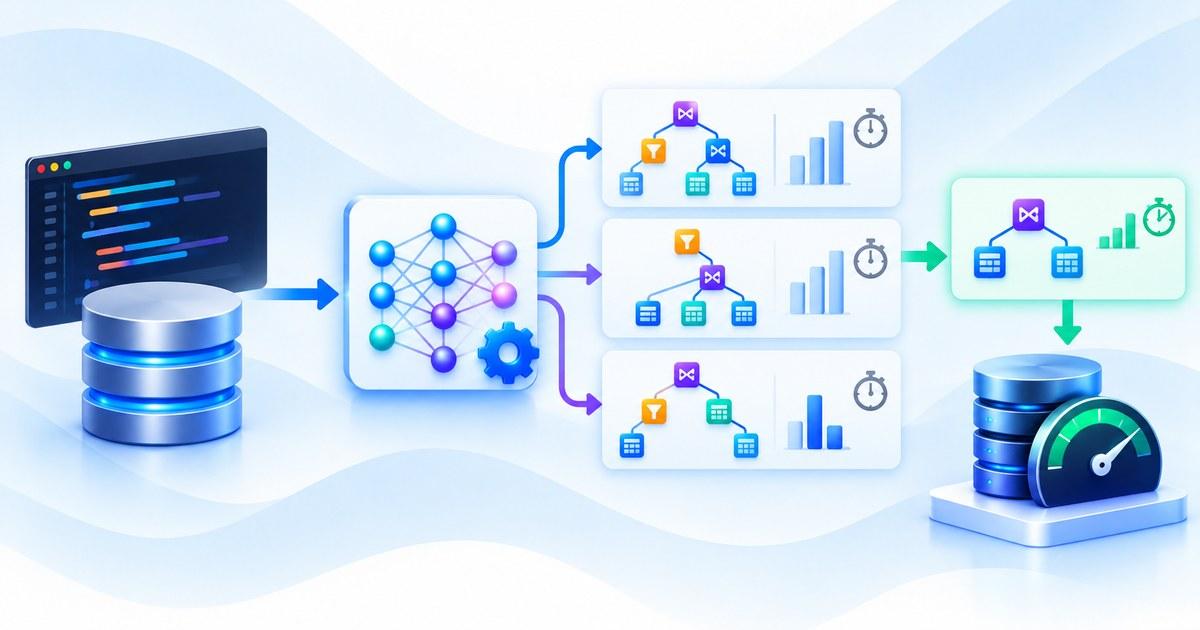
Section 1: Understanding ML Compilers and Why Model Execution Needs Optimization
From Trained Models to Executable Computation Graphs
Training a machine learning model produces learned parameters and a mathematical structure capable of transforming inputs into predictions, but this does not automatically mean that the model will execute efficiently on a production system. A neural network may contain matrix multiplications, activation functions, normalization operations, attention mechanisms, and tensor transformations that must be translated into executable instructions before the underlying hardware can perform the required computations. Although machine learning frameworks provide runtimes that execute these operations, the way they represent and schedule computation can influence kernel-launch overhead, memory consumption, data movement, and overall inference latency. ML compiler optimization addresses this gap by transforming a model's computational representation into an execution strategy that better matches the capabilities of the target hardware.
Most modern ML frameworks represent model computation as a sequence or graph of operations connected through tensors, which carry the intermediate values produced by one operation and consumed by another. For example, a neural network layer might multiply an input tensor by a weight matrix, add a bias term, apply an activation function, and pass the resulting tensor to the next layer, creating a dependency structure that determines which operations must execute before others. A compiler can analyze this representation to identify independent computations, recognize repeated operations, determine tensor shapes, and discover opportunities to combine or eliminate work without changing the intended behavior of the model. Instead of treating the model as a collection of isolated operations, the compiler examines how the entire computation fits together, allowing optimization decisions to account for the relationships between individual operators and their intermediate results.
The distinction between a trained model and an optimized executable becomes particularly important when deploying models into high-throughput inference services, where small inefficiencies can accumulate across millions of requests. A model that performs acceptably in a development environment may execute less efficiently when deployed with small batch sizes, strict latency requirements, limited memory, or a hardware platform that supports only certain optimized operations. Compilation can improve these workloads by simplifying the computation graph, lowering high-level operations into more efficient implementations, planning memory use, and generating code suited to the execution environment. However, the benefits depend on the model architecture, input characteristics, compiler capabilities, and target hardware, making measurement of the compiled workload essential before claiming a practical performance improvement.
How ML Compilers Analyze Graphs, Operators, and Tensor Dependencies
ML compilers begin their optimization process by analyzing the computational graph and determining how operations depend on one another, what tensors they consume, and which values must remain available throughout execution. This analysis allows the compiler to distinguish operations that must follow a specific order from those that can potentially execute independently, while tensor-shape information helps determine the dimensions, memory requirements, and supported implementations of individual operations. Static shapes can enable more aggressive specialization because the compiler knows important dimensions in advance, whereas dynamic shapes may require runtime checks, flexible memory planning, or multiple specialized execution paths. Understanding these constraints allows the compiler to choose transformations that preserve the model's computational meaning while improving execution efficiency.
An important optimization opportunity arises when the compiler identifies operations that produce intermediate values that are never used by the model's final outputs. Dead-code elimination can remove such operations, while constant folding evaluates expressions whose inputs are known during compilation, reducing the amount of work required during inference. The compiler may also simplify redundant transformations, propagate known tensor properties, and eliminate unnecessary conversions when the resulting graph remains semantically equivalent. These changes can reduce the number of executed operations and the amount of intermediate data generated, although more substantial performance improvements often depend on how the remaining computation is mapped to the target hardware.
Dependency analysis also helps the compiler determine whether operations can be reordered, parallelized, combined, or scheduled to reduce the cost of moving data between computational stages. For example, two independent branches of a model may be eligible for concurrent execution, while operations along a dependency chain must respect their required order to preserve correct outputs. The compiler must consider data dependencies, supported operator implementations, tensor layouts, and memory constraints before applying these transformations, since a theoretically valid rearrangement may increase memory usage or produce less efficient execution on the actual processor. By analyzing computation at the graph level before generating executable instructions, ML compilers can identify optimization opportunities that would be difficult to discover by examining individual operations in isolation.
How Hardware Characteristics Influence Compiler Optimization Decisions
The effectiveness of ML compiler optimization depends heavily on the hardware that executes the generated workload, since processors differ in their instruction sets, memory bandwidth, parallel execution capabilities, numerical formats, and support for specialized operations. A computation that performs efficiently on a GPU may behave differently on a CPU or an accelerator designed for specific matrix operations, making it necessary for the compiler to consider the characteristics of the target platform when selecting kernels and scheduling work. For example, matrix multiplications may benefit from highly optimized accelerator instructions, while workloads dominated by small element-wise operations may be limited by memory movement or kernel-launch overhead instead of raw computational throughput. The same model can therefore require different compilation strategies to achieve efficient execution across different hardware environments.
Hardware-aware optimization may involve selecting suitable tensor layouts, using vectorized instructions, choosing compatible numerical precision, and organizing computations so that data can be reused efficiently within the available memory hierarchy. A compiler targeting a GPU may prioritize parallel execution, efficient kernel scheduling, and memory coalescing, whereas a CPU-oriented compiler may emphasize vectorization, cache locality, and suitable thread allocation. Specialized accelerators may offer substantial performance advantages for supported operators and precision formats, but workloads that depend on unsupported operations may require expensive fallback implementations or transfers between execution devices. These considerations demonstrate why compiler optimization must account for the actual workload and hardware capabilities rather than relying exclusively on the model's theoretical operation count.
The principles discussed in “Hardware-Aware Machine Learning: Designing Models Around the Compute They Run On” are particularly relevant because the computational structure of a model and the hardware executing it jointly determine practical performance. An ML compiler extends this hardware-aware approach by transforming an existing model's graph, selecting suitable operator implementations, and generating executable workloads that make better use of the target processor's capabilities. Nevertheless, optimization decisions must be validated through benchmarking because reducing theoretical computation or selecting a lower-precision representation does not guarantee lower latency, reduced energy consumption, or acceptable predictive quality under every workload.
Key Takeaway
ML compiler optimization bridges the gap between a trained model's computational graph and the executable workload that runs on production hardware. By analyzing operator dependencies, removing redundant computations, fusing compatible operations, planning memory usage, and generating hardware-specific implementations, compilers can reduce execution overhead without necessarily changing the model's learned parameters. Effective optimization ultimately depends on the interaction between graph structure, tensor characteristics, numerical requirements, runtime behavior, and hardware capabilities, making measured performance and output validation essential when determining whether a compiled model delivers meaningful improvements.
Section 2: Graph Optimization and Operator Fusion for More Efficient Execution
Constant Folding, Dead-Code Elimination, and Redundant Computation Removal
Once an ML compiler has analyzed a model's computation graph, it can simplify the graph by removing operations that do not contribute useful work during inference, reducing the number of computations and intermediate values the runtime must handle. Constant folding evaluates expressions whose inputs are known during compilation, allowing the compiler to replace those expressions with their results rather than repeatedly calculating them at runtime. For example, if a model contains a fixed arithmetic transformation involving constant tensors, the compiler may evaluate that transformation ahead of time and retain the resulting value, provided that the transformation is safe to perform and its numerical behavior remains acceptable. This approach can reduce runtime computation while simplifying the graph that subsequent optimization stages must process.
Dead-code elimination addresses a different problem by removing operations whose outputs cannot influence the model's required results. During model development, graph construction, or export, the computational representation may retain unused branches, intermediate values, or operations that no longer contribute to the final output, creating work that does not improve prediction quality. A compiler can trace dependencies backward from the required outputs and remove operations that are not needed, while related simplification passes can eliminate redundant casts, unnecessary tensor transformations, or repeated computations when equivalence can be established safely. These transformations are particularly useful in large models, where even modest reductions in repeated operations can decrease memory pressure and execution overhead across a high volume of inference requests.
However, graph simplification must preserve the semantics of the original model, including operation dependencies, observable outputs, and any behavior that affects execution correctness. Floating-point arithmetic does not always produce identical results when operations are reordered or combined, while stateful operations and runtime-dependent conditions may restrict which transformations are safe. Compiler implementations therefore apply optimization rules according to the operation's semantics and the available information about tensor shapes, data types, and execution constraints, ensuring that simplification does not introduce changes that exceed acceptable numerical tolerances or alter the model's intended behavior.
Operator Fusion and Kernel Fusion: Reducing Execution and Memory Overhead
Operator fusion combines compatible operations into a larger computational unit so that the runtime can avoid some of the overhead associated with launching separate kernels and materializing intermediate tensors. In a neural network, an element-wise bias addition may be followed by an activation function, with the result passed to another operation that consumes the same tensor, creating opportunities to execute several stages together rather than writing each intermediate result to memory. When the operations are fused effectively, intermediate values may remain in registers or other fast-access storage, reducing memory traffic and allowing the compiler to generate a more efficient execution sequence for the target hardware.
Kernel fusion is particularly important on GPUs and other accelerators, where launching many small kernels can introduce overhead that becomes significant when individual operations perform relatively little computation. Instead of launching independent kernels for several compatible operations, a compiler may generate one kernel that performs the combined computation, reducing launch count and potentially improving data reuse. Fusion can also reduce the need to write intermediate tensors to global memory and load them again in subsequent operations, which is beneficial for workloads where memory bandwidth, rather than arithmetic throughput, limits performance. These advantages depend on the operators involved and the size of the tensors, making it necessary to evaluate the proposed fusion against the characteristics of the actual workload.
Fusion does not guarantee faster execution, however, because combining too many operations can increase register usage, create larger kernels, reduce parallel occupancy, or interfere with an otherwise efficient scheduling strategy. Some operations also impose constraints that prevent fusion, particularly when they require global synchronization, have incompatible layouts, or depend on execution patterns that cannot be represented efficiently within a single kernel. Compilers must therefore balance reduced launch and memory overhead against the resource requirements of the fused implementation, using hardware-specific rules, cost estimates, and empirical tuning where appropriate. The principles discussed in “Efficient ML: How to Build High-Performance Models With Less Compute” are relevant here because removing unnecessary work and improving data reuse can deliver meaningful performance gains without necessarily increasing model size or computational capacity.
Tensor Layouts, Memory Planning, and Intermediate Representation Optimization
Efficient execution depends not only on which operations a model performs but also on how tensor data is arranged in memory and how intermediate values move between computational stages. Tensor layouts determine how elements are organized and accessed, affecting whether hardware can read data efficiently, use vectorized operations, and exploit suitable memory-access patterns. A layout that works well for one operator may be inefficient for another, so an ML compiler may transform layouts or insert conversions when the expected benefit outweighs the cost of those additional operations. These decisions become particularly important in convolutional networks, attention workloads, and other models where large tensors are repeatedly accessed by operations with different computational requirements.
Memory planning provides another optimization opportunity by analyzing the lifetime of intermediate tensors and identifying buffers that can safely share storage. If one tensor is no longer needed when another tensor must be created, the compiler may reuse the same memory region rather than allocating additional storage, reducing peak memory requirements and potentially allowing a larger workload to execute within the available device memory. This capability is valuable for deep networks that produce large intermediate activations, since excessive memory usage can cause allocation overhead, limit batch sizes, or trigger transfers between device memory and slower storage. Effective memory planning must still respect operation dependencies and tensor lifetimes, ensuring that a buffer is never overwritten while its contents remain necessary for an upcoming computation.
Intermediate representations, or IRs, provide a structured way for compilers to express computation at different levels of abstraction as a model progresses from a framework-level graph toward executable instructions. A compiler may use an initial representation to expose high-level mathematical operations, then lower them into more explicit tensor operations, hardware-oriented primitives, and target-specific instructions as optimization proceeds. This staged architecture allows different optimization passes to work at the level where they are most effective, coordinating graph simplification, layout transformations, memory planning, and kernel generation without requiring every transformation to understand the entire model's original framework representation. The effectiveness of these stages depends on the quality of the intermediate representation and the transformations supported by the compiler, particularly when different operators interact through shared tensors and memory resources.
Key Takeaway
Graph optimization improves ML execution by removing unnecessary operations, combining compatible kernels, reducing intermediate memory traffic, and selecting efficient tensor layouts and numerical representations. These transformations must account for hardware characteristics, memory constraints, operation dependencies, and numerical correctness, since fewer operations or lower-precision computation do not automatically guarantee faster execution or equivalent predictions. By measuring compiled performance and validating model outputs, engineering teams can determine which graph transformations deliver reliable improvements for their actual deployment workloads.
Section 3: Lowering, Code Generation, and Hardware-Specific Execution
Lowering Model Graphs Into Intermediate Representations and Executable Operations
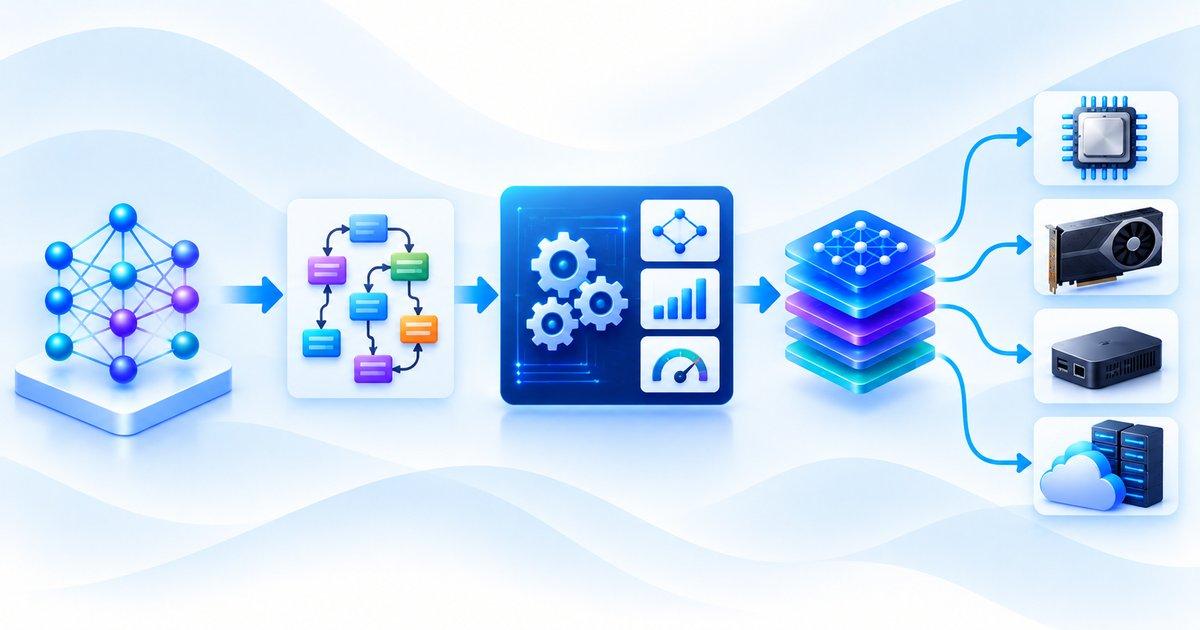
Once an ML compiler has optimized a model's computational graph, it must transform the high-level representation into operations that the target hardware can execute efficiently. This process, commonly called lowering, progressively converts abstract model operations into more explicit computational instructions while preserving their dependencies and intended behavior. A framework-level operation such as matrix multiplication may initially be represented as a single high-level operator, but subsequent compiler stages can introduce details about tensor layouts, data types, tiling strategies, memory access, and the implementation required by a particular processor. By exposing these details gradually, the compiler creates opportunities to apply optimizations at different levels without requiring the model developer to manually implement every low-level operation.
Intermediate representations provide the foundation for this transformation because they allow the compiler to describe computation at multiple levels of abstraction. A high-level representation may emphasize mathematical operations and tensor dependencies, while a lower-level representation can express loops, memory operations, hardware-specific primitives, and instructions that closely match the target architecture. Each representation enables different optimization passes, allowing the compiler to simplify the computational graph before focusing on instruction scheduling, memory access patterns, and machine-level execution. This layered approach also supports multiple hardware targets, since the same model representation can potentially be lowered through different implementation paths rather than requiring an entirely separate model definition for every processor.
The lowering process must preserve important constraints, including data dependencies, tensor dimensions, numerical behavior, and the execution semantics of individual operators. For example, an attention operation may require careful coordination among matrix multiplications, scaling, masking, and normalization, so transforming it into a sequence of lower-level operations must preserve the relationships that determine the model's output. Static shape information can enable more aggressive specialization when tensor dimensions are known at compilation time, whereas dynamic dimensions may require runtime guards, adaptable memory strategies, or specialized execution paths for different input shapes. By combining progressively lower-level representations with appropriate validation, ML compilers can translate high-level model descriptions into executable workloads while retaining opportunities for hardware-specific optimization.
Generating Optimized Kernels for CPUs, GPUs, and Specialized Accelerators
Code generation converts the compiler's optimized intermediate representation into instructions or executable kernels designed for a specific execution environment, making it a critical stage in translating theoretical optimization opportunities into measurable performance improvements. The same mathematical operation may have several valid implementations, with the fastest choice depending on tensor dimensions, data types, memory hierarchy, parallel execution capabilities, and the instructions supported by the target processor. A compiler therefore needs to select or generate implementations that match the characteristics of the workload, rather than assuming that one kernel design will perform equally well across CPUs, GPUs, and specialized ML accelerators.
On CPUs, code generation may prioritize vectorized instructions, cache locality, thread scheduling, and efficient execution of operations across multiple cores, allowing compatible computations to process several values simultaneously. GPU-oriented compilation typically places greater emphasis on large-scale parallelism, efficient memory access, thread organization, and kernel-launch overhead, particularly for models containing extensive matrix multiplications or other highly parallel operations. Specialized accelerators may provide dedicated matrix units or instructions for particular numerical formats, but their advantages depend on whether the compiled workload maps effectively to the operations the hardware supports. When a model contains unsupported operators or incompatible data layouts, fallback implementations and transfers between execution devices can offset some of the expected performance gains, requiring engineers to evaluate the complete execution path.
Kernel selection also depends on workload dimensions and execution conditions, because an implementation that performs well for large batches may be inefficient for small, latency-sensitive requests. A matrix multiplication with large dimensions may benefit from tiled execution and specialized hardware instructions, while a small operation may perform better with a simpler implementation that avoids excessive setup overhead. Compilers can use existing kernel libraries, generate specialized code, or combine predefined implementations with runtime selection strategies, depending on the architecture and supported toolchain. By matching kernel implementations to tensor characteristics and processor capabilities, code generation helps convert an optimized computation graph into executable instructions that use the available hardware efficiently.
Selecting Numerical Formats and Hardware-Compatible Execution Paths
Numerical formats influence both the computational cost and memory requirements of ML workloads because each representation determines how tensor values are stored and which arithmetic instructions can process them efficiently. Depending on the target hardware and model requirements, a compiler may select floating-point formats such as FP32, FP16, or BF16, or use supported integer formats for quantized computation, potentially reducing memory traffic and increasing throughput. These choices must account for differences in numerical range, precision, rounding behavior, and the capabilities of the relevant hardware, since a format that performs efficiently on one processor may be less advantageous on another.
Quantized execution can improve efficiency when the model and hardware support compatible lower-bit operations, although the benefits depend on the quantization method, selected operators, and the overhead associated with conversions or fallback implementations. The engineering considerations described in “Quantization Explained: How AI Models Become Faster and Cheaper to Run” are directly relevant because numerical representation affects the kernels available to the compiler, the amount of memory required, and the achievable execution throughput. A compiler must therefore determine whether quantized operations can be applied consistently across the computational graph or whether particular stages require higher precision to preserve acceptable numerical behavior.
Hardware-compatible execution also requires the compiler to handle unsupported operations, incompatible layouts, and data-type transitions without introducing excessive overhead. If an accelerator provides highly efficient kernels for matrix multiplication but lacks a suitable implementation for another operator, the runtime may need to execute that operation through a different kernel or device, potentially requiring additional memory transfers and synchronization. These cases make operator coverage and execution-path compatibility important considerations when selecting a compilation target, since isolated measurements of a single optimized kernel may not reflect the performance of the complete model.
Validation must accompany numerical and hardware-specific optimization because changes in operation order, precision, and implementation can introduce differences in model outputs even when the compiler intends to preserve the original computation. Engineers should compare compiled outputs with an appropriate baseline using numerical tolerances and task-level quality metrics, while also measuring end-to-end latency, throughput, memory consumption, and hardware utilization on representative inputs. By coordinating numerical-format selection, kernel compatibility, and output validation, ML compiler systems can pursue faster execution without assuming that lower precision or more specialized hardware necessarily delivers acceptable results for every model.
Key Takeaway
Lowering and code generation transform optimized model graphs into executable operations tailored to the target hardware, while memory planning, tiling, scheduling, and numerical-format selection determine how efficiently those operations run. The effectiveness of these transformations depends on tensor dimensions, memory behavior, supported instructions, hardware compatibility, and the numerical requirements of the model. By benchmarking complete execution paths and validating model outputs after compilation, engineering teams can determine whether hardware-specific code generation produces practical performance improvements without compromising predictive quality.
Conclusion: Transforming Machine Learning Models Into Faster Executable Workloads
ML compiler optimization plays a critical role in bridging the gap between a model's mathematical computation and the executable workload that runs on production hardware. Although modern machine learning frameworks simplify model development and provide convenient execution environments, their general-purpose runtimes may introduce overhead through repeated kernel launches, unnecessary tensor transformations, inefficient memory access, and operations that are not ideally matched to the target processor. ML compilers address these challenges by analyzing computational graphs, simplifying operations, combining compatible kernels, and generating executable instructions that make more efficient use of available computing resources.
Graph optimization provides an important starting point by eliminating redundant computations, evaluating constant expressions, and identifying operations that do not contribute to the required outputs. Operator fusion can further reduce execution overhead by combining compatible operations, while tensor layout transformations and memory planning help reduce data movement and unnecessary intermediate storage. These techniques must be coordinated carefully because an optimization that reduces the number of operations can still perform poorly if it increases register pressure, limits parallel execution, or creates additional synchronization requirements. Effective compilation therefore depends on understanding the relationships among graph structure, tensor dimensions, memory behavior, and hardware characteristics rather than assuming that fewer operations always produce faster execution.
Lowering and code generation translate the optimized graph into instructions and kernels that target CPUs, GPUs, and specialized accelerators, allowing the compiler to exploit processor-specific capabilities. Intermediate representations provide the structure needed to apply different optimization passes, while scheduling, tiling, vectorization, and numerical-format selection influence how efficiently the final executable uses computational and memory resources. However, hardware-specific optimizations must preserve the model's intended computational behavior, particularly when fusion, operation reordering, or reduced-precision arithmetic introduces numerical differences. Engineers should therefore validate compiled outputs against appropriate reference implementations and measure task-level quality alongside execution performance.
Benchmarking is essential for determining whether compilation delivers practical improvements under representative production conditions. Measurements should include end-to-end inference latency, throughput, memory consumption, hardware utilization, and compilation overhead, with particular attention to tail latency for time-sensitive applications. Profiling can reveal whether a workload is limited by arithmetic throughput, memory bandwidth, kernel-launch overhead, or data transfers, helping teams select transformations that address the actual bottleneck rather than optimizing operations that have little influence on overall performance. Compilation caches, dynamic-shape policies, autotuning, and runtime integration must also be managed carefully to ensure that optimizations remain effective beyond isolated benchmark environments.
Production deployment adds another layer of responsibility because compiler versions, model architectures, hardware configurations, and incoming workloads may change over time. Versioned compilation artifacts, reproducible builds, automated regression tests, staged deployment, and rollback procedures help engineering teams identify performance regressions while preserving the ability to recover a previously validated executable. Continuous monitoring should track performance and resource utilization while evaluating model quality when appropriate, ensuring that a faster implementation does not introduce unacceptable numerical differences or operational problems.
Ultimately, ML compiler optimization is not simply an exercise in generating fewer instructions or reducing theoretical computational complexity; it is the engineering process of transforming a model into an executable workload that performs efficiently under real deployment constraints. The strongest results come from coordinating graph optimization, kernel generation, memory planning, numerical validation, and hardware-aware execution with systematic benchmarking and production monitoring. By measuring actual improvements and preserving correctness throughout the compilation lifecycle, engineering teams can reduce inference latency, improve throughput, and use available computing resources more effectively without compromising the reliability of their machine learning applications.
Frequently Asked Questions
1. What Is ML Compiler Optimization?
ML compiler optimization is the process of transforming a machine learning model's computational representation into an executable workload that uses computing resources more efficiently. It includes graph simplification, operator fusion, memory planning, intermediate representation transformations, kernel generation, and hardware-specific scheduling, with the objective of improving execution performance while preserving the model's intended behavior.
2. How Does an ML Compiler Differ From a Machine Learning Framework?
A machine learning framework provides tools for defining, training, and executing models, including tensor operations, automatic differentiation, and runtime support, whereas an ML compiler focuses on transforming computations into efficient executable implementations. Although many frameworks include compilation capabilities, a compiler typically performs additional graph analysis, lowering, optimization, and code generation to improve how the model executes on a particular hardware target.
3. What Is an Intermediate Representation in an ML Compiler?
An intermediate representation, or IR, is a structured description of model computation that allows a compiler to analyze and transform operations before generating executable code. High-level representations may describe mathematical operations and tensor dependencies, while lower-level representations expose memory access, loops, hardware primitives, and instructions, enabling different optimization passes to operate at the appropriate level of abstraction.
4. How Does Computational Graph Optimization Improve Model Performance?
Computational graph optimization improves model performance by identifying redundant work, eliminating unused operations, evaluating constants during compilation, and simplifying the relationships between operators. These transformations can reduce the amount of computation and intermediate data required during execution, although their actual performance benefits depend on the model architecture, hardware, tensor dimensions, and runtime characteristics.
5. What Is Operator Fusion, and Why Does It Matter?
Operator fusion combines compatible operations into a larger computational unit, potentially reducing kernel launches, intermediate tensor materialization, and memory transfers. For example, combining a bias addition with an activation function may allow the intermediate value to remain in fast-access storage, although excessive fusion can increase register pressure or reduce parallel occupancy, making hardware-aware evaluation essential.
6. What Is the Difference Between Graph Optimization and Kernel Optimization?
Graph optimization operates on the broader computational structure of a model, removing unnecessary operations, reorganizing compatible computations, and identifying opportunities to combine operators. Kernel optimization focuses more directly on how an individual operation or fused group executes, improving factors such as memory access, tiling, vectorization, thread organization, and instruction selection, with both levels contributing to overall performance.
7. How Do ML Compilers Generate Hardware-Specific Code?
ML compilers lower model operations into intermediate representations and then select or generate implementations suited to the target processor's capabilities. Depending on whether the target is a CPU, GPU, or specialized accelerator, code generation may emphasize vectorized instructions, parallel execution, memory coalescing, specialized arithmetic units, or efficient scheduling, with the best implementation depending on the workload and available hardware features.
8. How Do Tensor Layouts and Memory Planning Affect Execution Speed?
Tensor layouts influence how efficiently processors access and reuse data, while memory planning determines when intermediate tensors are allocated, retained, and released. By choosing suitable layouts, reusing buffers when tensor lifetimes permit, and reducing unnecessary data transfers, compilers can reduce memory overhead and improve execution efficiency, particularly for workloads that generate large intermediate activations or depend heavily on memory bandwidth.
9. How Does Quantization Interact With Compiler Optimization?
Quantization represents model values using lower-bit numerical formats, potentially reducing memory consumption and enabling faster arithmetic on hardware that supports efficient quantized operations. An ML compiler can use these formats to select specialized kernels and optimize data movement, but quantization may introduce numerical differences, conversion overhead, or unsupported operations, so performance and predictive quality must be validated together.
10. What Is Automatic Kernel Generation?
Automatic kernel generation is the process of producing executable implementations for computational operations through compiler transformations, code-generation techniques, or specialized kernel-generation systems. Rather than requiring developers to manually implement every operation for each hardware target, these systems can generate or specialize kernels according to tensor dimensions, numerical formats, execution requirements, and processor capabilities, although the quality of the result depends on the compiler's supported transformations and optimization strategies.
11. How Do ML Compilers Optimize Models With Dynamic Input Shapes?
Models with dynamic input shapes require compilation strategies that can accommodate changing tensor dimensions without assuming a single fixed configuration. A compiler may generate a general executable, create specialized versions for frequently encountered shapes, or use runtime checks to select an appropriate execution path, with each strategy presenting trade-offs among compilation time, cache size, flexibility, and steady-state performance.
12. How Should Engineers Benchmark Compiled ML Models?
Engineers should compare compiled and reference implementations using representative input shapes, batch sizes, hardware configurations, and execution conditions, while separating compilation and initialization costs from steady-state inference where appropriate. Measurements should include latency distributions, throughput, memory consumption, hardware utilization, and profiling data, allowing teams to identify the actual performance bottlenecks and verify that an apparent improvement persists under realistic workloads.
13. Can Compiler Optimization Change Model Accuracy?
Compiler optimization can introduce numerical differences when operations are fused, reordered, or executed using lower-precision arithmetic, even when the transformations are intended to preserve the original computation. Engineers should compare compiled outputs against a suitable reference using numerical tolerances and evaluate task-level metrics such as accuracy, ranking quality, or regression error, ensuring that performance improvements do not produce unacceptable changes in model behavior.
14. What Causes Performance Regressions After Compilation?
Performance regressions can occur when compiler versions, optimization passes, model architectures, tensor shapes, runtime libraries, or hardware configurations change, altering the behavior of the generated executable. Inefficient fusion, increased register pressure, memory bottlenecks, unsuitable kernel selection, or repeated compilation can also reduce performance, making versioned artifacts, reproducible benchmarks, profiling, and regression testing important tools for identifying and correcting the underlying problem.
15. When Should an Engineering Team Invest in ML Compiler Optimization?
An engineering team should consider compiler optimization when model execution latency, throughput, memory usage, or infrastructure costs are significant constraints and profiling indicates that the existing execution path contains meaningful optimization opportunities. The investment is most useful when representative benchmarks demonstrate that graph transformations, kernel selection, memory planning, or hardware-specific code generation provide measurable benefits that justify compilation complexity, validation requirements, and ongoing maintenance.