Section 1: Understanding Reinforcement Learning from Verifiable Rewards
Why AI Models Need Objective Feedback
A language model learns to generate text by predicting tokens based on patterns in its training data. During pretraining, it typically learns by minimizing a next-token prediction loss. This process helps it acquire language structure, factual associations, coding patterns, and other statistical relationships.
However, predicting plausible text is not the same as consistently solving a problem correctly. A model may generate a mathematically convincing explanation that contains an arithmetic error. It may produce code that looks syntactically valid but fails when executed. It may also generate a logical argument that appears coherent while contradicting one of its premises.
Supervised fine-tuning can improve these behaviors by exposing the model to examples of desired responses. The model learns from demonstrations created by humans or generated through other data pipelines. Although this is useful, the quality of the result depends heavily on the examples available. Producing high-quality demonstrations for difficult reasoning problems can require substantial expert effort.
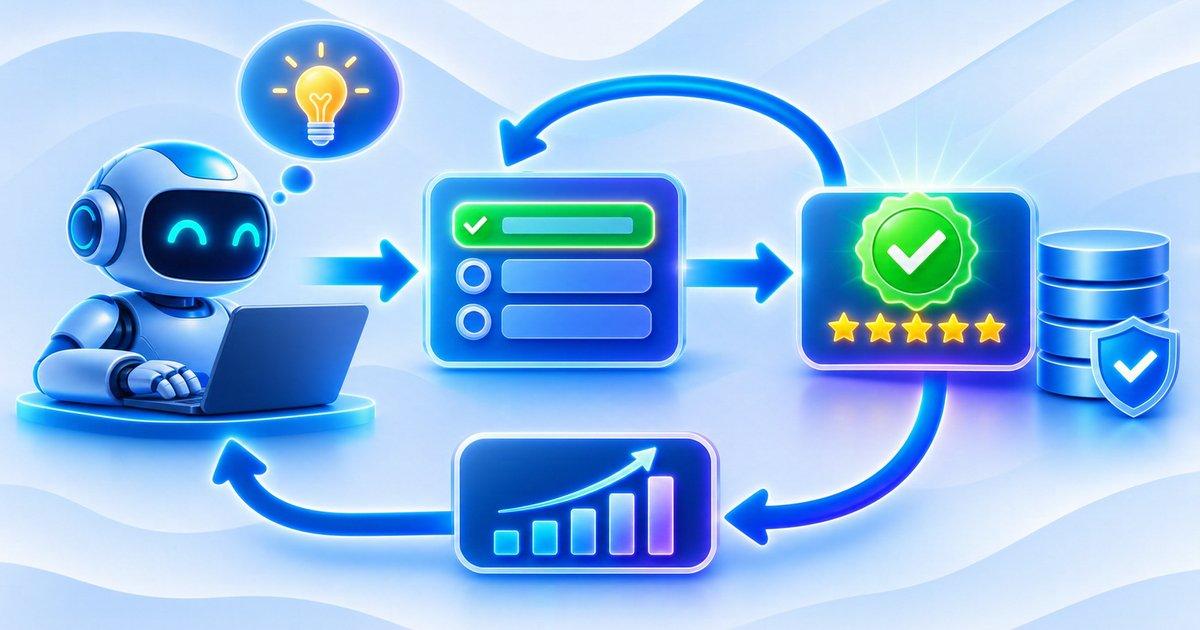
Reinforcement learning introduces a different training mechanism. Instead of learning only from a reference response, the model generates candidate outputs and receives feedback based on their outcomes. The optimization process then adjusts the model to make higher-reward outputs more likely.
The fundamental reinforcement learning objective can be represented as:
[
J(\theta)=
\mathbb{E}{x\sim D,;y\sim\pi\theta(\cdot|x)}
[R(x,y)]
]
Here, (x) is a training prompt, (y) is a generated response, (\pi_\theta) is the language model's policy, and (R(x,y)) is the reward assigned to the response.
The key engineering question is how to calculate (R(x,y)).
In preference-based training, a human evaluator or reward model may estimate which response is better. In RLVR, an automated verifier evaluates whether the response satisfies a predefined condition. This is particularly useful when the task has a clear correctness criterion.
For example, if a model is asked to calculate the determinant of a matrix, the system can compare its final result with a verified mathematical answer. If the model is asked to implement a function, a test harness can execute the generated code against expected input-output pairs.
The advantage is that feedback becomes repeatable and scalable. The same verification procedure can evaluate thousands or millions of generated candidates without requiring a human to inspect every response.
Objective feedback does not automatically produce intelligent behavior. It gives the learning algorithm a measurable target. The model must still discover which generation strategies produce outputs that satisfy that target.
What Is Reinforcement Learning From Verifiable Rewards?
Reinforcement Learning From Verifiable Rewards is a post-training approach in which a model is optimized using rewards produced by an external verification process.
The essential distinction is the source of the reward. Instead of relying primarily on a human preference score or a learned model that predicts response quality, RLVR uses a checker that evaluates a property of the generated output.
A simplified reward function is:
[
R(x,y)=
\begin{cases}
1, & \text{if }V(x,y)=\text{pass}\
0, & \text{otherwise}
\end{cases}
]
Here, (V) is the verifier. The binary reward is illustrative; practical systems can use partial rewards, penalties, or multiple verification conditions.
Consider a coding problem that asks a model to implement a function for finding the longest increasing subsequence. The model generates a candidate program. The verifier compiles it, executes it against public tests and hidden tests, and checks whether the returned results match the expected outputs. The model receives a positive reward only if the implementation satisfies the required conditions.
A mathematics task can follow a similar process. The model generates a solution and a final answer. The verifier extracts the answer, normalizes its representation, and compares it with a trusted reference or checks mathematical equivalence using a symbolic engine.
The process can be repeated with multiple candidate responses. The reinforcement learning algorithm uses the resulting rewards to update the model's policy.
RLVR is particularly useful for reasoning tasks because it separates the correctness of the final outcome from the subjective quality of the explanation. A model may use an unconventional solution strategy, but if the result passes a reliable verifier, it can still receive positive feedback.
This does not mean that every reasoning step is necessarily correct. A final answer can be correct because of a lucky guess, an accidental cancellation of errors, or an invalid explanation that happens to produce the right result. The verifier must therefore be designed around the intended learning objective.
The distinction between verifiable outcomes and verifiable reasoning is important. Outcome verification checks whether the final result is correct. Process verification checks whether the intermediate steps follow accepted rules. Some applications need only the former, while high-assurance mathematical or scientific workflows may require both.
The ability to adapt model behavior using feedback is also closely connected to the broader development of adaptive AI systems. Understanding how models respond to changing inputs, evolving requirements, and new feedback signals provides useful context for RLVR. Explore "Adaptive ML Systems: How Models Respond When the Environment Changes" to understand how adaptive learning strategies help deployed models respond to changing environments.
What Makes a Reward Verifiable?
A reward is verifiable when the system can evaluate the relevant property of an output using a sufficiently reliable and repeatable procedure.
The strongest examples involve deterministic conditions. A program either passes a specified unit test or fails it. A mathematical expression either satisfies a symbolic equivalence check under the relevant assumptions or does not. A formal proof either passes the proof assistant's verification rules or fails.
However, verification is broader than comparing strings or checking whether a program compiles. A robust verifier may need to parse the output, normalize its representation, execute code in an isolated environment, evaluate hidden test cases, check resource limits, and validate the expected behavior.
For example, a code verifier that checks only compilation is weak. A program can compile successfully while returning incorrect results. A stronger verifier executes the program against representative test cases, including boundary conditions and adversarial inputs.
Similarly, a mathematics verifier that compares raw strings may incorrectly reject equivalent answers. The fractions (1/2) and (0.5) represent the same value, but a simplistic string comparison would treat them as different. A reliable mathematical verifier needs appropriate normalization or symbolic comparison.
Verifiability also has a scope. A unit test can establish that a program passes the tested cases, but it cannot prove that the program is correct for every possible input unless the test procedure provides stronger guarantees. A formal proof checker can verify a proof within its formal system, but the correctness of the specification and the assumptions still matter.
Engineers must therefore distinguish between an objective verifier and a perfect verifier. The former uses explicit rules; the latter would never make an incorrect judgment. Real systems can have objective rules and still produce false positives or false negatives.
A reliable RLVR pipeline begins by defining exactly what success means, which conditions can be checked automatically, and what limitations remain outside the verifier's scope.
Key Takeaway
RLVR trains models using feedback generated by objective verification procedures rather than relying exclusively on human preferences or learned reward estimates. It is particularly effective for tasks such as mathematics, coding, and formal reasoning, where correctness can be evaluated through explicit rules. However, the reward is only as trustworthy as the verifier and the specification behind it. A deterministic checker can still validate the wrong property if the engineering requirements are incomplete.
Section 2: How Engineers Build an RLVR Training Pipeline
Designing the Task Dataset and Verification Environment
An RLVR pipeline begins with a collection of prompts or tasks for which the expected success criteria can be defined. The dataset must provide sufficient diversity to encourage the model to develop reusable problem-solving capabilities rather than memorizing a narrow set of examples.
For mathematics, the dataset may contain algebra, number theory, geometry, combinatorics, calculus, and other reasoning problems. Coding datasets may include algorithmic challenges, function implementation, debugging, and software engineering tasks. Formal reasoning datasets may contain logic problems, theorem-proving challenges, or structured constraint-satisfaction problems.
The quality of the dataset matters because reinforcement learning optimizes behavior on the distribution of prompts it receives. If the dataset contains mostly simple arithmetic problems, the model may improve on those tasks without becoming substantially better at complex mathematical reasoning.
Each task should have an associated verification specification. A coding problem may include a compiler configuration, a test harness, expected input-output behavior, execution limits, and security restrictions. A mathematical problem may include a canonical answer, accepted equivalent representations, and constraints on the variables.
The dataset should also distinguish between training and evaluation problems. If the model repeatedly encounters the same questions during optimization, it may learn shortcuts that improve measured training reward without developing robust generalization.
A strong evaluation set should contain held-out tasks and, where possible, different problem structures from those used during training. For coding, hidden tests can help identify solutions that memorize public examples. For mathematics, equivalent problem formulations can help determine whether the model learned a reusable approach or merely memorized specific answers.
Data preparation must also address ambiguity. A problem with multiple valid solutions should not be evaluated using a verifier that accepts only one representation. Similarly, a coding task should not unintentionally reward implementation details that are unrelated to the intended behavior.
The engineering team should define the task specification before optimizing the model. Otherwise, the reinforcement learning process may discover a way to maximize the implemented reward while failing to satisfy the actual user requirement.
Building Verifiers for Mathematics, Code, and Logical Reasoning
The verifier is the central component of an RLVR system. It transforms a generated response into a reward signal that can be used by the optimization algorithm.
For mathematics, verification may involve parsing the final answer, evaluating numerical equivalence, simplifying symbolic expressions, or checking a formal derivation. A symbolic mathematics system can compare expressions while accounting for algebraic transformations. For more advanced mathematical tasks, formal proof systems can verify whether a proposed proof follows from specified axioms and inference rules.
For programming, the verifier usually involves several stages. The generated code is extracted from the response, parsed, compiled or interpreted, and executed in a controlled environment. The program is then evaluated against test cases. Additional checks may inspect runtime, memory consumption, output formatting, and security constraints.
A simplified coding reward might be:
[
R_{\text{code}} =
\frac{1}{N}
\sum_{i=1}^{N}
\mathbb{1}
\left[
\operatorname{Test}_i(c)=\text{pass}
\right]
]
Here, (c) is the generated code and (N) is the number of tests. This produces a partial reward based on the proportion of tests passed. A stricter verifier may require every test to pass before assigning a positive outcome reward.
For logical reasoning, a verifier may check whether a conclusion follows from a set of premises, whether a constraint-satisfaction assignment is valid, or whether a generated proof can be accepted by a formal system.
The verifier should be designed to evaluate behavior rather than superficial appearance. A program should not receive a high reward simply because it contains expected keywords. A mathematical response should not pass because it reproduces a known answer without satisfying the problem's assumptions.
Security is equally important. Generated code must be treated as untrusted input. Execution should occur in an isolated environment with restricted filesystem access, limited network access, CPU and memory quotas, execution timeouts, and controlled dependencies. The verifier itself should not expose training infrastructure to arbitrary model-generated commands.
A useful verifier also produces diagnostic information. Although the reinforcement learning algorithm may consume a scalar reward, engineers benefit from knowing whether a failure resulted from compilation, a specific test case, a timeout, an invalid output format, or a resource violation. This information supports debugging and improvement of the training environment.
Policy Optimization With GRPO and PPO
After candidate responses receive rewards, the model needs an optimization algorithm to learn from the feedback. Two important algorithms in this area are Proximal Policy Optimization (PPO) and Group Relative Policy Optimization (GRPO).
PPO is a policy-gradient algorithm that attempts to improve a policy while preventing excessively large updates. In language model training, the policy represents the probability distribution over the next token given the prompt and previously generated tokens.
A simplified PPO objective uses a probability ratio:
[
r_t(\theta)=
\frac{\pi_\theta(a_t|s_t)}
{\pi_{\theta_{\text{old}}}(a_t|s_t)}
]
The clipped policy objective is commonly expressed as:
[
L^{CLIP}(\theta)=
\mathbb{E}_t
\left[
\min
\left(
r_t(\theta)A_t,
\operatorname{clip}(r_t(\theta),1-\epsilon,1+\epsilon)A_t
\right)
\right]
]
Here, (A_t) represents the advantage estimate, while (\epsilon) controls the clipping range. PPO commonly uses a value function or critic to estimate expected future rewards and calculate advantages.
GRPO takes a different approach. Rather than training a separate value model, it samples a group of responses for the same prompt and estimates advantages using their relative rewards.
A simplified group-relative advantage can be written as:
[
A_i =
\frac{R_i-\operatorname{mean}(R_1,\ldots,R_G)}
{\operatorname{std}(R_1,\ldots,R_G)+\epsilon}
]
Here, (R_i) is the reward for response (i), and (G) is the number of sampled responses in the group.
This allows the model to compare candidate responses against other responses to the same prompt. Responses with better-than-average rewards receive positive advantages, while weaker responses receive negative advantages.
GRPO became especially prominent through DeepSeekMath and DeepSeek-R1. The DeepSeek-R1 research describes its use of GRPO with rule-based accuracy and formatting rewards for reasoning tasks. The approach avoids maintaining a separate critic model, although the overall training process still requires substantial compute for generating and evaluating candidate responses.
GRPO is not synonymous with RLVR. RLVR describes the source of the reward, while GRPO is an optimization algorithm. An RLVR pipeline can use PPO or other policy optimization approaches, depending on the training architecture and requirements.
Efficient reinforcement learning also depends on controlling training costs while maintaining model performance. Generating multiple candidate responses, executing verification environments, and performing repeated optimization steps can require substantial computational resources. Engineers can explore related optimization strategies in "Efficient ML: How to Build High-Performance Models With Less Compute", which examines techniques for improving machine learning efficiency without unnecessarily increasing compute requirements.
Key Takeaway
A practical RLVR pipeline requires a well-defined task dataset, a reliable verification environment, multiple candidate generations, reward calculation, and a policy optimization algorithm. GRPO is particularly relevant because it compares groups of responses without requiring a separate critic model, while PPO provides a more conventional policy-gradient alternative. The most important engineering dependency is the verifier: if it evaluates the wrong property or produces unreliable results, the optimization algorithm will faithfully learn the wrong behavior.
Section 3: Applications and Engineering Use Cases of RLVR
Mathematical Reasoning and Scientific Problem Solving
Mathematics is one of the strongest application areas for RLVR because many mathematical tasks have objectively checkable outcomes. An answer can often be evaluated using numerical computation, symbolic algebra, or formal proof verification.
A model trained on mathematical problems can generate multiple candidate solutions and receive rewards based on whether the final answer satisfies the problem. This allows the model to explore alternative approaches without requiring a human to write a complete solution for every training example.
The process is especially useful for problems that require multiple reasoning steps. A model may need to identify relevant variables, select an appropriate theorem, transform an expression, and calculate a final result. Reinforcement learning can increase the likelihood of response patterns that lead to verified answers.
However, checking the final answer is not equivalent to checking the entire derivation. A model might produce an incorrect intermediate step but accidentally reach the correct final result. Conversely, a correct mathematical solution might be rejected because the verifier does not recognize an equivalent expression.
More sophisticated systems can combine outcome verification with symbolic checking or formal proof tools. A proof assistant can verify a derivation under explicit assumptions, providing stronger guarantees than a simple final-answer comparison.
Scientific problem solving creates additional opportunities. Some problems can be evaluated through numerical simulation, physical constraints, or known conservation laws. A model might propose a solution to an optimization problem, and an external solver could determine whether it satisfies the constraints.
The difficulty is that scientific tasks often contain uncertainty, approximations, and model assumptions. A simulation result may be numerically plausible without representing the real physical system accurately. Therefore, scientific RLVR requires careful validation of the simulation environment and the assumptions used to define correctness.
The broader opportunity is to train models that can use tools, perform calculations, and verify the results of their own problem-solving process. Instead of relying only on text generation, the model learns to interact with external systems that provide measurable feedback.
Software Engineering, Code Generation, and Automated Debugging
Software engineering is another natural application because code can be executed and tested. A generated program can be evaluated against unit tests, integration tests, type checks, static analysis rules, and other automated verification mechanisms.
For example, an AI model may receive a specification to implement a function that validates user input. It generates candidate implementations, and the verifier executes them against valid inputs, invalid inputs, boundary conditions, and adversarial cases. The reward reflects how successfully each implementation satisfies the specification.
This is more informative than evaluating code only by its appearance. A program that looks elegant but fails edge cases should not receive the same reward as one that correctly implements the required behavior.
RLVR can also support debugging. A model can receive a failing test, inspect the relevant code, propose a patch, and execute the test suite again. Successful patches receive positive feedback, while unsuccessful patches are penalized.
The same approach can extend to repository-level engineering tasks. A model may need to modify several files, update dependencies, satisfy interface requirements, and ensure that existing tests continue to pass. The verifier can run the relevant build and test commands in a controlled environment.
However, passing a test suite does not prove that software is fully correct. Tests cover only the behaviors they specify. A model can overfit to visible test cases, introduce security vulnerabilities, or break functionality that is not included in the evaluation suite.
Strong code-verification environments therefore combine multiple checks. Unit tests establish expected behavior for individual components. Integration tests examine interactions. Static analysis can identify certain classes of defects. Security scanners can detect known vulnerability patterns, while sandbox restrictions limit the consequences of unsafe generated code.
RLVR can make AI-generated software more reliable when the verifier represents meaningful engineering requirements. It should not be interpreted as a guarantee that a model-generated patch is safe to merge without code review and broader testing.
The connection to production engineering is direct: an AI coding model can generate candidate implementations, while the same automated quality gates used by software teams provide objective feedback. The model learns to optimize for measurable behavior rather than merely producing code that appears plausible.
Enterprise Reasoning, Data Analysis, and Domain-Specific Applications
Enterprise systems often contain tasks that appear subjective but include measurable components. Data analysis, financial calculations, configuration management, and operational workflows can all provide opportunities for verifier-based training.
A data analysis agent may be asked to calculate a revenue metric from a dataset. The verifier can execute the generated SQL query or Python code and compare the resulting value with an independently computed reference. A financial calculation task may be checked against accounting rules, numerical tolerances, and defined business constraints.
In configuration management, a model may generate infrastructure configuration files. A verifier can parse the files, validate their schemas, run policy checks, and confirm whether the configuration satisfies specified requirements.
Domain-specific systems can also use simulation environments. An industrial planning agent might generate a production schedule, which is evaluated against capacity limits, delivery constraints, and optimization objectives. A network-management agent may propose configuration changes that are tested in a simulator before being applied to a live environment.
The important principle is that a task becomes suitable for RLVR when its required outcome can be evaluated through a sufficiently trustworthy procedure. It does not have to be a mathematics problem or a coding challenge.
Nevertheless, many enterprise objectives contain subjective or incomplete requirements. A financial report may be numerically correct but poorly communicated. A customer-support response may follow company policy but fail to address the customer's concern. A strategic recommendation may satisfy all explicit constraints while being commercially impractical.
These tasks may require hybrid feedback. Verifiable rewards can evaluate measurable requirements, while human preferences or carefully designed reward models assess qualitative dimensions.
For example, an enterprise reporting agent could receive objective rewards for numerical accuracy, correct source attribution, and schema compliance. A separate preference signal could evaluate readability and usefulness. Keeping these reward components distinct makes it easier to diagnose where the system succeeds or fails.
This approach also connects to production ML infrastructure. Data pipelines, test environments, and monitoring systems must reliably supply the information needed to evaluate model-generated work. Teams can draw on engineering practices described in "ML Data Pipelines for Software Engineers: From Event Streams to Model-Ready Data" when building the data foundations for these training systems.
Key Takeaway
RLVR extends beyond mathematical reasoning and code generation. Any task with a reliable, measurable success condition may be a candidate, including tool use, database operations, data analysis, configuration validation, and simulated workflows. The strongest applications use verifiers that evaluate real task outcomes rather than superficial patterns. For tasks with subjective dimensions, objective rewards should be combined with other feedback mechanisms instead of being treated as a complete measure of quality.
Conclusion
Reinforcement Learning from Verifiable Rewards is changing how engineers approach the post-training of reasoning-focused AI models. Instead of depending entirely on human preference judgments or learned reward models, RLVR uses automated verification systems to provide objective feedback on generated outputs.
The approach is particularly valuable for mathematics, programming, formal reasoning, and tool-using agents because these tasks often have measurable success conditions. A symbolic mathematics engine can verify an expression, a compiler and test suite can evaluate generated code, and a proof assistant can check a formal derivation.
Algorithms such as PPO and GRPO use the resulting rewards to optimize a model's policy. GRPO is especially relevant because it compares multiple candidate responses for the same prompt without requiring a separate value model. This makes it a practical choice for several reasoning-focused RLVR pipelines.
However, objective feedback is not the same as perfect feedback. A verifier can accept an incorrect solution, reject a correct one, or reward behavior that satisfies a narrow test while violating the actual requirement. Sparse rewards and limited exploration can also make training difficult, particularly when the model encounters problems beyond its current capabilities.
For software engineers and ML practitioners, RLVR creates an opportunity to combine model training with established engineering verification practices. Compilers, test harnesses, symbolic solvers, proof systems, and simulation environments can become part of the learning loop rather than remaining tools used only after model generation.
The most promising direction is not to use verifiers as simplistic pass-or-fail gates. It is to build reliable feedback environments that measure meaningful outcomes, expose useful diagnostic information, and support controlled optimization.
As AI systems become more capable of using tools and completing multi-step tasks, objective feedback will become increasingly important. The quality of the verifier, the design of the reward, and the reliability of the training infrastructure will play a central role in determining whether these models become genuinely more useful.
Frequently Asked Questions
1. What is Reinforcement Learning From Verifiable Rewards (RLVR)?
RLVR is a reinforcement learning approach in which a model receives rewards from automated verification systems that check whether generated outputs satisfy objective requirements. It is particularly useful for tasks such as mathematics, coding, and formal reasoning, where correctness can be evaluated through explicit rules or execution.
2. How does RLVR differ from RLHF?
RLHF generally uses human preferences, often represented through a learned reward model, to guide model optimization. RLVR uses automated verifiers such as compilers, unit tests, symbolic solvers, or proof checkers to produce rewards based on measurable outcomes.
3. What is a verifiable reward?
A verifiable reward is a training signal generated by a procedure that checks whether a model's output satisfies a defined condition. For example, a coding response may receive a positive reward when it passes a required test suite.
4. What is the role of a verifier in RLVR?
A verifier evaluates model-generated outputs and converts the result into a reward signal. Its reliability is critical because incorrect verification results can encourage the model to learn undesirable behavior.
5. What is GRPO, and why is it used in RLVR?
Group Relative Policy Optimization is a reinforcement learning algorithm that compares multiple responses generated for the same prompt and calculates their advantages relative to the group. It is useful in RLVR because it can optimize the model without requiring a separate critic or value model.
6. Is RLVR the same as GRPO?
No. RLVR describes the source of the reward, while GRPO describes an optimization algorithm. An RLVR training pipeline can use GRPO, PPO, or other suitable reinforcement learning methods.
7. How is RLVR used for code generation?
A model generates candidate code, which is compiled and executed against a test suite. The verifier evaluates whether the implementation satisfies the expected behavior and assigns rewards based on the results.
8. Can RLVR improve mathematical reasoning?
Yes. Mathematical problems often have answers that can be checked through numerical evaluation, symbolic equivalence, or formal proof systems. RLVR can use these checks to reinforce successful problem-solving behavior.
9. What is reward hacking in RLVR?
Reward hacking occurs when a model discovers a way to maximize the reward without satisfying the actual task objective. For example, a coding model may exploit a weak test suite by memorizing visible examples instead of implementing a correct general solution.
10. Does RLVR require human-labeled training data?
RLVR does not necessarily require human-labeled reasoning demonstrations for its reward signal. It still requires well-defined tasks, verification rules, and independent evaluation, and human expertise may be needed to design or validate those components.
11. What is the difference between outcome verification and process verification?
Outcome verification checks whether the final answer or result is correct. Process verification checks whether the intermediate steps follow valid rules, which is particularly important in applications that require trustworthy mathematical proofs or auditable reasoning.
12. What are the limitations of binary rewards?
Binary rewards provide a simple signal but can be sparse, especially when a model rarely generates correct responses. They can also fail to distinguish between partially correct and completely incorrect outputs, making exploration and optimization more difficult.
13. Can RLVR be used to train AI agents?
Yes. Agents can receive rewards based on whether they successfully complete verifiable tasks through tools, APIs, databases, code execution, or simulated environments. The environment must define meaningful success conditions and restrict unsafe actions.
14. How do engineers evaluate an RLVR-trained model?
Engineers use independent evaluation datasets, hidden test cases, task-specific accuracy measures, pass@k, verifier reliability metrics, and regression tests. They should also evaluate generalization beyond the exact prompts and verification conditions used during training.
15. What is the future of reinforcement learning with verifiable rewards?
Future development is likely to focus on stronger verifiers, more reliable feedback for complex tasks, improved exploration, tool-using agents, and hybrid reward systems. Combining objective verification with human feedback and robust evaluation may allow models to handle a wider range of real-world tasks.