Section 1: Understanding ML Benchmark Contamination and Why It Matters
What Is ML Benchmark Contamination?
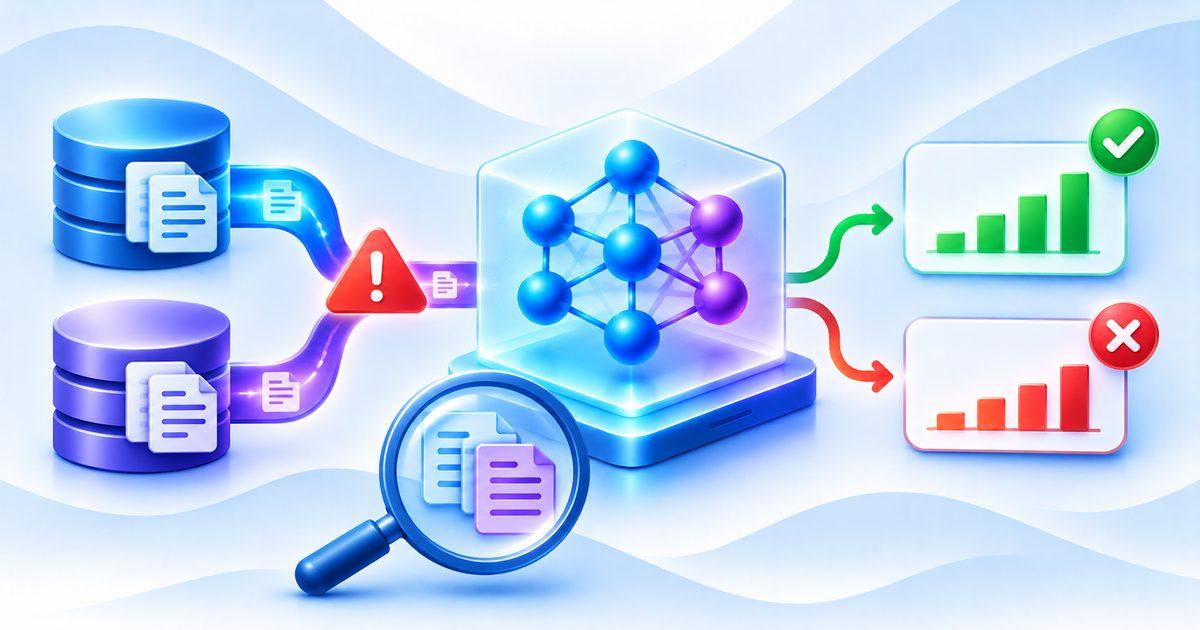
ML benchmark contamination occurs when information from an evaluation dataset becomes available to a machine learning model during training, fine-tuning, optimization, or another stage of development, potentially giving the model an unfair advantage when it is subsequently evaluated on that benchmark. Machine learning benchmarks are designed to measure how effectively models perform on examples that were not used to develop them, making the separation between training information and evaluation information essential for trustworthy performance measurements. When benchmark questions, answers, coding solutions, or closely related examples appear in the model's training data, the resulting evaluation may measure a combination of genuine generalization and prior exposure rather than the model's ability to solve entirely unfamiliar problems.
This issue has become particularly important with large language models because their pretraining datasets frequently contain information collected from publicly accessible websites, academic publications, books, code repositories, discussion forums, and educational resources. Popular benchmarks are often published alongside their questions, answer keys, explanations, and reference implementations, creating opportunities for these materials to become part of large-scale training corpora. A coding model, for example, may achieve a high score on a programming benchmark because some problem statements or solutions were present in its pretraining data, allowing it to recognize familiar patterns or reproduce previously encountered solutions rather than independently solving every problem.
However, the presence of benchmark material in a training corpus does not automatically prove that a model has memorized the examples or that its reported performance is entirely artificial. The impact depends on several factors, including the amount of exposure, frequency of repetition, similarity between training and evaluation examples, model architecture, training objectives, and the extent to which the model relies on previously encountered information. Engineers should therefore distinguish between evidence of data overlap, demonstrated memorization, and measurable benchmark performance inflation when investigating contamination risks.
Data Leakage vs. Benchmark Contamination: Understanding the Difference
Data leakage is a broader machine learning problem in which information that should not be available to a model during training or prediction influences its development or evaluation, potentially producing misleading performance measurements. It can occur when target information accidentally enters the input features, when future observations are used to predict past events, when duplicate records appear across training and testing datasets, or when preprocessing operations use information from the complete dataset rather than only the training partition. These problems can affect conventional supervised learning systems, recommendation engines, forecasting models, and deep learning applications, making leakage prevention an essential part of reliable dataset engineering.
Target leakage occurs when a feature contains information that directly or indirectly reveals the outcome the model is expected to predict, such as using a post-transaction investigation result to predict whether a transaction was fraudulent at the time it was originally processed. Temporal leakage occurs when information generated after the prediction point enters the training dataset, creating an unrealistic advantage during evaluation, while entity leakage occurs when records belonging to the same customer, patient, device, or other identifiable entity appear in both training and test partitions despite the evaluation objective requiring separation. Preprocessing leakage can also arise when normalization parameters, feature-selection decisions, or imputation statistics are calculated using validation or test information before the model is evaluated.
Benchmark contamination represents a more specific evaluation-integrity problem because it concerns the exposure of evaluation material or closely related information during model development. In large language models, benchmark questions and solutions may enter pretraining datasets through public web content, while conventional supervised models may experience contamination through duplicated test records, repeated dataset reuse, or incorrect splitting procedures. The two concepts are closely connected because both can make evaluation results appear stronger than they would be under genuinely independent testing, but their detection methods and underlying mechanisms are not always identical.
The importance of dataset quality and separation is also emphasized in “Data-Centric AI: Why Improving Your Dataset Can Beat Changing Your Model”, because model performance depends heavily on the integrity, representativeness, and construction of the data used throughout development. Engineering teams should therefore treat dataset preparation, deduplication, feature validation, and training-test separation as core responsibilities rather than assuming that strong benchmark metrics automatically demonstrate reliable generalization.
How Contamination Inflates Model Accuracy and Benchmark Scores
Benchmark contamination can inflate measured performance when a model encounters evaluation questions, answers, or closely related examples that it has already processed during an earlier stage of development. Depending on the nature of the exposure, the model may recognize a familiar question, reproduce a previously encountered answer, retrieve memorized code, or rely on learned patterns that make a particular benchmark task substantially easier. This can create the appearance of stronger reasoning, coding, or problem-solving capabilities even when the model's performance on genuinely unfamiliar examples is considerably weaker.
Consider a code-generation model evaluated using a benchmark containing programming problems and reference solutions that are publicly available online. If the model's pretraining corpus contains those problems or their solutions, it may generate correct responses by recalling previously encountered implementations or recognizing familiar problem structures. Although the model may still need to interpret the prompt and generate a valid response, its benchmark score may not accurately represent its ability to solve new programming problems that require comparable reasoning without prior exposure. Similar risks exist in mathematical reasoning benchmarks, medical question-answering datasets, examination-based evaluations, and natural language understanding tasks where published questions and answer explanations can enter training corpora.
Contamination does not always involve exact copies because benchmark-related information can appear through paraphrased questions, modified code examples, alternative explanations, or semantically similar training material. A model may encounter a mathematical problem with different variable names but an identical underlying solution, or a coding problem expressed using different wording while retaining the same algorithmic requirements. These relationships can create different levels of contamination, ranging from direct textual duplication to broader task familiarity, making exact string matching insufficient for identifying every potentially problematic example.
The effect on performance depends on the relationship between the exposed material and the evaluation task, along with how frequently the model encountered related information and whether its training process reinforced that information. Some overlap may have little measurable influence because the model learns general concepts that are also necessary for solving unseen problems, while direct exposure to test answers may create a much stronger advantage in certain circumstances. Engineers should therefore avoid assuming that every shared phrase invalidates a benchmark or that every high-scoring model has memorized its test set, instead investigating whether contamination is associated with an observable improvement in evaluation results.
Key Takeaway
ML benchmark contamination occurs when evaluation information becomes available during model development, potentially creating an advantage that makes reported performance appear stronger than genuine generalization would justify. It is closely related to broader data leakage but includes additional challenges involving pretraining corpus overlap, benchmark memorization, semantic similarity, and repeated optimization against public evaluation datasets. Software engineering teams should distinguish exposure from demonstrated memorization, investigate the actual influence of suspected contamination, and protect evaluation integrity through controlled dataset construction, provenance tracking, and independent testing.
Section 2: How Benchmark Contamination Happens Across the ML Lifecycle
Pretraining Contamination: When Public Benchmarks Enter Training Corpora
Pretraining contamination occurs when benchmark questions, answers, solutions, or closely related information become part of the large datasets used to train foundation models. Large language models are commonly pretrained using information collected from websites, books, academic papers, code repositories, educational platforms, discussion forums, and other publicly accessible sources. Since many machine learning benchmarks are published online with their evaluation questions, reference answers, and supporting explanations, these materials can unintentionally enter pretraining corpora during large-scale data collection and processing.
Consider a language model trained on a large collection of publicly available programming tutorials and code repositories that also contain questions from established coding benchmarks. When the same model is evaluated against those benchmark questions, it may recognize familiar problem statements or reproduce previously encountered solutions, potentially improving its evaluation score without demonstrating an equivalent ability to solve entirely unfamiliar problems. Similar contamination risks exist in mathematical reasoning datasets, academic examination benchmarks, medical question-answering collections, and natural language understanding tasks, where publicly available questions and answer explanations may become embedded in training material.
Contamination can occur through several forms of overlap, depending on how closely the training material resembles the evaluation examples. Exact overlap involves identical or nearly identical copies of benchmark questions, while syntactic similarity includes examples that preserve substantial wording despite formatting or minor textual changes. Semantic overlap occurs when training examples express similar meanings through different wording, whereas task-level contamination involves exposure to the underlying problem structure, solution method, or answer pattern. These distinctions matter because a simple duplicate-detection process may identify exact copies while missing paraphrased questions or alternative explanations that provide similar information.
However, discovering benchmark-related information in a pretraining corpus does not automatically establish that the model memorized it or that its evaluation score was inflated. The practical impact depends on the frequency of exposure, the similarity between training and evaluation examples, the model's capacity, the training objective, and whether the model can reproduce the relevant information when prompted. Engineering teams should therefore examine both the existence and characteristics of training-data overlap while avoiding the assumption that every shared phrase or concept represents harmful contamination.
Fine-Tuning, Instruction Tuning, and Benchmark-Specific Training Leakage
Benchmark contamination can also occur after pretraining when evaluation material enters supervised fine-tuning datasets, instruction-tuning corpora, domain-specific training collections, or synthetic datasets generated during model development. Fine-tuning commonly uses curated examples to adapt a pretrained model to a specific task, meaning that benchmark questions, reference answers, and detailed explanations can influence the model if they are included in the adaptation dataset. Even when benchmark questions are absent from the original pretraining corpus, subsequent training stages can introduce direct exposure and create an advantage during evaluation.
For example, a coding assistant may be fine-tuned using a dataset collected from public programming websites, where some examples contain questions and accepted solutions from a popular coding benchmark. The model may subsequently generate correct answers for those benchmark items because it has encountered the same solutions or closely related implementations during fine-tuning, potentially making its reported coding performance appear stronger than its generalization ability. Similar risks arise when mathematical reasoning models are trained on publicly available worked solutions, or when medical question-answering systems are adapted using examination preparation materials that overlap with their evaluation datasets.
Instruction tuning and synthetic data generation introduce additional contamination pathways because training examples may preserve benchmark-specific answers even when the original questions are rewritten. A dataset-generation pipeline may paraphrase public benchmark questions, ask another model to produce explanations, or create variations of known coding problems, inadvertently retaining the same underlying solutions and task structures. Although these examples may look different from the original benchmark text, they can still expose the model to information that makes subsequent evaluation easier. Engineering teams should therefore examine the provenance of both original and synthetic training examples, rather than relying exclusively on textual deduplication.
It is also important to distinguish benchmark-specific exposure from legitimate domain learning because a model can improve on a benchmark by learning general concepts that are genuinely relevant to the evaluated task. A model trained extensively on programming fundamentals may perform better on coding benchmarks without having encountered their exact questions, while a model exposed to specific reference solutions may gain an advantage through prior familiarity. Determining the difference requires examining dataset lineage, example similarity, training procedures, and performance on genuinely fresh evaluation problems instead of treating every increase in benchmark scores as evidence of contamination.
Data Splitting Errors, Repeated Benchmark Tuning, and Evaluation Feedback Loops
Benchmark contamination also occurs in conventional supervised machine learning when training, validation, and test datasets are not separated according to the actual requirements of the prediction problem. Duplicate records may appear across different partitions, allowing a model to encounter nearly identical examples during training and evaluation, while entity leakage can occur when records belonging to the same customer, patient, device, or transaction source appear across supposedly independent datasets. Temporal leakage introduces another problem when information recorded after the prediction point becomes available to the model, creating unrealistic evaluation conditions in forecasting, fraud detection, healthcare prediction, and other time-dependent applications.
Preprocessing operations can introduce additional leakage when information from validation or test data influences the transformations applied to training examples. For example, calculating normalization statistics, selecting features, imputing missing values, or encoding categorical variables using the complete dataset can allow evaluation information to influence model development. Although some of these practices are described as general data leakage rather than benchmark contamination, they undermine the same fundamental requirement that evaluation examples must remain independent of the information used to develop the model. Correct dataset splitting, entity isolation, temporal boundaries, and training-only preprocessing are therefore essential for establishing trustworthy evaluation results.
A more subtle problem arises when engineering teams repeatedly evaluate models against the same public test set and gradually optimize their development decisions around its results. Even when benchmark examples are never explicitly added to the training data, repeated experimentation can create an evaluation feedback loop in which developers adjust model architectures, prompts, hyperparameters, thresholds, and preprocessing strategies based on observed test performance. Over time, the test set effectively becomes part of the optimization process, weakening its independence and making reported scores less representative of unseen data. Public leaderboard optimization can intensify this effect because teams may repeatedly modify their systems to improve benchmark rankings without obtaining equivalent improvements on fresh evaluation examples.
These reproducibility challenges are particularly important when multiple engineers or research teams perform experiments using shared datasets, notebooks, and evaluation infrastructure. As explained in “The Reproducibility Crisis in Machine Learning: What Engineering Teams Can Do”, trustworthy experimentation depends on preserving dataset versions, preprocessing history, model configurations, and evaluation procedures so that reported results can be reconstructed and investigated. Engineering teams should therefore maintain separate development and final evaluation datasets, restrict repeated access to locked test sets, and record the number and nature of experiments performed against public benchmarks.
Key Takeaway
Benchmark contamination can enter machine learning systems at multiple stages, including pretraining, supervised fine-tuning, synthetic-data generation, dataset splitting, repeated benchmark optimization, and retrieval-time information access. Understanding these pathways requires distinguishing exact duplication, semantic overlap, task-level familiarity, conventional data leakage, and evaluation feedback loops rather than relying exclusively on simple text-matching techniques. By preserving data provenance, controlling benchmark access, validating dataset partitions, and auditing external information sources, engineering teams can reduce contamination risks and establish more credible measures of genuine model generalization.
Section 3: Detecting and Measuring Benchmark Contamination
Exact Matching, Fuzzy Matching, and Duplicate Detection
Detecting benchmark contamination often begins with identifying exact or near-exact overlaps between evaluation examples and the datasets used during model development. Exact matching compares benchmark questions, answers, code snippets, and reference solutions against available training records to identify identical or directly duplicated content. Engineering teams can implement this process using normalized text representations, cryptographic hashes, document fingerprints, and database lookup operations, allowing large training corpora to be screened efficiently for previously published evaluation material. For example, a coding benchmark may contain a problem statement and reference implementation that also appear in a public GitHub repository included in a model's pretraining dataset, creating a direct overlap that can be identified through text or code comparison.
Before performing matching, engineers should normalize the source material to account for differences that do not meaningfully change its content. Operations such as removing unnecessary whitespace, standardizing capitalization, normalizing Unicode characters, eliminating formatting differences, and applying consistent tokenization can help identify duplicate examples that would otherwise appear different at the raw text level. For code datasets, additional normalization may involve removing comments, standardizing formatting, and comparing syntactic structures, although these transformations must preserve meaningful differences in program behavior. N-gram overlap and fuzzy matching can extend the detection process by identifying partially duplicated examples, similar code fragments, or benchmark questions with minor wording changes.
However, exact and fuzzy matching cannot identify every form of contamination because benchmark-related information may be expressed through substantially different wording or representations. A mathematical problem may be rewritten with different variable names while preserving the same solution, and a programming problem may be paraphrased while retaining the same algorithmic requirements. Exact string matching is therefore a useful first-stage screening technique rather than a complete contamination-detection solution, making semantic analysis and behavioral testing necessary when investigating more complex forms of overlap.
Semantic Similarity, Embedding Analysis, and Advanced Contamination Detection
Semantic similarity techniques help identify benchmark-related training examples that share meaning with evaluation material even when their wording, formatting, or surface structure differs. These techniques commonly use embedding models to convert questions, passages, or code descriptions into numerical vector representations, allowing engineers to compare examples based on their position within a learned semantic space. By calculating similarity scores between benchmark items and training records, an evaluation team can retrieve potentially related examples and investigate whether they contain the same underlying questions, reasoning patterns, or solutions. This approach is particularly useful when analyzing large language model pretraining corpora that contain paraphrased material, translated questions, or explanations derived from publicly available benchmarks.
A practical detection pipeline can generate embeddings for benchmark examples and training documents, store them in a vector database, and retrieve the nearest training records for each evaluation item. Engineers can then examine similarity rankings, compare relevant text passages, and determine whether the retrieved examples represent genuine overlap or merely share common terminology. For instance, two medical questions may use different language while testing the same clinical concept, but their semantic similarity does not necessarily mean that one was copied from the other or that the model was exposed to the exact evaluation answer. Similarity thresholds must therefore be calibrated against the task and dataset because generic domain terminology, common coding patterns, and frequently discussed concepts can create false positives.
Advanced detection approaches can combine semantic retrieval with likelihood-based analysis, benchmark-specific probes, and independent examination of potentially overlapping records. Likelihood-based techniques investigate whether a model assigns unusually high probabilities to specific benchmark sequences or candidate continuations, which may indicate prior familiarity under particular experimental assumptions. LLM-prompted detection methods can also compare candidate training examples against benchmark material or ask a model to identify potential similarities, although these approaches are heuristic and may produce inconsistent judgments. The 2026 systematic review, Are LLM Benchmarks Already Contaminated?, categorizes these methods across exact, syntactic, semantic, and task-level contamination, emphasizing that their effectiveness depends on model access, detection assumptions, and the type of overlap being investigated.
Membership Inference, Behavioral Testing, and Black-Box Detection Methods
Membership inference provides another approach to contamination investigation by attempting to determine whether a particular example or document was included in a model's training data. Rather than directly comparing the full training corpus with a benchmark, these methods analyze how the model responds to selected inputs and use signals such as prediction likelihood, confidence behavior, or differences between related examples to estimate whether the material may have been encountered previously. In white-box settings, investigators may have access to model parameters, training records, or token-level probability information, while black-box approaches operate through the model's publicly accessible interface and analyze its generated responses without requiring direct access to internal model components.
Behavioral testing can complement these methods by constructing controlled variations of benchmark questions and examining whether the model reproduces familiar answers or demonstrates unusual sensitivity to specific wording. For example, an evaluator may compare responses to an original programming question, a paraphrased version, and a structurally equivalent problem with modified inputs, checking whether the model consistently reproduces the reference solution or demonstrates the ability to generalize to the changed problem. Similar tests can be performed on mathematical reasoning and question-answering benchmarks by modifying names, numerical values, question structure, or contextual information, although strong performance on these variations does not independently prove that the original benchmark was absent from training.
Membership-inference techniques have important limitations because unusually high confidence or likelihood does not necessarily indicate memorization, while genuine memorized examples may not always produce easily detectable output patterns. Research published in the 2025 NAACL Findings study Does Data Contamination Detection Work (Well) for LLMs? found that several evaluated membership-inference assumptions could perform close to random guessing in particular pretraining-data settings, with distribution shifts creating additional detection difficulties. Researchers must therefore distinguish between detecting evidence of previous exposure and establishing that exposure caused a measurable improvement in benchmark performance, particularly when different detectors produce conflicting results.
Engineering teams should use membership inference and behavioral testing as complementary evidence rather than treating either method as definitive proof of contamination. The evaluation principles discussed in “ML Testing for Software Engineers: How to Test Systems That Don't Always Produce the Same Output” are relevant because benchmark auditing requires controlled inputs, repeatable experiments, statistical comparisons, and careful interpretation of model outputs. Combining these practices helps investigators avoid confusing legitimate generalization with memorization while identifying cases that require deeper examination of training-data provenance.
Key Takeaway
Detecting and measuring benchmark contamination requires multiple complementary methods because exact matching, fuzzy matching, semantic similarity, likelihood analysis, and membership inference identify different forms of possible exposure. None of these approaches independently proves that a model memorized benchmark material or that its reported performance was inflated, making controlled experiments, statistical analysis, and independent evaluation essential. By measuring contamination prevalence, analyzing performance across appropriately selected subsets, documenting detection uncertainty, and validating results on fresh evaluation data, engineering teams can produce more trustworthy assessments of genuine model generalization.
Conclusion: Building ML Systems That Measure Genuine Generalization
Machine learning benchmarks play an essential role in evaluating model capabilities, comparing architectures, guiding research investments, and determining whether new training approaches deliver meaningful improvements. However, these evaluations are only reliable when test examples represent information that the model has not previously encountered in ways that compromise the intended assessment. ML benchmark contamination challenges this assumption by allowing evaluation questions, answers, solutions, or closely related information to enter pretraining corpora, fine-tuning datasets, synthetic training collections, or other development workflows, potentially making models appear more capable than they actually are on unfamiliar problems.
The problem extends beyond large language models because conventional supervised machine learning systems can also experience evaluation leakage through duplicate records, incorrect dataset splitting, target leakage, temporal leakage, and preprocessing errors. In foundation models, contamination introduces additional complexity through semantic overlap, task-level familiarity, benchmark-specific optimization, and retrieval-time information access. Engineering teams must therefore distinguish between the presence of overlapping information, actual memorization, and measurable performance inflation rather than assuming that every detected similarity invalidates a benchmark or that every impressive score represents genuine generalization.
Identifying contamination requires multiple complementary detection approaches because no single technique can reliably uncover every form of prior exposure. Exact matching, fuzzy matching, hashing, and n-gram analysis provide useful methods for finding duplicated material, while embedding-based retrieval and semantic analysis can identify potentially related examples that use different wording. Membership inference, likelihood-based techniques, behavioral testing, and controlled contamination experiments can provide additional evidence about model exposure and its potential influence on evaluation outcomes. Nevertheless, these methods have limitations involving false positives, false negatives, distribution differences, and assumptions about model access, making transparent reporting and independent validation essential when interpreting their results.
Building trustworthy benchmarks also requires proactive engineering practices that protect evaluation data throughout the development lifecycle. Dataset provenance, entity-based splitting, temporal separation, deduplication, locked test sets, fresh evaluation examples, controlled benchmark access, and statistical validation help reduce the risk of information leakage and benchmark overfitting. Organizations should also document known contamination risks, preserve training-data and model lineage, audit synthetic-data and retrieval pipelines, and introduce automated overlap checks into their CI/CD and model-governance workflows.
Ultimately, the objective of machine learning evaluation is not to produce increasingly impressive benchmark scores, but to determine whether a model can perform reliably on information and situations that genuinely test its intended capabilities. Organizations that combine contamination-resistant datasets, independent evaluation, rigorous statistical analysis, and production-oriented testing can make better model-selection decisions and establish stronger evidence of real-world performance. As AI systems become more capable and their training datasets increasingly difficult to audit completely, benchmark integrity must become a fundamental engineering responsibility rather than an optional research consideration.
Frequently Asked Questions
1. What is ML benchmark contamination?
ML benchmark contamination occurs when evaluation questions, answers, solutions, or closely related information become available to a model during training or development, potentially giving it an advantage during subsequent evaluation. This exposure can happen through pretraining corpora, fine-tuning datasets, synthetic examples, public repositories, or repeated benchmark-specific optimization. Consequently, the resulting evaluation score may reflect a combination of genuine generalization and previous exposure rather than the model's ability to solve entirely unfamiliar examples.
2. How does data leakage make machine learning models appear more accurate?
Data leakage occurs when information that should not be available during training or prediction influences the model's development or evaluation. For example, a forecasting model may accidentally use future information, or a classification model may receive features that indirectly reveal the target label, allowing it to achieve artificially high evaluation scores. Because the model benefits from information that would not be available under real deployment conditions, its measured performance may significantly overestimate its actual predictive capability.
3. What is the difference between data leakage and benchmark contamination?
Data leakage is a broader problem involving inappropriate information entering the training or evaluation process, including target leakage, temporal leakage, entity overlap, and preprocessing leakage. Benchmark contamination specifically concerns the exposure of evaluation material or closely related information during model training, fine-tuning, development, or inference. Both can compromise evaluation reliability, but benchmark contamination is particularly important for foundation models because their large training corpora may contain publicly available benchmark questions, answers, and reference solutions.
4. How does benchmark contamination affect large language models?
Large language models are frequently trained on extensive collections of publicly available text, code, academic publications, and educational material, some of which may contain benchmark questions and their solutions. When these models are evaluated on overlapping benchmarks, they may recognize familiar questions, reproduce previously encountered answers, or rely on learned solution patterns, potentially improving their scores without demonstrating equivalent generalization to unseen examples. The severity of this effect depends on the amount of exposure, training procedures, model behavior, and similarity between the training and evaluation material.
5. What is the difference between exact, syntactic, semantic, and task-level contamination?
Exact contamination involves identical or directly duplicated evaluation examples appearing in training data, while syntactic contamination involves examples that retain substantial textual similarity despite formatting or minor wording changes. Semantic contamination occurs when training examples express similar meanings using different language, whereas task-level contamination involves exposure to the underlying problem structure, reasoning method, or solution approach. These categories represent different forms of possible overlap, and detecting one type does not automatically establish that the model has memorized or benefited from the corresponding evaluation example.
6. How does benchmark contamination occur during pretraining and fine-tuning?
During pretraining, benchmark questions and solutions can enter training corpora through publicly accessible websites, code repositories, research papers, books, and educational resources collected at scale. During fine-tuning, contamination can occur when benchmark-specific examples, answer explanations, synthetic variations, or related instructional material are included in domain-specific datasets. Because contamination can enter at multiple stages, engineering teams should examine the provenance of pretraining and fine-tuning data rather than checking only the original training corpus.
7. Can repeated use of public test datasets cause benchmark overfitting?
Repeated evaluation against the same public test dataset can create benchmark overfitting when developers gradually adjust architectures, prompts, hyperparameters, and decision thresholds according to observed evaluation results. Even when test examples are not explicitly included in model training, repeated feedback can make development decisions increasingly specialized to the benchmark. Maintaining a separate locked evaluation set and limiting access to final test results helps preserve independent evidence of model generalization.
8. What is the difference between training-time and search-time contamination?
Training-time contamination occurs when benchmark-related information enters the model's pretraining, fine-tuning, or other development datasets before evaluation. Search-time contamination occurs when a model accesses benchmark questions, answers, or related solutions through external retrieval systems, search tools, code repositories, or other resources while generating its response. This distinction is particularly important for retrieval-augmented generation systems and AI agents, because evaluating the complete system requires examining both the model's training history and the information sources available during inference.
9. How can engineers detect benchmark contamination in training datasets?
Engineers can begin with exact matching, normalized text comparison, hashing, n-gram analysis, and fuzzy matching to identify duplicated or closely related benchmark material within available training datasets. Embedding-based semantic retrieval can extend the investigation by finding paraphrased examples and semantically related content that simple string comparisons may miss. These methods should be combined with manual investigation, data provenance analysis, and behavioral testing because detected similarity indicates a potential contamination risk rather than definitive proof that the model memorized or used the material.
10. Can membership inference detect whether a model has seen benchmark examples?
Membership inference methods attempt to estimate whether a particular example was included in a model's training data by examining output likelihoods, confidence behavior, or other observable characteristics. White-box techniques may use internal model information, while black-box approaches investigate behavior through the model's accessible interface without requiring direct access to its parameters. However, these methods depend on their assumptions and can produce false positives or fail to identify genuinely exposed examples, making them complementary investigation tools rather than definitive contamination detectors.
11. Does benchmark contamination always mean that a model has memorized the answers?
Benchmark contamination does not automatically establish memorization because the presence of related information in a training corpus does not prove that the model stored or reproduced the exact evaluation answers. A model may encounter information about the same concept and learn general knowledge that legitimately improves its ability to solve related problems without memorizing the benchmark material. Engineers should therefore distinguish between data overlap, demonstrated memorization, and measurable performance inflation through controlled experiments and independent evaluation.
12. How can benchmark contamination be quantified?
Benchmark contamination can be quantified initially by estimating the proportion of evaluation examples that overlap with training or development material, grouping detected matches according to exact, syntactic, semantic, and task-level similarity. Engineers can then compare model performance across appropriately selected suspected-contaminated and clean evaluation subsets, while accounting for differences in question difficulty and data distribution. Controlled experiments using known levels of training-data exposure provide stronger evidence about performance inflation, although contamination estimates should include uncertainty because detection methods can produce false positives and false negatives.
13. How can engineering teams create contamination-resistant evaluation datasets?
Engineering teams can reduce contamination risks by maintaining hidden holdout datasets, collecting fresh examples, introducing temporal evaluation sets, and restricting access to final benchmark questions and answers. Dataset construction should also incorporate deduplication, entity isolation, appropriate temporal splitting, verified labels, and documented provenance so that evaluation information remains independent of model development. Periodically refreshing benchmarks and using independently authored problems can provide additional protection, provided that new examples preserve the intended task difficulty and accurately measure the capability being evaluated.
14. What are the best practices for preventing data leakage in ML pipelines?
Preventing data leakage requires establishing correct training, validation, and test boundaries before model development begins, with group-based or temporal splitting used whenever random partitioning would allow related information to cross dataset boundaries. Preprocessing transformations should be fitted using training data only, while dataset snapshots, feature definitions, transformation histories, and source metadata should be versioned to preserve reproducibility. Automated duplicate detection, entity-overlap checks, feature-availability validation, benchmark access controls, and independent evaluation further strengthen the integrity of machine learning pipelines.
15. How can organizations ensure that benchmark performance reflects real-world model quality?
Organizations should combine independently maintained evaluation datasets, contamination audits, controlled experimentation, statistical validation, and transparent reporting when determining whether a model genuinely improves over existing alternatives. Benchmark results should be complemented by fresh evaluation examples, out-of-distribution testing, production-oriented validation, and monitoring under realistic application conditions because public test scores alone cannot establish reliability in every deployment environment. Maintaining training-data lineage, documenting known contamination limitations, restricting final test-set access, and periodically updating evaluation procedures helps organizations make more defensible model-selection and deployment decisions.