Section 1: Why ML Model Efficiency Requires More Than Smaller Models
Model Size Is Only One Dimension of Efficiency
Machine-learning model efficiency is often associated with reducing parameter count, but parameter count alone provides an incomplete picture of how expensive a model is to train, store, and serve. Two models with similar numbers of parameters can have very different execution characteristics because they may use different operators, tensor shapes, memory-access patterns, numerical formats, and computational pathways. A model can also contain fewer parameters while requiring more memory movement or less hardware-friendly operations, resulting in little practical improvement in latency or throughput. Engineers therefore need to evaluate efficiency as a multidimensional property that includes computation, memory consumption, latency, throughput, energy usage, and infrastructure cost rather than treating model size as the primary objective.
This distinction becomes especially important at production scale because small differences in per-request resource consumption can accumulate rapidly when a model serves millions of predictions. A recommendation service, fraud detector, search-ranking system, or real-time classification API may execute the same model continuously across a large user population, making even modest inefficiencies economically significant. The appropriate question is therefore not whether a model can be made smaller, but whether its computational footprint is proportional to the predictive capability required by the application. This perspective aligns with “Model Complexity vs Business Value: Finding the Right Level of ML,” because model complexity creates value only when the additional capacity delivers measurable improvements in the outcomes the system is designed to achieve.
Memory, Compute, Latency, and Energy Create Different Optimization Problems
Model efficiency becomes more complicated because different resource constraints can dominate under different workloads. Training a large neural network may be primarily limited by accelerator availability, memory capacity, communication bandwidth, or the time required to process a massive dataset, while online inference may be constrained by latency, concurrent requests, power consumption, or the cost of keeping enough accelerator capacity available to meet demand. A technique that improves one dimension can therefore have little effect on another, making efficiency optimization a trade-off rather than a single numerical target.
Memory is particularly important because neural networks repeatedly move parameters, activations, gradients, and intermediate tensors through different levels of the memory hierarchy. A model can contain relatively few arithmetic operations while still requiring substantial memory traffic, especially when large tensors must be repeatedly written to and retrieved from external memory. Reducing parameter precision, simplifying intermediate representations, or restructuring computation can sometimes produce greater practical gains than merely removing arithmetic operations. Energy consumption is also closely connected to data movement and hardware utilization, which means that reducing unnecessary computation can improve both infrastructure efficiency and the operational sustainability of large-scale ML systems.
Latency creates another constraint because an optimization that increases throughput may still be unsuitable for interactive applications if it introduces additional queueing or preprocessing time. Conversely, a model configuration optimized for very low latency may consume more resources because it prevents effective batching. Engineers therefore need workload-specific performance targets and must evaluate efficiency under realistic serving conditions rather than assuming that one optimization strategy will perform equally well across every deployment environment.
Theoretical Compression Does Not Guarantee Real-World Speedups
A major challenge in model optimization is the difference between reducing theoretical complexity and reducing actual execution time. Removing parameters, creating sparse weight matrices, or lowering numerical precision can make a model mathematically smaller, but these changes produce meaningful production benefits only when the software and hardware stack can exploit them. An accelerator optimized for dense matrix operations may not execute an irregularly sparse model significantly faster, while a runtime that lacks efficient support for a particular numerical format may provide little benefit from quantization.
This distinction is especially important for pruning because deleting individual weights can dramatically reduce the number of nonzero parameters without reducing the dimensions of the underlying tensors. The hardware may still process structures that contain many zero values unless the execution system is explicitly designed to skip them. Structured pruning can therefore be more useful in some environments because removing complete channels, filters, or blocks can translate more directly into smaller operations that existing hardware can execute efficiently. The same principle applies to quantization, where lower numerical precision may reduce memory requirements but not necessarily improve latency if the target processor lacks optimized support for the chosen representation.
Effective model optimization therefore requires measurement on actual production hardware and workloads. Engineers need to evaluate not only parameter count or theoretical operations but also end-to-end latency, memory consumption, throughput, accelerator utilization, and energy behavior. A compression method should be considered successful when it produces a measurable system-level improvement while keeping predictive quality within acceptable limits, rather than simply producing a smaller model artifact.
Key Takeaway
ML model efficiency is not simply a matter of making a neural network smaller because real-world performance depends on the interaction among computation, memory, latency, energy, software execution, and hardware capabilities. Engineers achieve meaningful efficiency when pruning, quantization, distillation, sparse computation, and architectural optimization produce measurable reductions in end-to-end resource consumption while preserving the predictive capabilities, reliability, and latency required by the production workload.
Section 2: Pruning and Sparse Computation: Removing Unnecessary Work
What Pruning Removes From a Trained Model
Pruning reduces model complexity by identifying parameters or structures that contribute relatively little to the target task and removing them from the model. The underlying idea is that trained neural networks often contain redundancy, meaning that not every parameter contributes equally to the final prediction. Engineers can exploit this redundancy by evaluating parameter importance, removing low-value components, and retraining or fine-tuning the remaining model so that it recovers some of the capability lost during compression. This creates a smaller computational representation while attempting to preserve the accuracy and robustness required by the application.
Pruning can operate at different structural levels, including individual weights, neurons, channels, filters, attention components, or larger blocks within the architecture. Fine-grained pruning can create substantial sparsity because individual connections can be removed with relatively precise control, while structured pruning removes larger units that are easier for conventional hardware and inference runtimes to process efficiently. The appropriate strategy depends on whether the primary objective is reducing storage, decreasing theoretical computation, lowering actual latency, or improving accelerator utilization.
The pruning process usually involves evaluating the contribution of different model components, removing selected structures, and then fine-tuning the remaining model to recover performance. This creates an important distinction between compression and retraining because an aggressively pruned model may initially lose significant predictive capability before optimization restores some of that loss. Engineers therefore need to establish a target compression level based on the quality requirements of the production workload rather than assuming that maximum parameter removal is automatically desirable.
Structured and Unstructured Sparsity Have Different Production Implications
The distinction between structured and unstructured sparsity becomes important when a compressed model moves from an experiment into production because the mathematical reduction in parameters does not necessarily translate into faster execution. Unstructured pruning can eliminate individual weights throughout a tensor, creating highly sparse matrices that reduce the number of meaningful parameters but may leave the original tensor dimensions unchanged. If the processor and runtime continue executing dense operations over those structures, much of the theoretical savings may remain unrealized.
Structured pruning addresses this limitation by removing larger computational units such as entire channels, filters, heads, or blocks. These changes can directly reduce the size of matrix operations and convolutional workloads, making them easier for conventional accelerators to process efficiently. The trade-off is that structured pruning can be less flexible because removing larger components may affect model capacity more aggressively than eliminating individual low-value connections.
The choice therefore depends on the target execution environment and the type of performance improvement required. A model deployed on specialized hardware with strong sparse-computation support may benefit substantially from fine-grained sparsity, while an application running on standard accelerators may achieve more predictable gains from structured reduction. This reinforces the broader principles in “Sparse Machine Learning: Why Doing Less Computation Can Produce Better AI Systems,” where computational savings become meaningful only when the model representation and execution environment are aligned.
Sparsity can also occur naturally within some architectures or be introduced deliberately through regularization during training. Engineers can encourage certain patterns of zeros or inactive components so that the final model is easier to compress and execute efficiently. The objective is to create sparsity that the hardware can exploit rather than simply producing a lower-density mathematical representation that leaves runtime behavior unchanged.
Sparse Computation Requires Hardware and Compiler Support
The practical value of sparse models depends heavily on whether the complete software and hardware stack can recognize and exploit the reduced computation. A model may contain a high proportion of zero-valued parameters, but if the runtime still loads and processes those values as though they were dense, the expected performance improvement may be negligible. Sparse computation therefore requires compatible kernels, compilers, memory layouts, scheduling strategies, and accelerator capabilities that can skip unnecessary operations rather than merely storing zeros.
Hardware support can make a substantial difference because some accelerators contain specialized execution paths for particular sparsity patterns. When model structure matches those patterns, the hardware can reduce arithmetic operations and potentially decrease memory movement as well. Engineers must therefore evaluate not only how sparse a model has become but also whether its sparsity pattern matches the capabilities of the deployment platform.
Compiler optimization is equally important because the computational graph must be transformed into an execution strategy that takes advantage of sparse structures. Poorly optimized graph transformations can introduce additional overhead that offsets the theoretical savings achieved through pruning. Engineers therefore need profiling tools to determine whether sparse kernels are actually being selected, whether memory access remains efficient, and whether accelerator utilization improves after compression.
These considerations make sparsity a hardware-aware optimization rather than a purely mathematical technique. Teams should benchmark the original dense model and the pruned model under identical production conditions, comparing latency, throughput, memory usage, accelerator utilization, and energy consumption alongside predictive quality. This approach prevents theoretical compression metrics from being mistaken for actual system performance.
Key Takeaway
Pruning and sparse computation can reduce model complexity by removing low-value parameters and structures, but meaningful production gains depend on whether the resulting sparsity is compatible with the hardware, compiler, and runtime. Engineers achieve the strongest results by choosing the right pruning structure, validating performance beyond parameter count, and balancing computational savings against predictive quality, robustness, latency, and the specific requirements of the production workload.
Section 3: Quantization and Distillation: Preserving Capability With Less Resource Consumption
How Quantization Reduces Numerical Precision and Memory Requirements
Quantization improves model efficiency by representing weights, activations, and sometimes intermediate computations using fewer bits than the numerical formats used during conventional training or inference. A model operating with higher-precision values can require substantial memory because every parameter and activation occupies a larger representation, while lower-precision formats can reduce storage requirements and decrease the amount of data that must move through memory during execution. When the target accelerator supports those formats efficiently, quantization can also increase throughput because more operations can be performed within the same hardware and memory budget.
The benefit becomes significant for large production models because memory consumption can influence both deployment feasibility and inference economics. A model that barely fits into accelerator memory may require additional devices or more expensive hardware, while a quantized version may fit within a smaller memory footprint and reduce the amount of data transferred during inference. Lower-precision execution can therefore improve several dimensions simultaneously, although the actual benefit depends on the architecture, runtime, and hardware.
Quantization introduces a quality trade-off because numerical approximation can affect model behavior, particularly in operations that are sensitive to accumulated error. Engineers therefore need to determine where reduced precision is safe and where higher precision should be retained. Mixed-precision execution can provide a practical compromise by applying aggressive quantization to components that tolerate it while preserving more precision in sensitive operations. The result can be a model that achieves substantial memory and computational savings without applying the same precision reduction indiscriminately across the entire network.
Post-Training and Training-Aware Quantization Require Different Trade-Offs
Post-training quantization is attractive because it can be applied to an already trained model without requiring a complete retraining cycle. Engineers typically use representative data to estimate appropriate numerical ranges and convert model parameters or activations into lower-precision formats. This approach can be relatively fast and operationally convenient, making it useful when an existing model needs to become more efficient for deployment without reopening the entire training process.
The limitation is that post-training quantization provides fewer opportunities for the model to compensate for the numerical changes. A model that is highly sensitive to precision loss may experience noticeable degradation, particularly when activation distributions vary significantly across inputs or when certain layers depend heavily on numerical accuracy. Engineers therefore need representative calibration data and should evaluate both aggregate quality and important edge cases after quantization.
Training-aware quantization introduces quantization effects during the training or fine-tuning process so that the model can learn parameters that are more robust to reduced numerical precision. This can provide better quality retention for models that are sensitive to post-training conversion, although it requires additional training compute and a more involved optimization pipeline. The choice between approaches depends on the target accuracy requirements, available training resources, model sensitivity, and hardware capabilities.
Hardware support remains important because a quantized model does not automatically produce lower latency simply because its numerical representation is smaller. The runtime needs efficient kernels for the selected precision, and the accelerator must be capable of processing those values efficiently. Engineers should therefore benchmark the quantized model on the actual deployment platform rather than assuming that a reduction in bit width will directly translate into proportional speed improvements.
Combining Quantization and Distillation for More Efficient Models
Quantization and distillation can be combined because they address different dimensions of model efficiency. Distillation reduces the model's architectural and parameter footprint, while quantization reduces the numerical representation required to execute the resulting model. A large teacher can therefore produce a compact student, after which the student can be quantized to reduce memory use and improve hardware efficiency further. This layered approach can create substantially smaller deployment models than either technique alone.
The combination is especially valuable when models need to operate under strict memory or latency constraints because distillation can reduce the number of parameters while quantization reduces the storage and computation associated with those parameters. The resulting model can be easier to deploy on constrained accelerators, mobile hardware, or high-volume inference infrastructure while retaining an acceptable portion of the teacher's predictive capability.
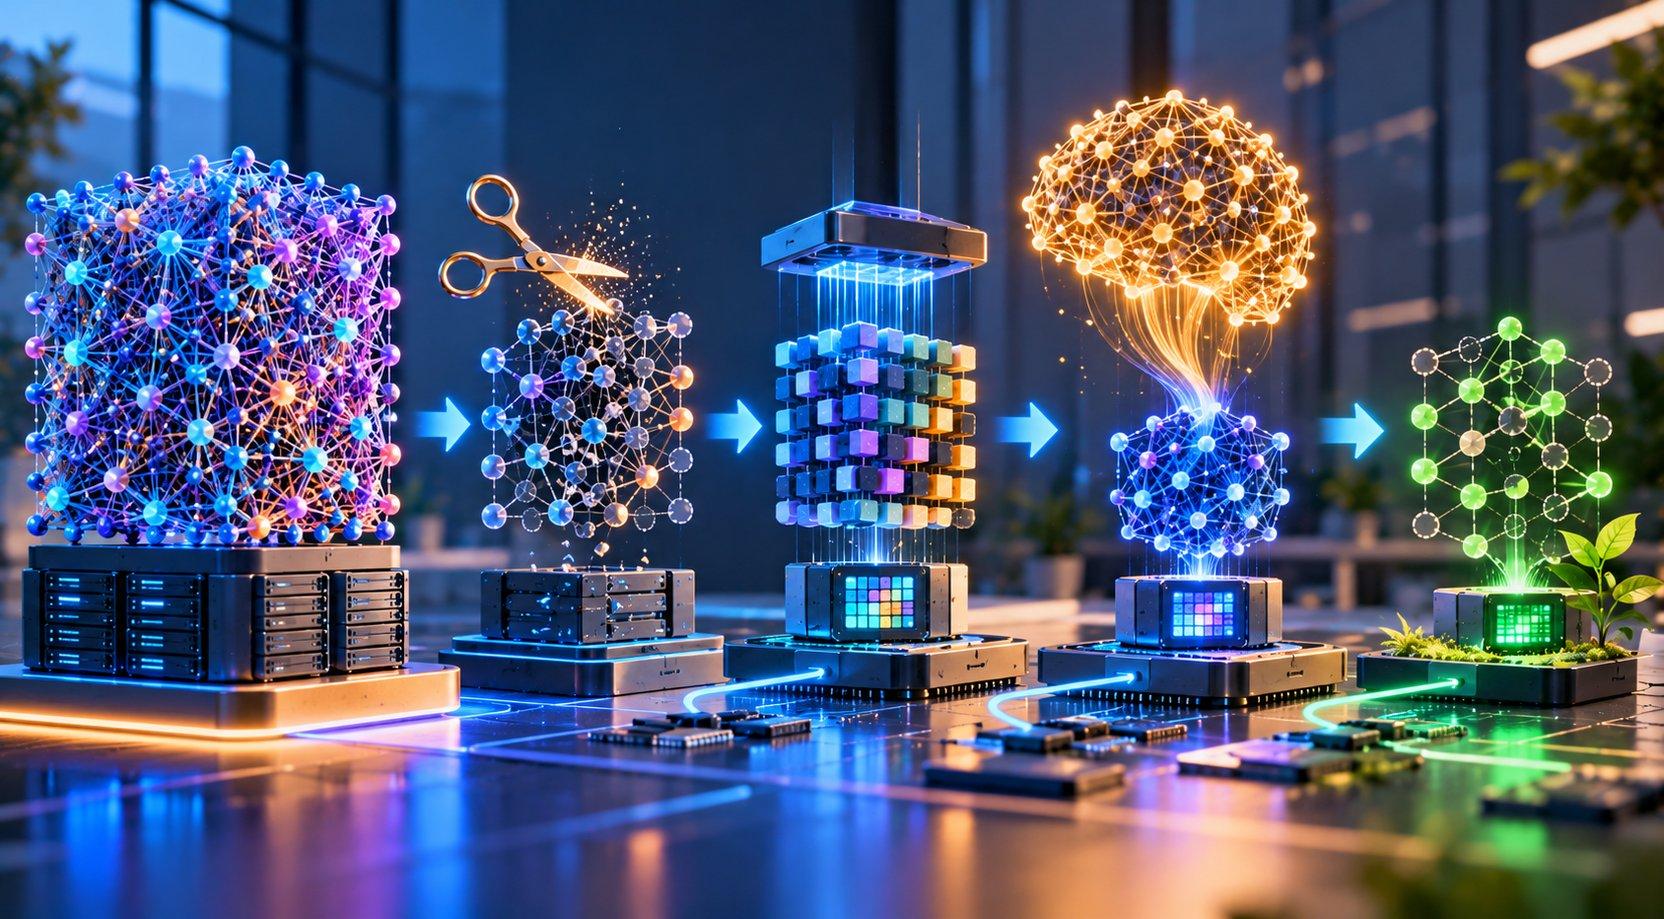
However, combining multiple compression techniques can also compound errors because a student model may already have some quality loss relative to the teacher before quantization introduces additional approximation. Engineers therefore need sequential and joint evaluation to understand where degradation originates. A useful workflow can compare the original teacher, the distilled student, the quantized student, and the combined optimized model under identical evaluation conditions so that quality changes can be attributed to each step.
The broader engineering lesson is that efficient modeling should be treated as a constrained optimization problem rather than as a collection of independent tricks. Engineers should define the required quality, latency, memory, throughput, and infrastructure budget first, then select the combination of distillation and quantization strategies that satisfies those constraints. The ideas in “Knowledge Distillation: How Smaller Models Learn From Larger AI Systems” and “Quantization Explained: How AI Models Become Faster and Cheaper to Run” illustrate how capability preservation and computational reduction can be approached from complementary directions.
Key Takeaway
Quantization and knowledge distillation reduce model resource requirements through different mechanisms, with quantization lowering numerical precision and distillation transferring useful behavior into smaller architectures. Engineers can combine these techniques to achieve greater efficiency, but successful deployment depends on validating numerical quality, hardware execution, edge-case behavior, and end-to-end performance so that computational savings do not remove capabilities that remain important to the production system.
Section 4: Turning Model Compression Into Production Performance
Benchmarking Must Measure Accuracy and Real Execution Cost Together
Model compression becomes valuable only when theoretical reductions in parameters, precision, or computation translate into measurable improvements in the production environment, making benchmarking an essential final stage in the optimization process. A pruned, quantized, or distilled model may be substantially smaller than its original version while producing little improvement in latency if the target hardware cannot exploit the new structure, so engineers need to compare the original and optimized models using identical workloads, input distributions, concurrency levels, and deployment configurations.
Production benchmarking should therefore extend beyond predictive quality and include latency, throughput, memory consumption, accelerator utilization, energy use, and cost per inference. Average latency alone can hide important behavior because a model that responds quickly under light traffic may experience substantial delays when request concurrency increases or when input sizes become larger. Tail latency is particularly important for interactive systems because the slowest requests can determine whether the application meets its service-level objectives even when average performance appears acceptable.
Quality evaluation must also extend beyond aggregate metrics because compression can disproportionately affect particular segments, rare events, or difficult inputs. A student model created through distillation may perform almost identically to its teacher on common examples while becoming less reliable on edge cases, while aggressive quantization may introduce small numerical changes that become significant for long sequences or sensitive classification boundaries. Engineers therefore need representative evaluation datasets, stress cases, and segment-level comparisons that reveal where optimization changes model behavior.
Hardware-Aware Optimization Determines Whether Compression Pays Off
Compression techniques interact directly with the execution platform, making hardware-aware optimization critical when determining whether pruning, quantization, or sparsity creates actual performance gains. A quantized model may use fewer bits but receive limited latency improvement if the accelerator does not provide efficient kernels for the selected numerical format, while an unstructured sparse model may retain much of its original execution cost when the hardware continues processing the underlying tensor as though it were dense.
Engineers therefore need to understand the capabilities of the target hardware before selecting a compression strategy. Some accelerators are optimized for lower-precision matrix operations, while others provide specialized support for structured sparsity or particular tensor dimensions. Compiler behavior also influences the outcome because graph transformations, operator fusion, kernel selection, and memory scheduling determine whether the optimized representation is executed efficiently or converted into a less efficient form during runtime.
Hardware-aware benchmarking should compare not only end-to-end latency but also memory bandwidth, accelerator utilization, kernel execution time, and data movement. These measurements help engineers determine whether the optimization removed the actual bottleneck or merely changed the representation of the model without changing how the system spends most of its time. In some cases, a slightly larger model with hardware-friendly operations can outperform a smaller compressed model because the larger model maps more efficiently to the available execution architecture.
This makes compression a co-design problem in which model structure and hardware capabilities are optimized together rather than sequentially. Engineers can combine structured pruning, supported quantization formats, efficient tensor layouts, and compiler-friendly operators to create models that are not only smaller but also easier for the deployment stack to execute efficiently.
Efficient Serving Requires Profiling, Caching, and Selective Computation
A compressed model can still consume unnecessary resources when the surrounding serving architecture repeatedly performs work that could be avoided, making system-level optimization an important complement to model compression. Feature retrieval, preprocessing, embedding generation, serialization, and network communication can dominate the request path even when model inference itself becomes substantially faster. Engineers therefore need end-to-end profiling to determine where time and compute are actually being spent and whether compression has shifted the bottleneck to another stage of the serving pipeline.
Caching can eliminate repeated inference or representation generation when inputs and intermediate results remain valid for sufficient periods. Frequently requested embeddings, stable classification results, or reusable preprocessing outputs can be stored and reused instead of recomputed for every request. The effectiveness of caching depends on freshness requirements, so engineers need explicit invalidation policies to prevent resource savings from producing stale predictions.
Selective computation offers another way to reduce average cost by matching model capacity to input difficulty. A lightweight compressed model can process routine cases, while uncertain requests can be routed to a larger model or an additional computational stage. This architecture allows organizations to retain access to higher-capacity models without paying their full inference cost for every request, creating a natural complement to pruning, quantization, and distillation.
The broader principle is that efficient serving should minimize unnecessary computation across the complete request path, which makes model compression only one component within a larger optimization strategy. This connects naturally with “Caching for AI Applications: The Overlooked Technique for Reducing Inference Costs,” because eliminating redundant work can sometimes produce greater production savings than further reducing the model itself.
Key Takeaway
Turning model compression into production performance requires engineers to connect pruning, quantization, distillation, and sparsity with real hardware, serving infrastructure, and application requirements. The strongest systems measure predictive quality and end-to-end resource consumption together, exploit hardware-supported optimizations, eliminate unnecessary computation through caching and selective inference, and treat model efficiency as a continuous lifecycle concern rather than a one-time compression exercise.
Conclusion
ML model efficiency is becoming a core part of production machine-learning engineering because the cost of intelligence increasingly matters alongside the quality of intelligence. As models become larger and inference workloads expand, organizations cannot evaluate model success through accuracy alone because training compute, memory consumption, latency, energy usage, hardware utilization, and infrastructure cost all influence whether a model is practical to operate at scale.
The most important lesson is that model efficiency is not synonymous with model size.
A smaller model can reduce memory consumption and computation, but parameter count does not capture the complete execution cost of a neural network. Tensor shapes, operator selection, memory movement, numerical precision, compiler behavior, hardware support, batching, and serving architecture can all determine whether a model performs efficiently in production. An optimized model therefore needs to be evaluated as a complete execution system rather than as a collection of parameters.
Pruning provides one path toward efficiency by removing low-value parameters or structures, allowing engineers to reduce model complexity while attempting to preserve important predictive behavior. Structured pruning can be particularly useful when the target hardware benefits directly from reduced tensor dimensions, while fine-grained sparsity can provide greater theoretical compression when the execution stack is capable of exploiting sparse computation. The distinction matters because removing parameters does not automatically mean removing equivalent work from the processor.
Quantization approaches the problem differently by reducing the numerical precision used to represent parameters and activations. Lower-precision formats can reduce memory requirements and improve throughput when supported effectively by the target hardware, but numerical approximation can also introduce quality degradation. Engineers therefore need to evaluate quantized models across representative data, sensitive layers, rare cases, and realistic workloads rather than assuming that a lower bit width automatically creates proportional performance improvements.
Knowledge distillation provides another route by transferring useful behavior from a larger teacher model into a smaller student model. The student can then provide much of the required predictive capability at a lower inference cost, making distillation particularly valuable when a large model is useful for training but too expensive to serve for every request. The quality of the resulting student depends heavily on the information transferred during distillation and the coverage of the data used to teach the smaller model.
Sparse computation connects compression with execution because the practical value of sparsity depends on whether the hardware and compiler can skip unnecessary operations. A model containing many zero-valued weights may still perform like a dense model when the runtime lacks efficient sparse kernels, while hardware-supported structured sparsity can translate model compression into meaningful reductions in latency and compute.
Frequently Asked Questions
1. What is ML model efficiency?
ML model efficiency refers to achieving the required predictive performance while minimizing unnecessary computation, memory usage, latency, energy consumption, and infrastructure cost throughout training and production inference.
2. Is model efficiency the same as model compression?
No. Model compression is one component of model efficiency. Pruning, quantization, and distillation compress models, while caching, batching, hardware-aware execution, selective inference, and serving optimization can reduce resource consumption without necessarily changing the model itself.
3. What is model pruning?
Model pruning removes parameters, connections, channels, filters, attention components, or other structures that contribute relatively little to the target task. The remaining model can then be fine-tuned to recover some of the predictive capability lost during pruning.
4. What is the difference between structured and unstructured pruning?
Unstructured pruning removes individual parameters and can create high levels of theoretical sparsity, while structured pruning removes larger units such as channels, filters, or blocks. Structured pruning can translate more directly into production speedups when the target hardware is optimized for the resulting tensor structures.
5. What is quantization?
Quantization reduces the numerical precision used to represent model parameters, activations, or intermediate computations. Lower-precision representations can reduce memory usage and improve computational efficiency when supported effectively by the target hardware.
6. What is knowledge distillation?
Knowledge distillation trains a smaller student model using information generated by a larger teacher model. The student attempts to preserve important predictive behavior while requiring fewer parameters and less computation during inference.
7. Can pruning, quantization, and distillation be combined?
Yes. These techniques address different sources of inefficiency and can be applied together, although their effects should be evaluated carefully because quality degradation from multiple compression stages can accumulate.
8. Does a smaller model always run faster?
No. Actual execution speed depends on operators, tensor shapes, memory movement, compiler optimizations, hardware support, batching, and runtime behavior. A smaller model can still be slower than a larger model when its computation maps poorly to the target execution platform.
9. What is sparse computation?
Sparse computation is an execution strategy that avoids performing unnecessary operations associated with zero-valued or structurally absent model components. Its practical value depends on whether the compiler, runtime, and hardware can efficiently exploit the model's sparsity pattern.
10. How does quantization affect model accuracy?
The effect depends on the model architecture, data, and numerical sensitivity of individual operations. Some models tolerate substantial precision reduction, while others require higher precision for selected components, making calibration, mixed precision, and validation important parts of quantization.
11. What is post-training quantization?
Post-training quantization converts an already trained model into lower-precision representations using calibration or representative data. It can be relatively quick to deploy because it does not require complete retraining, although some models may experience more quality degradation than they would with quantization-aware training.
12. How do engineers measure whether compression actually worked?
Engineers compare the original and optimized models using predictive quality, latency, throughput, memory consumption, accelerator utilization, energy consumption, and cost under realistic production workloads. The goal is to measure end-to-end improvements rather than relying only on parameter count or theoretical operation reductions.
13. Why is hardware important for model efficiency?
Hardware determines which numerical formats, sparse structures, tensor operations, and memory-access patterns can execute efficiently. A model optimization can provide substantial benefits on one accelerator while providing little improvement on another, making hardware-aware benchmarking essential.
14. Can efficient models reduce cloud infrastructure costs?
They can, particularly for high-volume inference workloads where reductions in per-request computation, memory usage, and latency accumulate across large numbers of predictions. The actual savings depend on accelerator utilization, serving architecture, request volume, batching, and infrastructure pricing.
15. What is the future of ML model efficiency?
The future is likely to combine pruning, quantization, distillation, sparsity, efficient architectures, caching, selective inference, adaptive computation, and specialized hardware into an integrated optimization strategy. Model efficiency will increasingly become a design requirement throughout the ML lifecycle rather than a final compression step performed after model development.