Section 1: Understanding Low-Rank Adaptation Beyond Large Language Models
Why Full Fine-Tuning Becomes Expensive When Adapting Pretrained Models
Pretrained machine learning models provide a powerful foundation for specialized applications because they learn useful representations from large datasets that would be expensive to reproduce for every new task. However, adapting these models to a particular domain often requires fine-tuning their parameters using task-specific data, introducing additional requirements for GPU memory, optimizer state, training time, and experimentation. Full fine-tuning updates all trainable model parameters, which can become computationally expensive when adapting large vision encoders, speech recognition networks, recommendation models, and time-series architectures, particularly when engineering teams must create and maintain separate versions for multiple specialized tasks.
The resource requirements extend beyond storing the model weights because training commonly requires gradients and optimizer states for the parameters being updated, together with memory for activations and intermediate computations. For large neural networks, these requirements can limit the batch size that fits on available hardware, increase training duration, and make experimentation more expensive, even when the target dataset is relatively small. The problem becomes more pronounced when an organization wants to specialize one pretrained backbone for several domains, such as adapting an image encoder for different medical imaging categories or customizing a shared speech model for different languages, accents, and acoustic environments, because maintaining fully fine-tuned copies can increase storage and operational complexity.
Full fine-tuning remains valuable when a task requires substantial changes to the model's learned representations, but updating every parameter is not always necessary to obtain useful specialization. In many situations, pretrained weights already contain capabilities that transfer to the target task, meaning that a smaller set of trainable parameters may be sufficient to adapt the model's behavior without replacing its entire learned representation. Low-rank adaptation, commonly known as LoRA, addresses this opportunity by introducing a compact trainable update into selected weight matrices while keeping the original weights frozen, reducing the number of parameters that must be optimized during adaptation. This approach can make specialized fine-tuning more practical when GPU memory, training time, and the cost of maintaining multiple task-specific versions are important constraints.
How Low-Rank Adaptation Uses Small Trainable Matrices to Modify Model Behavior
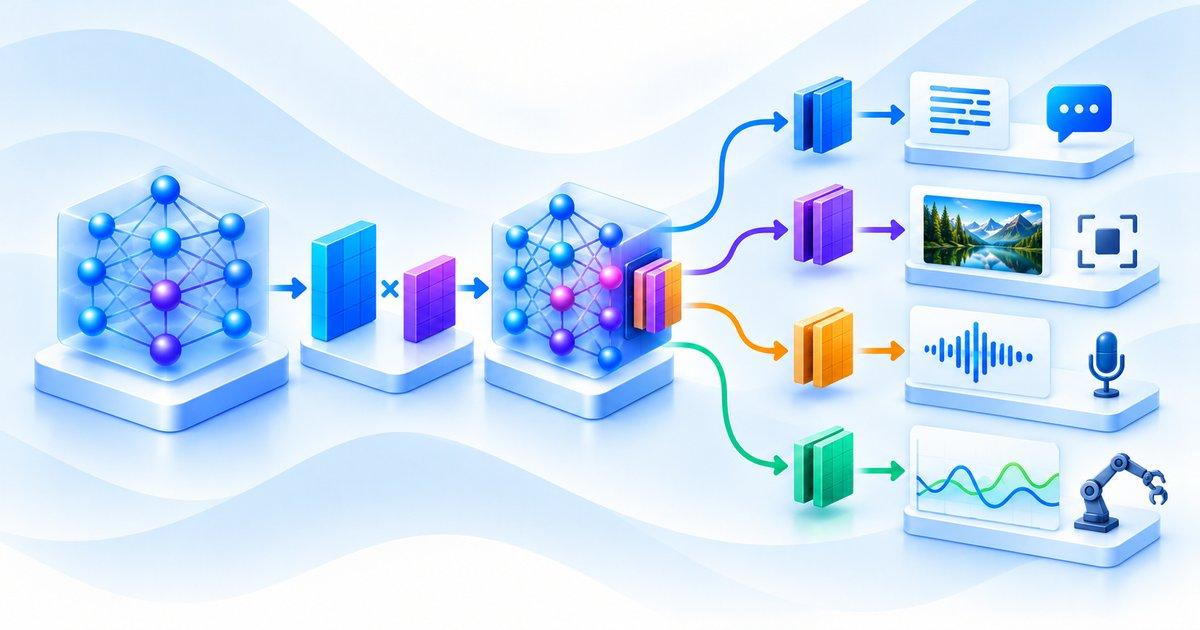
Low-rank adaptation is based on the observation that a useful weight update may sometimes be represented by a lower-dimensional structure rather than requiring unrestricted changes to every element of a large weight matrix. Suppose a pretrained linear transformation has a weight matrix (W), which maps an input vector into an output representation; conventional full fine-tuning learns an update (\Delta W) to that matrix, whereas LoRA approximates the update through the product of two smaller matrices, typically denoted (A) and (B). The adapted transformation can be expressed as (W' = W + \Delta W), with the low-rank update represented as (\Delta W = BA), optionally multiplied by a scaling factor, allowing the trainable update to be learned through substantially fewer parameters when the selected rank is small relative to the original matrix dimensions.
For a weight matrix with dimensions (d_{\text{out}} \times d_{\text{in}}), full fine-tuning updates (d_{\text{out}}d_{\text{in}}) parameters, while a LoRA update with rank (r) introduces approximately (r(d_{\text{in}}+d_{\text{out}})) trainable parameters. When (r) is much smaller than both matrix dimensions, this representation can reduce the parameter count substantially, which in turn can lower gradient and optimizer-state memory requirements during adaptation. The pretrained weight matrix remains frozen in the standard LoRA setup, allowing the training process to concentrate its updates on the low-rank matrices rather than repeatedly optimizing the full parameter set, although activations and other training-related memory costs still depend on the architecture and implementation.
Rank selection determines the dimensionality of the update and influences the balance between parameter efficiency and adaptation capacity, because a very small rank may not capture all the changes needed for a specialized task, while a larger rank increases the number of trainable parameters. Engineers must therefore evaluate different ranks and target modules using representative validation data, measuring both task performance and resource requirements rather than assuming that the lowest-rank configuration will always be sufficient. Although LoRA is widely associated with transformer-based language models, its underlying mechanism applies to suitable weight matrices in other neural architectures as well, provided that the selected components and training objective support an effective low-rank adaptation.
Applying LoRA to Computer Vision, Speech Recognition, and Recommendation Models
Computer vision provides several opportunities for parameter-efficient adaptation because pretrained visual encoders often learn representations that can be reused across image classification, object recognition, segmentation, and domain-specific visual analysis. LoRA can be applied to selected linear projections within vision transformers or to other compatible layers, allowing engineers to adapt a pretrained model to specialized image distributions without updating every original parameter. For example, a visual model pretrained on broad image datasets may need additional specialization for industrial defect detection or medical image classification, where the relevant patterns differ from general-purpose imagery and task-specific training data may be comparatively limited; LoRA offers one way to learn those changes while preserving the majority of the original representation.
Speech and audio models can also benefit from parameter-efficient adaptation when a pretrained architecture needs to handle particular languages, accents, acoustic environments, or specialized vocabularies. Depending on the model architecture, LoRA can be introduced into attention projections or other supported linear transformations in an audio encoder, speech recognition network, or related sequence model, reducing the number of parameters updated during task specialization. However, adaptation quality still depends on the diversity and accuracy of the target audio data, and freezing most of the pretrained model may limit the extent to which the system can accommodate changes that require substantial new acoustic or linguistic representations.
Recommendation systems and time-series models offer additional possibilities when their architectures contain compatible linear or projection layers and their pretrained representations provide useful starting points for the target task. A recommendation model may need to adapt shared representations to a new product category, user population, or market, while a time-series forecasting model may require specialization for a particular sensor environment or operational regime. LoRA can provide a compact update mechanism for appropriate components, but it should not be assumed to replace all task-specific adaptation strategies, particularly when the target problem depends on new categorical embeddings, substantial changes in temporal dynamics, or input structures that are not well represented by the pretrained architecture.
The broader transfer-learning principles discussed in “Transfer Learning Beyond LLMs: How Knowledge Moves Between ML Tasks” are relevant because LoRA is one method of adapting previously learned representations rather than rebuilding every model parameter for each new application. Its usefulness depends on how much of the pretrained representation transfers to the target domain, which components need to change, and whether the low-rank update has sufficient capacity to capture the required specialization. Engineering teams should therefore evaluate LoRA separately for each architecture and task instead of assuming that results obtained from language models will automatically translate to vision, speech, recommendation, or time-series workloads.
Key Takeaway
Low-rank adaptation makes specialized model fine-tuning more efficient by learning compact updates to selected pretrained weight matrices instead of updating every model parameter. Its potential benefits extend beyond large language models to compatible computer vision, speech, recommendation, and time-series architectures, although the results depend on the model structure, target data, selected rank, and required degree of specialization. By comparing LoRA with full fine-tuning, frozen feature extraction, and other parameter-efficient methods, engineering teams can determine where reducing trainable parameters delivers meaningful training and maintenance benefits without compromising task performance.
Section 2: Engineering LoRA for Different Model Architectures and Specialized Tasks
Selecting Target Layers and Modules for Low-Rank Adaptation
Implementing low-rank adaptation effectively requires deciding which parts of a pretrained model should receive trainable updates, because the selected modules determine where the model can specialize and how much adaptation capacity is available. In transformer architectures, LoRA is frequently applied to linear projections within attention mechanisms, such as query, key, value, and output projections, and may also be applied to feed-forward layers depending on the task and implementation. For vision transformers, these choices influence how visual representations are adapted, while speech models may require updates to attention projections or other compatible transformations that support the target acoustic or linguistic task.
The most suitable target modules depend on the model architecture and the nature of the required specialization, rather than following a universal configuration across all applications. If a pretrained visual encoder already captures useful shapes and textures but struggles with a specialized image domain, adapting selected projections may provide sufficient flexibility without modifying the entire network, whereas a task requiring more extensive changes to intermediate representations may benefit from targeting additional modules. Recommendation and time-series architectures introduce different considerations because their performance may depend heavily on embeddings, temporal projections, feature interactions, or specialized components that are not directly equivalent to the attention layers commonly used in transformer models.
Engineers should therefore begin by examining the model's computational structure, identifying which parameters participate in the task-relevant transformations, and testing a small number of plausible target-module configurations against a consistent baseline. This process should compare adaptation quality, trainable parameter count, training stability, memory usage, and execution behavior, because expanding the number of adapted modules increases flexibility but may also increase optimization costs and the likelihood of fitting patterns that do not generalize. By selecting target layers according to the model's architecture and the requirements of the specialized task, teams can allocate trainable parameters where they provide meaningful adaptation capacity instead of applying the same configuration indiscriminately.
Understanding LoRA Rank, Scaling, Initialization, and Regularization
The rank of a LoRA update controls the dimensionality of the trainable low-rank representation and therefore influences how much the update can change the behavior of the pretrained model. For a weight matrix (W), the standard formulation expresses the adapted weights as (W' = W + \frac{\alpha}{r}BA), where (A) and (B) are trainable matrices, (r) is the selected rank, and (\alpha) is a scaling parameter, although specific implementations may use different scaling conventions. A larger rank allows the update to represent a broader range of changes but introduces more trainable parameters, while a smaller rank provides greater parameter efficiency when the required task-specific adjustment can be represented adequately in a lower-dimensional space.
Selecting rank involves balancing adaptation capacity against the computational and statistical costs of training additional parameters, since a very low rank may restrict the model's ability to capture important target-domain patterns while an unnecessarily high rank can increase memory requirements and make optimization less efficient. Engineers can evaluate several rank values using representative training and validation data, comparing not only predictive quality but also convergence, stability, and the extent to which the adapted model generalizes beyond the examples used for training. The appropriate rank may differ across model families and target modules, making it useful to treat rank selection as an empirical design decision rather than assuming that a single value will work equally well for computer vision, speech, recommendation, and time-series tasks.
Scaling determines the magnitude of the learned update relative to the frozen pretrained weights, helping control how strongly adaptation influences the original representation during training and inference. Initialization also matters because the trainable matrices must begin in a configuration that allows optimization to introduce useful changes without unnecessarily disrupting the pretrained model's behavior; a common LoRA initialization sets one factor to small or zero-valued weights according to the implementation's convention so that the initial update is zero or effectively negligible. Regularization, learning-rate selection, and validation procedures further influence whether the model learns genuine task-specific structure or overfits limited training data, making it important to evaluate these choices together rather than tuning rank in isolation.
Combining LoRA With Quantization and Other Efficiency Techniques
LoRA can be combined with other efficiency techniques when the objective is to make model adaptation more economical, although each technique addresses a different part of the computational problem. LoRA reduces the number of parameters being optimized by introducing compact trainable updates, whereas quantization reduces the precision used to represent model weights or activations, potentially lowering memory requirements and enabling efficient arithmetic on supported hardware. This distinction matters because a model can have relatively few trainable parameters while still requiring substantial memory to store and execute its frozen backbone, making parameter-efficient training and model compression complementary rather than interchangeable strategies.
Quantized LoRA approaches, including configurations that train LoRA adapters while keeping the pretrained base model in a lower-precision representation, can reduce the memory needed to load large models during adaptation. However, quantization can introduce numerical differences and may restrict which operations or training configurations are supported efficiently, so engineers should validate the resulting model's quality, numerical stability, and resource requirements rather than assuming that combining two efficiency techniques automatically multiplies their benefits. Other approaches, such as activation checkpointing, efficient attention implementations, selective parameter updating, and suitable batch-size adjustments, may provide additional benefits depending on the architecture and the training hardware.
The principles discussed in “Efficient ML: How to Build High-Performance Models With Less Compute” are relevant because practical efficiency depends on the complete training and inference workflow rather than on the number of trainable parameters alone. Teams should measure adaptation time, peak memory usage, validation quality, artifact size, inference latency, and production throughput to determine whether LoRA, quantization, or their combination delivers the required benefits under realistic conditions. By evaluating each technique against a clear baseline and considering the needs of the target architecture, engineering teams can build a specialization strategy that reduces unnecessary resource consumption without assuming that lower parameter counts automatically produce faster execution or better predictions.
Key Takeaway
Effective LoRA implementation depends on selecting suitable target modules, choosing an appropriate rank and scaling configuration, and training against representative task-specific data with an appropriate objective. Combining LoRA with quantization or other efficiency methods can further reduce selected resource requirements, but the resulting benefits depend on architecture, hardware support, numerical behavior, and deployment needs. By evaluating adaptation quality alongside training memory, execution performance, and operational cost, engineers can determine where parameter-efficient adaptation provides a practical advantage over full fine-tuning or other specialization strategies.
Section 3: Evaluating Model Quality, Generalization, and Adaptation Efficiency
Measuring Adaptation Quality Against Full Fine-Tuning and Baseline Models
Evaluating low-rank adaptation requires comparing its predictive performance and resource consumption against suitable alternatives, because reducing the number of trainable parameters does not automatically produce a model that performs well on the target task. Engineers should establish a baseline using the original pretrained model, typically with a task-specific prediction head or an appropriate inference configuration, and compare it with LoRA, full fine-tuning, and other parameter-efficient methods where feasible. This comparison helps determine whether the pretrained representations already contain sufficient information for the specialized task, whether a low-rank update provides meaningful improvements, and whether the additional capacity of full fine-tuning is justified by the resulting gains in model quality.
The evaluation metrics should reflect the requirements of the target application rather than relying on a generic measure of accuracy across every model architecture. For computer vision, useful measures may include classification accuracy, precision, recall, or intersection over union for segmentation, while speech recognition may be evaluated through word error rate and recommendation systems may require ranking metrics such as normalized discounted cumulative gain. Time-series models may need measures such as mean absolute error or root mean squared error, depending on the forecasting objective, making it important to use metrics that capture the errors most relevant to the application. Engineers should also examine performance across important data segments, since an adapted model may improve aggregate results while performing worse for particular classes, customer groups, recording conditions, or operating environments.
Resource measurements should accompany predictive evaluation because LoRA is intended to improve adaptation efficiency rather than guarantee that every aspect of model execution becomes cheaper. Teams should record the number of trainable parameters, peak GPU memory consumption, training duration, optimizer-state requirements, convergence behavior, and storage needed for each adapted model, while separately measuring inference latency and throughput when those properties matter for deployment. This separation is essential because LoRA can substantially reduce training-related memory while leaving the frozen backbone's inference computation largely unchanged, meaning that a model that is cheaper to fine-tune may not be faster to serve.
Managing Overfitting, Catastrophic Forgetting, and Domain Generalization
Parameter-efficient adaptation can reduce the number of trainable parameters, but it does not eliminate the risk of overfitting when the target dataset is small, noisy, or insufficiently representative of the deployment environment. A LoRA adapter may learn patterns that appear useful in the training examples but fail to generalize to unseen users, image acquisition conditions, speech environments, or future time periods, particularly when the available data captures only a narrow slice of the target domain. Engineers should therefore use validation datasets that reflect realistic deployment variation, apply suitable regularization and early stopping where appropriate, and monitor performance on data that differs meaningfully from the examples used to optimize the adapter.
Catastrophic forgetting occurs when adaptation weakens previously learned capabilities that remain important beyond the target training task, although the degree of risk depends on the architecture and the adaptation strategy. Because standard LoRA keeps the pretrained weights frozen, it can preserve the original parameters while learning task-specific changes through the low-rank matrices, but the resulting model's behavior can still shift substantially when those updates are applied. A vision adapter, for example, may improve recognition of specialized industrial defects while performing poorly on a broader set of images, or a speech adapter may improve recognition for one accent while reducing performance for speakers with different acoustic characteristics, making cross-domain evaluation valuable when the model must retain broader usability.
Domain generalization should therefore be evaluated by testing the adapted model across multiple representative conditions rather than measuring only performance on a randomly selected subset of the target training distribution. Depending on the application, this may involve testing unseen data sources, rare classes, different operating environments, or later time periods, while examining whether performance deteriorates under distribution changes that are likely to occur after deployment. When preserving the pretrained model's original capabilities is important, engineers can compare the adapted model against the original checkpoint on selected reference tasks, helping determine whether the specialization produces unacceptable regressions outside the target domain.
Evaluating Rank Selection, Trainable Parameters, and Practical Performance Trade-Offs
The rank of a LoRA update determines the dimensionality of the trainable parameterization, creating a direct trade-off between adaptation capacity and the resources required to train and maintain the resulting adapter. A lower rank introduces fewer trainable parameters and can reduce optimizer-state memory, while a higher rank offers more flexibility to represent task-specific changes in the pretrained weight matrices. However, increasing rank does not guarantee better predictive performance, because the additional capacity may provide little benefit when the pretrained representation is already well suited to the target task or may encourage overfitting when training data is limited.
Rank selection should be performed through controlled experiments that vary rank while keeping the training data, evaluation protocol, and other important settings sufficiently consistent. Engineers should measure task-specific quality, convergence behavior, training time, memory consumption, and the stability of results across repeated runs where feasible, enabling them to determine whether a higher rank provides worthwhile gains. Target-module selection should be evaluated alongside rank because adapting more layers or projections can change the model's capacity and resource profile as much as changing the rank of an individual update, making it important to distinguish the effect of rank from the effect of where the adaptation is applied.
The practical efficiency of LoRA also depends on the full model architecture, since the frozen backbone still needs to be loaded and executed during training and inference. Although a smaller adapter can reduce the storage required for task-specific parameters, the overall serving memory may remain dominated by the base model, while the inference compute can remain similar to that of the original architecture if the adapter introduces additional operations that have not been merged or otherwise optimized. Teams should therefore distinguish trainable parameter count, total model storage, peak training memory, inference latency, throughput, and operational cost, preventing a single efficiency metric from obscuring the trade-offs that matter in production.
The broader efficiency techniques described in “ML Model Efficiency: Pruning, Quantization, Distillation, and Sparse Computation Explained” provide useful context for understanding how LoRA differs from other approaches to reducing the cost of machine learning systems. While LoRA targets the number of parameters updated during adaptation, pruning changes the model's parameter or computational structure, quantization reduces numerical precision, and distillation transfers knowledge into a different model, meaning that the approaches address different constraints and can sometimes complement one another. By evaluating these options against the same application requirements, engineering teams can identify whether LoRA alone provides sufficient efficiency or whether additional techniques are needed to meet inference, storage, or hardware constraints.
Key Takeaway
Evaluating LoRA requires measuring task-specific predictive quality alongside training memory, trainable parameter count, adaptation time, and deployment performance, with comparisons against suitable baselines such as frozen-feature extraction and full fine-tuning. Engineers must also test for overfitting, domain generalization, capability regressions, and architecture-specific limitations, because smaller adapters do not automatically provide better predictions or faster inference. By selecting ranks and target modules empirically and validating specialized models under realistic operating conditions, teams can determine whether low-rank adaptation provides a reliable efficiency advantage for their target applications.
Conclusion: Making Specialized Model Adaptation More Efficient
Low-rank adaptation offers machine learning engineers a practical way to specialize pretrained models without updating every parameter during fine-tuning, making it particularly valuable when training resources, GPU memory, and model-maintenance costs are important constraints. Instead of modifying the entire pretrained weight matrix, LoRA learns a compact update represented by two smaller matrices whose product approximates the required change, allowing the original weights to remain frozen in the standard implementation. This approach can reduce the number of trainable parameters and the associated optimizer-state requirements while preserving the pretrained model as a foundation for multiple specialized applications.
Although LoRA is widely associated with large language models, its underlying principles can also apply to compatible computer vision, speech recognition, recommendation, and time-series architectures. A pretrained vision transformer, for example, can use LoRA to adapt selected projection layers for a specialized image classification task, while a speech model may use low-rank updates to accommodate a target language or acoustic environment. Recommendation and forecasting systems can also benefit when their architectures contain suitable trainable transformations and the pretrained representations provide a useful foundation, although the effectiveness of adaptation depends on the structure of the model, the quality of the target data, and the degree of specialization required.
Successful implementation requires careful selection of target modules, rank, scaling configuration, and training objectives, because these decisions influence the balance between adaptation capacity, parameter efficiency, and predictive quality. A low rank can provide substantial parameter savings but may restrict the model's ability to represent important changes, while a higher rank increases flexibility at the cost of additional trainable parameters and memory. Engineers should therefore compare multiple configurations against suitable baselines, including frozen feature extraction and full fine-tuning, using task-specific metrics and consistent experimental conditions to establish whether LoRA offers a meaningful advantage for the target application.
It is equally important to recognize that reducing trainable parameters does not automatically make the entire model smaller, faster to execute, or cheaper to serve. The frozen backbone must still be stored and generally participates in inference, meaning that LoRA's primary benefits concern adaptation efficiency rather than guaranteed reductions in end-to-end inference latency. Combining LoRA with quantization, efficient execution, or other model optimization techniques may provide additional benefits, but the resulting implementation must be evaluated for numerical behavior, memory use, training stability, and actual production performance rather than assuming that multiple efficiency techniques always produce additive improvements.
Ultimately, LoRA is most useful when a pretrained model already captures substantial knowledge relevant to the target task and a comparatively compact update can provide the required specialization. Engineering teams should evaluate its value across the complete model lifecycle, including training cost, adaptation quality, generalization, artifact management, inference behavior, and ongoing maintenance. By comparing LoRA with alternative adaptation strategies and measuring the outcomes that matter to the application, organizations can determine where parameter-efficient fine-tuning provides a sustainable advantage without assuming that one adaptation method is suitable for every architecture or workload.
Frequently Asked Questions
1. What Is Low-Rank Adaptation in Machine Learning?
Low-rank adaptation, commonly called LoRA, is a parameter-efficient fine-tuning technique that adapts a pretrained neural network by learning a compact update to selected weight matrices while keeping the original weights frozen in the standard implementation. Rather than optimizing every element of a large weight matrix, LoRA represents the update through two smaller trainable matrices, reducing the number of parameters that must be optimized while allowing the model to learn task-specific behavior.
2. How Does LoRA Work Mathematically?
Suppose a pretrained layer uses a weight matrix (W), and conventional fine-tuning would learn an unrestricted update (\Delta W) to that matrix, whereas LoRA approximates the update through the product of two smaller matrices, (A) and (B). The resulting weight transformation is commonly written as (W' = W + \frac{\alpha}{r}BA), where (r) represents the rank and (\alpha) is a scaling parameter, although implementations can use different scaling conventions and initialization choices.
3. Why Is LoRA Considered Parameter-Efficient Fine-Tuning?
LoRA is considered parameter-efficient because it reduces the number of parameters that must be updated during adaptation, often lowering gradient storage and optimizer-state memory requirements compared with full fine-tuning. Since the pretrained weights remain frozen in the standard approach, engineers can train relatively small task-specific updates while retaining the original model as a shared foundation, although the memory required for the backbone and intermediate activations remains relevant.
4. How Does LoRA Differ From Full Fine-Tuning?
Full fine-tuning updates the pretrained model's parameters broadly, providing considerable flexibility when the target task requires substantial changes to learned representations, while LoRA updates selected low-rank parameterizations and keeps the original weights frozen. LoRA can reduce trainable parameter count and training-related memory requirements, but full fine-tuning may perform better when extensive adaptation is necessary, so the choice should be based on comparative evaluation rather than parameter efficiency alone.
5. Can LoRA Be Used for Computer Vision Models?
LoRA can be applied to compatible computer vision architectures, including vision transformers and other models containing suitable linear or projection layers, allowing engineers to adapt pretrained representations to specialized image tasks. Applications may include industrial defect detection, domain-specific image classification, and visual recognition under different acquisition conditions, although the appropriate target modules and rank depend on the model architecture and the amount of change required by the target domain.
6. How Can LoRA Adapt Speech and Audio Models?
LoRA can specialize compatible speech and audio models by introducing low-rank updates into selected projections or other supported transformations, allowing the model to adapt to target languages, accents, vocabularies, or acoustic environments. The effectiveness of this approach depends on the quality and diversity of the training data, the architecture's capacity to represent the required changes, and whether the selected modules influence the parts of the model responsible for the target task.
7. Is LoRA Useful for Recommendation Systems and Time-Series Models?
LoRA may be useful for recommendation systems and time-series models when their architectures contain suitable weight matrices and their pretrained representations provide a strong starting point for the target task. Recommendation applications may require specialization for particular user populations or product domains, while forecasting systems may need adaptation to specific sensor environments or operating patterns, although models that rely heavily on newly learned embeddings or substantial architectural changes may require additional adaptation methods.
8. What Determines the Appropriate LoRA Rank?
The appropriate LoRA rank depends on the target task, model architecture, available training data, selected modules, and the amount of adaptation capacity required to achieve acceptable performance. A smaller rank reduces the number of trainable parameters but may limit the complexity of the learned update, whereas a larger rank provides more flexibility while increasing parameter count and related training costs, making controlled experiments across several configurations the most reliable way to determine a suitable setting.
9. Which Model Layers Should Be Adapted Using LoRA?
The appropriate target layers depend on where task-specific changes are most useful within the model's architecture, with transformer-based models often using attention projections or feed-forward layers and other architectures requiring different choices. Engineers should inspect the model structure, identify relevant weight matrices, and compare different target-module configurations against a consistent baseline, because adapting more layers can increase capacity but may also increase resource requirements without producing proportional improvements.
10. How Much Training Memory Can LoRA Save?
LoRA can reduce the memory needed for trainable parameters, gradients, and optimizer states because the standard implementation freezes the original weights and updates only the low-rank matrices. The actual memory savings depend on the base-model size, rank, selected modules, optimizer, batch size, activation storage, and training framework, so teams should measure peak GPU memory instead of assuming a fixed reduction percentage across all workloads.
11. Does LoRA Improve Inference Speed?
LoRA primarily reduces the cost of adapting a pretrained model rather than automatically improving inference latency, because the original backbone generally still needs to execute during prediction. Keeping adapters separate may introduce additional operations, while merging the learned updates into compatible base weights can avoid separate adapter computations in supported implementations, although actual performance depends on the model architecture, runtime, hardware, and serving configuration.
12. Can LoRA Be Combined With Quantization?
LoRA can be combined with quantization, including approaches that keep a pretrained backbone in a lower-precision representation while training low-rank updates, potentially reducing the memory required to adapt large models. However, quantization and LoRA address different aspects of efficiency, and their combination must be evaluated for supported operations, numerical stability, task performance, training memory, and serving behavior rather than assuming that the benefits will automatically multiply.
13. How Should Engineers Evaluate LoRA Against Full Fine-Tuning?
Engineers should compare LoRA with full fine-tuning, frozen feature extraction, and other relevant approaches using consistent training data, validation procedures, and task-specific metrics. The comparison should include predictive quality, generalization, training time, peak memory, trainable parameter count, and relevant inference measurements, allowing teams to determine whether the resource savings from LoRA justify any differences in model quality or operational complexity.
14. How Can Multiple LoRA Adapters Be Managed in Production?
Multiple adapters can be managed by maintaining a shared pretrained backbone and separate versioned adapter artifacts for different tasks, domains, or customer requirements, with request routing selecting the compatible adapter for each inference request. Reliable deployment requires tracking base-model compatibility, preprocessing versions, evaluation results, and runtime dependencies, while load testing should assess adapter switching, memory usage, concurrency, and latency when many specialized tasks share the same serving infrastructure.
15. When Should an Organization Choose LoRA for a Specialized ML Task?
An organization should consider LoRA when a pretrained model already provides useful representations for the target task and the required specialization can be achieved through a relatively compact update to selected parameters. It is particularly attractive when full fine-tuning is constrained by memory, training budget, or the cost of maintaining multiple specialized models, but teams should first establish the expected benefits through comparative evaluation because full fine-tuning, frozen feature extraction, or another adaptation method may be more suitable for some architectures and tasks.