Section 1: Why Traditional Data Augmentation Is Not Enough for Modern Machine Learning
Machine learning models are often limited not by the amount of data available, but by the quality and diversity of the examples represented in that data. A training dataset may contain millions of observations while still failing to capture rare events, unusual combinations of features, emerging behaviors, or difficult edge cases. Traditional data augmentation can increase the number of training examples, but it does not always solve these deeper coverage problems.
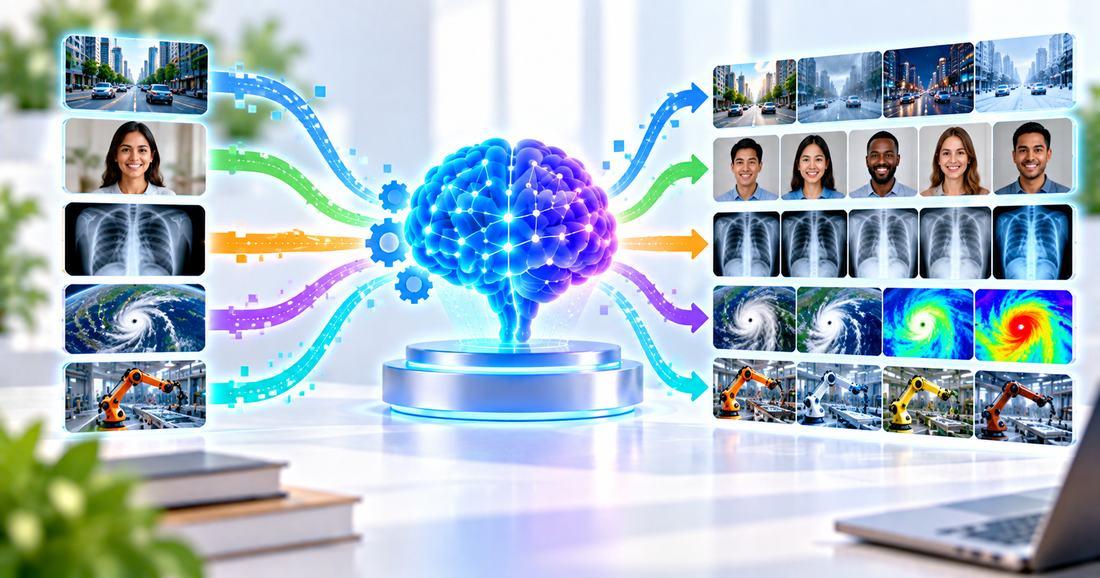
Synthetic data generation offers a different approach. Instead of simply modifying an existing example, machine learning models can learn the underlying characteristics of a dataset and generate new observations that resemble the original data while introducing additional variation.
The distinction matters because modern AI systems increasingly need to perform reliably outside the most common conditions represented in historical datasets.
Traditional Augmentation Changes Existing Examples
Data augmentation typically begins with a real observation and applies transformations that are expected to preserve its underlying meaning.
An image can be rotated, cropped, resized, or adjusted for brightness. A sensor signal can sometimes be perturbed with realistic noise. A text example may be transformed through carefully controlled paraphrasing.
These techniques are useful because they create additional training examples without requiring new data collection.
However, augmentation generally remains close to the original observation.
A photograph of a damaged machine can be rotated, but the transformation does not create an entirely new type of physical defect. A customer transaction can be slightly modified, but that does not necessarily produce a new behavioral pattern. A time-series signal can be perturbed, but the resulting sequence may still represent essentially the same event.
This creates a limitation when the missing information is not simple variation, but new combinations or underrepresented scenarios.
Synthetic data generation approaches the problem differently by learning patterns across many observations and using those patterns to produce entirely new samples.
This broader distinction connects with “Data-Centric AI: Why Improving Your Dataset Can Beat Changing Your Model” Improving the dataset does not always mean collecting more real examples. It can also mean creating training data that better represents the situations a model needs to understand.
Real Datasets Often Miss Important Cases
Many machine learning datasets contain an imbalance between common and rare events.
Fraudulent transactions may represent only a small fraction of all transactions. Equipment failures may be uncommon compared with normal operating states. Certain medical conditions may have relatively few observations. Rare defects may appear only occasionally in manufacturing data.
This creates a difficult learning problem.
A model can achieve high overall performance by learning the dominant patterns while remaining weak on precisely the cases that matter most.
Collecting more examples of rare events can be expensive or practically impossible. In some environments, deliberately creating failures or waiting for sufficient real incidents is not a viable strategy.
Synthetic data can help by generating additional examples that reflect the characteristics of underrepresented classes or scenarios.
However, the generator must learn meaningful variation rather than simply producing repetitive copies of existing examples. If synthetic observations lack diversity, the additional data may increase dataset size without increasing useful information.
The goal is therefore not to balance the number of records mechanically.
It is to improve the coverage of the underlying problem space.
Synthetic Data Can Create Scenarios That Are Difficult to Collect
Some machine learning applications require training examples from environments that are expensive, dangerous, rare, or still emerging.
Autonomous systems may need unusual road situations.
Industrial models may need examples of uncommon equipment failures.
Cybersecurity systems may need examples of attack patterns that are difficult to collect safely.
Robotics systems may need large numbers of environmental variations that would be expensive to reproduce physically.
Synthetic generation provides a way to create controlled scenarios without waiting for every condition to occur naturally.
The generated data can potentially vary environmental conditions, object configurations, temporal patterns, or combinations of attributes while preserving known relationships.
This makes synthetic data particularly valuable when the challenge is not simply insufficient data volume but insufficient scenario diversity.
Synthetic Data Must Preserve Useful Relationships
Generating realistic-looking records is not enough.
A synthetic dataset needs to preserve the relationships that matter for the downstream task.
Consider a tabular dataset containing income, age, employment status, and credit behavior. A generator might produce records with realistic values for each individual feature while creating unrealistic combinations between those features.
Similarly, a synthetic time series might resemble real sensor measurements individually while failing to preserve the correlations and temporal dependencies between sensors.
For images, a generated sample may look visually convincing while containing subtle artifacts that a model learns as shortcuts.
This is why synthetic-data quality must be evaluated statistically and operationally.
Engineers need to determine whether distributions, correlations, temporal structures, class relationships, and important edge cases are preserved sufficiently for the intended use.
Key Takeaway
Traditional data augmentation creates additional examples by modifying existing observations, while synthetic data generation attempts to learn underlying data patterns and create genuinely new samples. This makes synthetic data potentially valuable for rare events, difficult-to-collect scenarios, and underrepresented regions of the problem space. The real objective is not simply to generate more records, but to increase useful data diversity while preserving the relationships and characteristics required by downstream machine learning models.
Section 2: How Machine Learning Models Generate Synthetic Data
Synthetic data generation begins with a fundamentally different objective from traditional augmentation. Instead of applying a predefined transformation to an existing observation, a generative model learns statistical, structural, or semantic patterns from real data and uses that learned representation to produce new observations. The generated examples are artificial, but they are designed to resemble the characteristics of the real population closely enough to support a particular machine learning objective.
Different data types require different generation strategies. Tabular records, images, text, and time-series data each have distinct structures that the generative model needs to preserve.
Generative Models Learn the Structure of Real Data
The first step in synthetic data generation is learning a useful representation of the original dataset.
A generative model observes real examples and attempts to learn the relationships that make those examples plausible. Depending on the architecture, it may learn distributions directly, compress observations into a latent representation, or progressively construct new samples from noise.
Generative adversarial networks, or GANs, use two competing components: a generator creates synthetic samples while a discriminator attempts to distinguish generated data from real examples. Through this competition, the generator is encouraged to produce increasingly realistic outputs.
Variational autoencoders, or VAEs, learn a structured latent representation of the data and generate new samples by sampling from that learned representation.
Diffusion models use a different process. They gradually transform data into a noisy representation during training and learn how to reverse that process to generate new samples. This approach has become particularly influential for high-dimensional data such as images and increasingly for other modalities.
Transformer-based generative models can learn relationships across sequences, making them useful for text, event streams, and some forms of structured and temporal data.
The architecture matters, but the underlying objective is similar: learn enough of the data-generating structure to produce plausible new observations.
Tabular and Time-Series Data Require Relationship Preservation
Generating synthetic tabular data is more difficult than simply sampling each column independently.
Consider a customer dataset containing age, income, occupation, account activity, and purchasing behavior. Each individual feature may have a realistic distribution, yet independently sampled columns can create combinations that are statistically or logically implausible.
A useful synthetic-data model therefore needs to capture dependencies between variables.
The same challenge becomes even more important for time-series data.
A synthetic equipment signal should preserve not only the distribution of individual measurements but also temporal patterns, correlations between sensors, trends, seasonality, and meaningful changes in system state.
A sequence that looks realistic at each individual timestep may still be unrealistic when viewed over a longer period.
This means synthetic data generation should be evaluated at the level of relationships and structure rather than only individual feature distributions.
For complex datasets, the useful output is not merely a collection of realistic-looking records.
It is a collection of records that behaves like the original data-generating system in the ways that matter for the downstream application.
Conditional Generation Enables Targeted Synthetic Data
One of the most useful capabilities of modern generative systems is conditional generation.
Instead of asking a model to generate arbitrary samples, engineers can specify characteristics that the synthetic data should contain.
A manufacturing system might request synthetic examples representing specific equipment failures. A vision model might require images containing particular object classes or environmental conditions. A fraud-detection system might need examples with particular transaction patterns or rare combinations of behaviors.
Conditional generation can therefore be used to target underrepresented areas of the training distribution.
This is particularly valuable when the primary problem is class imbalance or insufficient coverage of specific scenarios.
However, conditioning creates another potential failure mode.
If the generator is not sufficiently capable, it may produce samples that satisfy the requested label while introducing artifacts or unrealistic relationships. A synthetic “fraudulent” transaction may technically belong to the correct class but fail to resemble real fraudulent behavior.
The generated data must therefore be validated against real examples and domain expectations.
Synthetic Data and Model Training Form a Feedback Loop
Synthetic data is usually generated for another machine learning model, which creates an important evaluation question: does the synthetic data actually improve the downstream system?
A generator can produce highly realistic samples according to statistical metrics while providing little benefit to the predictive model.
In some cases, synthetic examples may even reduce performance if they contain artifacts that encourage the downstream model to learn incorrect patterns.
This is why synthetic-data evaluation should include downstream testing.
Engineers can train models on real data alone and compare them with models trained using carefully selected combinations of real and synthetic data. They can then evaluate whether synthetic augmentation improves generalization, rare-event performance, robustness, or another specific objective.
The synthetic dataset should be treated as a component of the machine learning pipeline rather than as an end product whose quality can be judged independently of its intended use.
This connects with “Knowledge Distillation: How Smaller Models Learn From Larger AI Systems,” because both approaches highlight an important engineering principle: generated or transformed information is valuable only when the information transferred to the downstream system remains useful for the intended task.
Key Takeaway
Machine learning models generate synthetic data by learning the structure of real datasets and producing new observations through approaches such as GANs, VAEs, diffusion models, and generative transformers. Effective generation must preserve relationships between variables, temporal dependencies, and domain-specific structure rather than merely matching individual feature distributions. Conditional generation can improve coverage of rare scenarios, but synthetic data should ultimately be judged by whether it improves downstream model performance without introducing artificial patterns or misleading correlations.
Section 3: Designing Synthetic Datasets That Improve Real-World ML Performance
Generating synthetic data is technically impressive, but generation alone does not guarantee better machine learning. A synthetic dataset can look realistic while failing to improve downstream performance, reproducing unwanted biases, or introducing artifacts that cause models to learn patterns that do not exist in the real world.
For this reason, synthetic data should be treated as an engineering component of the ML pipeline. The goal is not to maximize the number of generated examples, but to create synthetic observations that address a clearly identified weakness in the real training data.
Identify the Data Gap Before Generating Anything
The first step is understanding what the original dataset is missing.
A dataset may lack sufficient examples of rare events, contain too few observations from certain populations, provide limited environmental variation, or fail to represent emerging scenarios. Synthetic generation should target these specific gaps rather than simply producing more examples of what already exists.
Suppose a fraud-detection dataset contains millions of legitimate transactions but relatively few confirmed fraud cases. Generating additional generic transactions will provide little value. A better approach would focus on producing realistic variations of fraud scenarios while preserving relationships between transaction amount, account behavior, timing, location, and other relevant variables.
Similarly, a computer-vision system may perform well under normal lighting but poorly under nighttime or partially obstructed conditions. Synthetic generation can target those environmental conditions rather than duplicating ordinary images.
This makes synthetic data fundamentally different from simple dataset expansion.
The question is not “How much more data can we create?”
It is “Which missing parts of the problem should the synthetic data help represent?”
This perspective is particularly important for rare-event modeling and aligns with “How Machine Learning Teams Handle Rare Events and Extreme Class Imbalance” Synthetic data can be valuable when real examples of critical events are difficult to obtain, but the generated cases still need to reflect plausible variations of the underlying phenomenon.
Validate Statistical and Behavioral Realism
Once synthetic data has been generated, engineers need to evaluate whether it resembles the real population in the ways that matter.
Simple feature-level comparisons can provide an initial check. Engineers can compare distributions, ranges, category frequencies, missingness patterns, and basic summary statistics between real and synthetic datasets.
However, matching individual distributions is not enough.
Relationships between variables also need to be evaluated. Correlations, conditional distributions, feature interactions, class relationships, and temporal dependencies can reveal whether the generator has learned the underlying structure.
For time-series data, validation becomes even more important. Engineers may need to compare autocorrelation, seasonality, cross-series relationships, event frequency, and longer-term sequence behavior.
Visual realism can also be misleading in image-based applications. A generated image may appear convincing to a human while containing subtle artifacts that are highly predictive to a downstream model.
This is why synthetic-data evaluation should operate at multiple levels.
The dataset should be statistically plausible, structurally consistent, and appropriate for the intended machine learning task.
Measure Whether Synthetic Data Improves the Downstream Model
The strongest test of synthetic data is whether it creates measurable value.Engineers can establish a baseline model trained entirely on real data and then compare it with models trained using different proportions of synthetic data.The experiments might compare real-only training, real plus synthetic training, and synthetic-heavy training across the same validation and test datasets.The evaluation should focus on the problem the synthetic data was intended to solve.If synthetic data was generated to improve rare-event detection, the relevant question is whether performance on rare cases improves.If it was generated to increase robustness, the relevant question is whether the model performs better under realistic distribution changes or difficult conditions.If it was generated to address limited data availability, engineers should measure whether comparable performance can be achieved with less real-world data.This downstream perspective prevents teams from confusing generator quality with business value.A synthetic dataset can score well on statistical similarity metrics and still provide no meaningful improvement to the actual model.
Conversely, a dataset that is not perfectly identical to the real distribution can still be useful if it adds meaningful coverage of important edge cases.
Prevent Synthetic Artifacts, Bias, and Feedback Loops
Synthetic data introduces a new risk: models can learn artifacts created by the generator itself.
If synthetic images contain subtle visual patterns that are absent from real images, a downstream classifier may learn those patterns rather than the intended visual features.
In tabular data, a generator may create unrealistic combinations that become predictive of the target.
In time-series data, a synthetic process may accidentally produce overly smooth signals or repetitive patterns.
Once a downstream model learns these artifacts, the problem can become difficult to detect because performance on synthetic validation data may remain strong.
Bias can also be amplified. If the original training dataset underrepresents a population or contains systematic errors, a generative model trained on that dataset can reproduce those weaknesses at scale.
Synthetic data should therefore supplement trustworthy real data rather than automatically replace it.
Key Takeaway
Effective synthetic data generation starts by identifying a specific gap in the real dataset, then generating targeted examples that address that gap without introducing unrealistic structure or artifacts. Engineers should validate synthetic data at the feature, relationship, temporal, and downstream-model levels. The strongest evidence of value comes from measurable improvements in the intended ML task, while continuous comparison with real data is necessary to prevent generated artifacts, amplified bias, and synthetic-only patterns from entering production models.
Section 4: Why Synthetic Data Could Transform the Future of Machine Learning
Synthetic data is evolving from a specialized technique for increasing dataset size into a broader strategy for building machine learning systems that can learn from scenarios that are difficult, expensive, rare, or sensitive to collect in the real world. As generative models become more capable, synthetic data could influence how organizations approach model development, testing, privacy, simulation, and deployment.
The important shift is that synthetic data can become part of the data-generation strategy itself, rather than simply serving as an augmentation technique applied at the end of a traditional pipeline.
Synthetic Data Can Expand the Reach of Machine Learning
One of the biggest opportunities is making machine learning practical when real-world examples are limited.
A newly deployed machine may have only a small amount of historical telemetry. A new product may have little customer interaction history. A rare manufacturing defect may occur too infrequently to provide enough training examples. An autonomous system may need examples of dangerous scenarios that cannot safely or economically be reproduced repeatedly.
Synthetic generation can help fill these gaps by creating additional plausible scenarios before sufficient real-world data becomes available.
This does not eliminate the value of real observations.
Instead, synthetic examples can provide coverage while the real system continues generating authentic data. Over time, real observations can be incorporated into the training process and used to evaluate whether the synthetic distribution remains useful.
This creates a more flexible development cycle in which organizations do not have to wait for every important scenario to occur naturally before building a model.
Synthetic Data Could Change Privacy and Data Collaboration
Sensitive data is another area where synthetic generation could become increasingly valuable.
Organizations may have data that is useful for model development but difficult to share broadly because it contains personal, confidential, or proprietary information. A synthetic dataset can potentially reproduce some statistical and structural characteristics of the original population without simply distributing the original records.
However, synthetic data should not automatically be treated as anonymous.
A generator can potentially memorize or reproduce unusual training examples, and sensitive information may remain inferable depending on how the system was trained and evaluated. Privacy-preserving synthetic-data pipelines therefore need appropriate controls and privacy testing.
When designed carefully, synthetic datasets can support software development, experimentation, testing, and collaboration while reducing the need to expose production records directly.
This makes synthetic generation a complementary technology to privacy-preserving machine learning rather than a universal replacement for it.
Synthetic Data Could Enable Scenario-Based AI Development
Perhaps the most transformative opportunity is the ability to deliberately construct difficult scenarios.
Traditional datasets primarily reflect what has already happened. Synthetic generation can allow engineers to ask what would happen under conditions that are uncommon or not yet observed.
A cybersecurity team can generate variations of attack patterns. A robotics team can construct different environmental configurations. An industrial team can simulate combinations of operating conditions and equipment states. A computer-vision team can create controlled variations in lighting, occlusion, or object placement.
This creates a more deliberate approach to model development.
Instead of waiting for the dataset to contain every important scenario, engineers can identify weaknesses and generate targeted examples designed to test them.
The resulting workflow is closely connected to “The Hidden Role of Baselines in Successful Machine Learning Projects” Synthetic data is most valuable when it is used to solve a measurable modeling problem and its contribution is evaluated against a strong real-data baseline rather than assumed to improve performance simply because additional examples were created.
Key Takeaway
Synthetic data could transform machine learning by expanding access to rare scenarios, supporting development where real data is limited or sensitive, and enabling deliberate generation of difficult conditions for training and testing. Its greatest long-term value will come from combining synthetic and real observations rather than replacing one with the other. Successful organizations will use synthetic data to target measurable gaps in coverage, improve robustness, and accelerate development while continuously validating generated information against real-world behavior.
Conclusion
Synthetic data generation is becoming an increasingly important part of modern machine learning because organizations often face a fundamental data problem: the examples required to build reliable models are difficult to collect, label, share, or generate naturally.
Traditional data augmentation provides a useful solution by modifying existing observations. Images can be cropped or rotated, signals can be perturbed, and other transformations can create additional training examples. However, these approaches generally remain close to the original observations.
Synthetic data generation takes a broader approach.
Generative models can learn patterns and relationships within real datasets and then create new observations that reflect those characteristics. This can help expand dataset diversity, address underrepresented scenarios, support rare-event modeling, and create controlled examples that may be difficult to obtain from the real world.
The distinction is important.
The goal is not simply to generate more records.
The goal is to generate useful information that improves machine learning performance.
This makes synthetic data especially valuable when real-world observations are scarce. A manufacturing organization may have very few examples of a particular equipment failure. A cybersecurity team may lack enough historical examples of an emerging attack pattern. An autonomous system may need to test dangerous scenarios that cannot be safely reproduced repeatedly. A newly launched product may have limited historical customer data.
In such situations, synthetic generation can help expand the space of scenarios available during model development.
However, synthetic data introduces its own risks.
A generator can reproduce biases contained in its training data. It can create unrealistic relationships between features. It can introduce artifacts that downstream models learn as shortcuts. It can generate visually convincing observations that are statistically or physically incorrect.
This means synthetic data cannot be evaluated simply by asking whether the generated examples look realistic.
Engineers need to examine whether important distributions, relationships, correlations, temporal structures, and class characteristics are preserved.
More importantly, they need to determine whether the synthetic data improves the intended downstream task.
This is the strongest test of synthetic-data value.
A model trained on real data can be compared with a model trained using carefully selected combinations of real and synthetic examples. If synthetic data was generated to improve rare-event performance, the evaluation should focus on rare-event detection. If it was designed to improve robustness, testing should examine performance under difficult or shifted conditions.
The generator itself is not the final product.
The downstream machine learning system is.
Another important consideration is privacy.
Synthetic data can potentially reduce the need to distribute sensitive production records directly, which can be useful for development and collaboration. However, synthetic data should not automatically be assumed to be private or anonymous. Generative models can sometimes memorize or reproduce characteristics of their training examples.
Privacy-aware synthetic-data generation therefore requires appropriate evaluation and, where necessary, privacy-preserving techniques.
The future is also likely to involve a combination of real and synthetic data rather than complete replacement of one with the other.
Frequently Asked Questions
1. What is synthetic data generation in machine learning?
Synthetic data generation is the process of using algorithms or generative models to create artificial observations that reproduce important characteristics of real-world data. Synthetic data can take the form of tables, images, text, time-series sequences, transactions, or other structured and unstructured information.
2. How is synthetic data different from traditional data augmentation?
Traditional augmentation usually modifies existing observations through transformations such as cropping, rotation, perturbation, or controlled variation. Synthetic generation attempts to learn patterns from real data and create new observations rather than simply modifying existing examples.
3. Why is synthetic data useful for machine learning?
Synthetic data can help when real examples are limited, expensive to collect, difficult to label, sensitive to share, or concentrated in a small portion of the problem space. It can increase scenario diversity and provide additional examples for specific machine learning tasks.
4. Can synthetic data help with class imbalance?
Yes. Synthetic data can be used to generate additional examples for underrepresented classes or rare events. However, the generated examples need to reflect meaningful variations of the rare class rather than simply repeating existing patterns.
5. Can synthetic data replace real training data?
Usually, it should not be assumed to replace real data completely. Real observations provide evidence about actual system behavior, while synthetic data can provide controlled variation and fill specific coverage gaps. A combination of real and synthetic data is often more useful than relying entirely on either source.
6. What machine learning models can generate synthetic data?
Different generative architectures can be used depending on the data type. Examples include generative adversarial networks, variational autoencoders, diffusion models, and transformer-based generative models. The appropriate technique depends on the structure and requirements of the dataset.
7. Can synthetic data be generated for tabular datasets?
Yes. Generative models can learn relationships between numerical and categorical variables and produce artificial records with similar statistical characteristics. Evaluation should examine both individual feature distributions and relationships between variables.
8. Can synthetic data be generated for time-series data?
Yes. Models can generate synthetic temporal sequences while attempting to preserve trends, seasonality, temporal dependencies, correlations between variables, and other sequence characteristics. The quality of synthetic time series should be evaluated over both individual observations and longer temporal patterns.
9. Can synthetic data help with rare events?
Yes. Synthetic generation can create additional examples of rare scenarios that are difficult to collect naturally, such as equipment failures, unusual transactions, cybersecurity events, or uncommon defects. The generated scenarios must still be validated for realism and usefulness.
10. How do engineers determine whether synthetic data is realistic?
They can compare real and synthetic data across feature distributions, correlations, conditional relationships, class characteristics, temporal dependencies, missingness patterns, and other domain-specific properties. Visual similarity alone is not sufficient.
11. How do engineers know whether synthetic data actually helps?
The strongest test is downstream evaluation. Engineers can compare models trained with real data alone against models trained with combinations of real and synthetic data. Improvement should be measured against the specific objective for which the synthetic data was generated.
12. Can synthetic data introduce bias?
Yes. A generative model can reproduce or amplify biases present in its training data. It can also introduce new artifacts or unrealistic relationships. Synthetic datasets therefore require their own quality and fairness evaluation rather than being assumed to be neutral.
13. Is synthetic data automatically private?
No. Synthetic data can still contain information that resembles or potentially reveals characteristics of the original training data. Privacy-preserving synthetic-data generation may require additional methods, testing, and controls depending on the sensitivity of the source data.
14. What are the biggest challenges of synthetic data generation?
Major challenges include preserving meaningful relationships, generating sufficient diversity, representing rare events realistically, avoiding generator artifacts, preventing bias amplification, maintaining temporal or structural consistency, and demonstrating measurable downstream value.
15. What is the future of synthetic data in machine learning?
Synthetic data is likely to become a complementary component of machine learning development, particularly for rare-event coverage, scenario generation, testing, privacy-sensitive workflows, and limited-data environments. The strongest systems will combine real observations with targeted synthetic examples and continuously validate synthetic data against real-world behavior.