Section 1: Why Traditional Monitoring Misses Important Production Anomalies
Static Thresholds Cannot Capture Every Unusual Behavior
Traditional production monitoring relies heavily on predefined thresholds and manually configured alerts that trigger when metrics cross specified limits. Engineers might configure alerts when CPU utilization exceeds 90%, request latency rises above 500 milliseconds, or an application's error rate surpasses a defined percentage, allowing monitoring systems to respond quickly when known failure conditions occur. Although these mechanisms remain valuable for detecting predictable problems, they can miss unusual behavior that develops while individual metrics remain within their configured limits.
Consider a service whose normal response time is approximately 40 milliseconds but gradually increases to 180 milliseconds during a period when CPU utilization remains moderate. A fixed latency threshold of 500 milliseconds would not trigger an alert, even though the unexpected increase might indicate a database bottleneck, a dependency slowdown, or a performance regression introduced by a recent deployment. Similarly, a sudden reduction in transaction volume can indicate an upstream integration failure even when the system's resource utilization and error rates appear normal.
Machine learning can help identify these deviations by learning historical behavioral patterns and comparing current observations against contextually appropriate expectations. Instead of asking only whether a metric has crossed a predefined limit, an anomaly detection system can evaluate whether the current behavior is unusual for that service, workload, time of day, or operating condition. This approach makes monitoring more sensitive to unexpected changes while allowing engineers to preserve explicit thresholds for known critical failure conditions.
Normal Production Behavior Changes With Context
Production systems rarely operate under perfectly stable conditions because traffic patterns, deployment schedules, customer behavior, infrastructure capacity, and external dependencies change over time. A request volume that appears abnormal during a quiet period may be completely expected during a product launch, while a utilization level that is acceptable for a scheduled batch workload could indicate a serious problem for an interactive service. Consequently, anomaly detection must distinguish unusual behavior from ordinary variation rather than treating every deviation from a fixed baseline as evidence of failure.
Contextual baselines can improve this distinction by comparing observations against behavior expected under similar conditions. A monitoring system can account for recurring daily traffic patterns, weekday versus weekend workloads, known maintenance windows, or differences between services with distinct performance characteristics. Time-series models and statistical techniques can help estimate these expected patterns, while contextual metadata allows the detection system to interpret whether the observed deviation is meaningful.
This approach also needs to account for legitimate changes caused by software releases, infrastructure scaling, configuration updates, and evolving customer workloads. A deployment might increase average latency temporarily while caches warm up, whereas a sustained increase after the deployment could indicate a regression requiring investigation. Anomaly detection is therefore most useful when telemetry is interpreted alongside deployment events and operational context rather than evaluated in isolation.
Individual Metrics Can Hide Problems Across the System
Many production failures do not appear as an extreme deviation in a single metric because they emerge through relationships between multiple system signals. A database may experience increasing query latency while CPU utilization remains normal, or an application may begin generating more retries without producing enough failed requests to trigger a conventional error-rate alert. When engineers examine each metric independently, these connected changes can be difficult to recognize before they begin affecting users.
Machine-learning techniques can evaluate several signals together to identify combinations of behavior that differ from established operating patterns. A model might detect an unusual relationship between incoming request volume, database connection usage, request latency, and retry counts even when none of those metrics independently crosses a configured threshold. Such multivariate analysis can provide earlier indications of congestion, resource contention, dependency failures, or other complex operational problems.
However, detecting a relationship between metrics does not automatically establish the underlying cause, because several different incidents can produce similar telemetry patterns. An anomaly detection system should therefore help engineers identify unusual behavior and narrow the scope of investigation rather than treating every model-generated alert as a definitive root-cause diagnosis. The broader principles in “Failure Modes of Modern AI Systems and How Engineers Prevent Them” are relevant because production reliability depends on understanding how failures emerge across interacting components rather than monitoring isolated signals alone.
Key Takeaway
Traditional monitoring remains essential for detecting known failure conditions, but static thresholds and isolated metrics can miss contextual, gradual, and multivariate anomalies in complex production environments. Machine learning can strengthen observability by learning normal system behavior, identifying unexpected relationships across telemetry, and adapting detection to changing workloads, provided that engineers also control false positives, correlate related signals, and connect alerts with operational context to make earlier detection genuinely useful.
Section 2: How ML Models Detect Anomalies in Production Data
Statistical Baselines and Time-Series Models Establish Expected Behavior
Anomaly detection begins with establishing what normal system behavior looks like because engineers cannot reliably identify unusual activity without understanding the patterns typically observed under comparable operating conditions. Statistical baselines provide a useful starting point by tracking metrics such as request latency, error rates, transaction volumes, CPU utilization, memory consumption, and database activity over time. Rather than relying exclusively on fixed thresholds, a system can compare recent observations against historical averages, variability, seasonal patterns, or expected ranges to identify deviations that deserve investigation.
Time-series anomaly detection extends this approach by accounting for changes that occur across time, allowing the system to distinguish recurring patterns from unexpected deviations. A service that normally experiences higher traffic during business hours, for example, should not generate the same alerts as a service experiencing an equally large traffic increase during an otherwise quiet period. Models that account for seasonality, trends, and recent observations can create context-sensitive expectations, making it easier to identify unusual changes without generating excessive alerts during predictable workload fluctuations.
The choice of baseline depends on the metric and its operating characteristics because not every production signal follows a stable distribution. Request latency may contain occasional extreme values, traffic volume may change rapidly after a deployment, and resource consumption may behave differently under distinct workload types. Engineers therefore need to evaluate whether an average, percentile, rolling window, seasonal baseline, or forecasting model represents normal behavior adequately before using its deviations to generate alerts.
Unsupervised Learning Helps Detect Previously Unseen Anomalies
Production incidents are often difficult to label consistently because engineers may have limited examples of confirmed failures, while new problems emerge in ways that were not represented in historical monitoring data. Unsupervised anomaly detection addresses this limitation by learning structural patterns in observed data without requiring every observation to be labeled as normal or abnormal. These techniques can identify observations that differ significantly from the broader population, making them useful when incident labels are scarce or operational behavior is complex.
Isolation Forest is one technique that can identify unusual observations by examining how easily individual data points can be separated through randomized partitions. Points that differ substantially from common patterns can often be isolated with fewer partitioning steps, allowing the model to produce anomaly scores without requiring a fully labeled training dataset. Engineers can apply this approach to carefully constructed feature vectors representing request characteristics, resource measurements, traffic behavior, or other signals associated with production operations.
Clustering provides another perspective by grouping observations with similar characteristics and identifying points that fall far from established groups or appear in unusually sparse regions. This can help detect unusual combinations of latency, throughput, error rates, and resource consumption that may not be obvious when individual metrics are inspected independently. However, clustering performance depends on feature representation, distance measures, scaling, and the structure of the underlying data, so an unusual point should not automatically be interpreted as a production incident.
Unsupervised models are especially useful when they supplement rather than replace established monitoring practices, because they can prioritize unusual behavior for investigation while explicit rules continue to detect known critical conditions. Their anomaly scores should therefore be evaluated against operational examples and engineer feedback, helping teams determine which deviations correspond to actionable problems rather than harmless variation.
Streaming Inference Turns Detection Into an Operational Capability
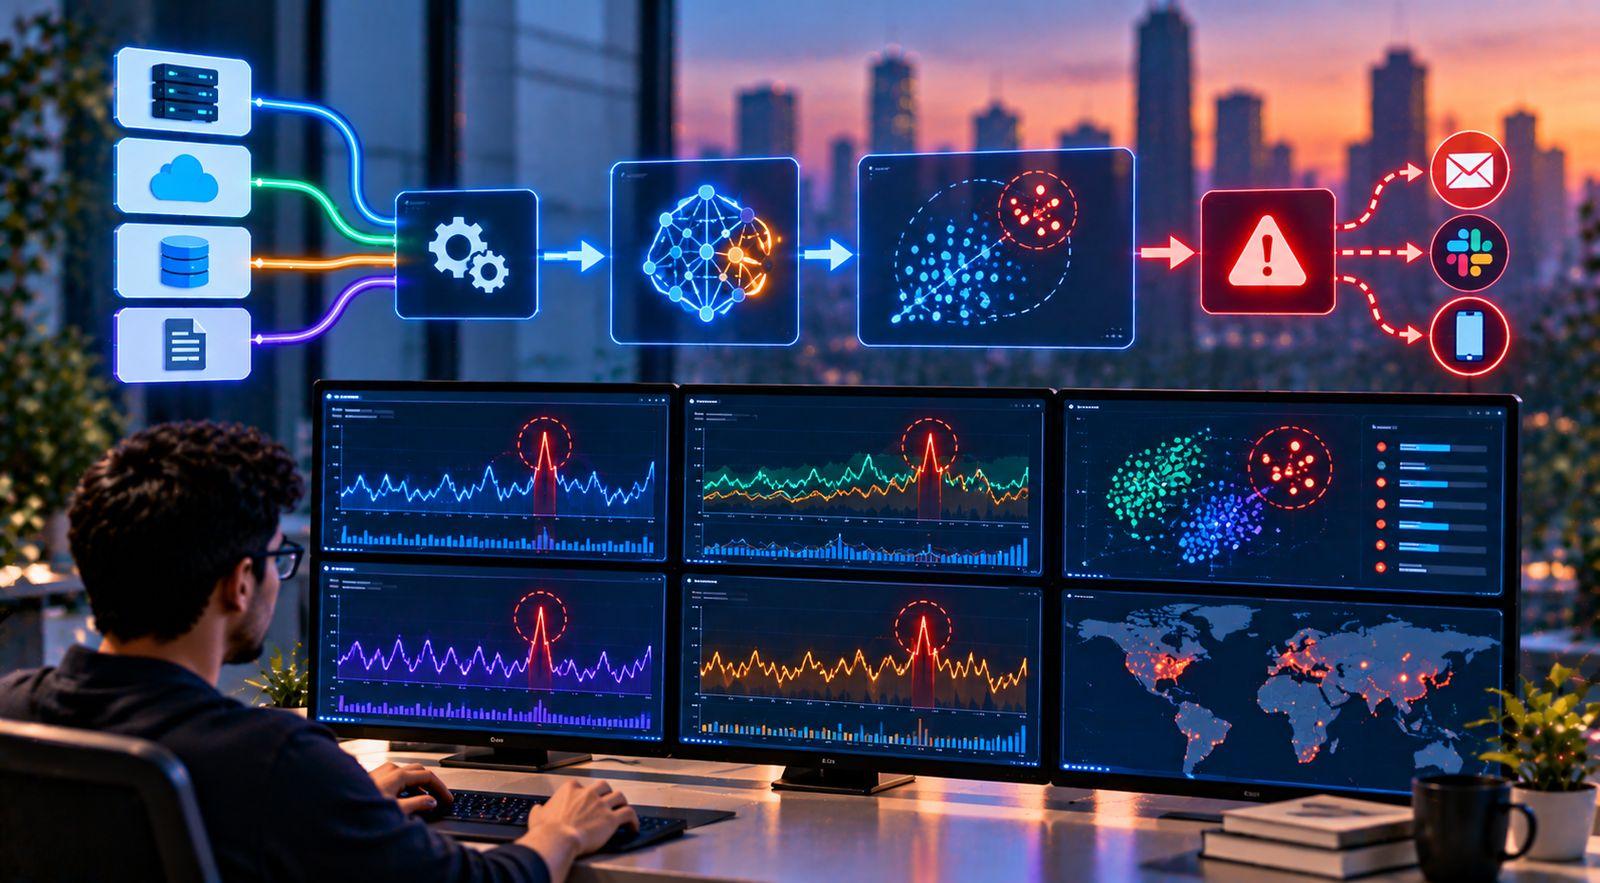
Anomaly detection becomes particularly valuable when models can evaluate incoming telemetry continuously rather than identifying problems only during retrospective analysis. A streaming detection pipeline can collect recent observations, construct features over sliding windows, update expected behavior, generate anomaly scores, and send significant deviations to an alerting or incident-management system. This allows engineers to identify unusual conditions while they are developing, potentially reducing the time between the first warning signal and the investigation of a production problem.
Streaming inference introduces operational constraints because detection must keep pace with incoming telemetry while consuming acceptable amounts of compute and memory. Engineers need to select appropriate window sizes, sampling frequencies, model complexity, and scoring intervals according to the speed at which relevant anomalies develop. Extremely short windows may create noisy alerts from ordinary fluctuations, whereas excessively long windows can smooth away brief but important failures or delay detection until a substantial amount of damage has occurred.
Threshold calibration is equally important because anomaly scores must be translated into alerts that engineers can act upon. Teams can combine model scores with service criticality, duration, deviation magnitude, and corroborating signals to prioritize anomalies, while suppressing repeated notifications for the same continuing incident. The resulting system can reduce alert fatigue by emphasizing deviations with stronger operational significance instead of treating every unusual observation as an independent emergency.
The principles discussed in “Real-Time Anomaly Detection: Engineering ML Systems That Detect Problems as They Happen” are particularly relevant because detection quality depends on the complete pipeline, including telemetry collection, feature generation, scoring, thresholding, and alert delivery. A useful production detector must therefore provide timely and meaningful signals while remaining efficient enough to operate continuously.
Key Takeaway
ML-based anomaly detection combines statistical baselines, time-series analysis, unsupervised learning, autoencoders, multivariate monitoring, and streaming inference to identify unusual production behavior that fixed thresholds may overlook. The most effective systems select techniques appropriate to their telemetry, calibrate anomaly scores against operational evidence, and integrate detection with contextual monitoring and incident investigation so that unusual behavior becomes an early, actionable signal rather than another source of alert noise.
Section 3: Building an Anomaly Detection Pipeline for Real Production Systems
Telemetry Ingestion Must Preserve the Context Behind Every Signal
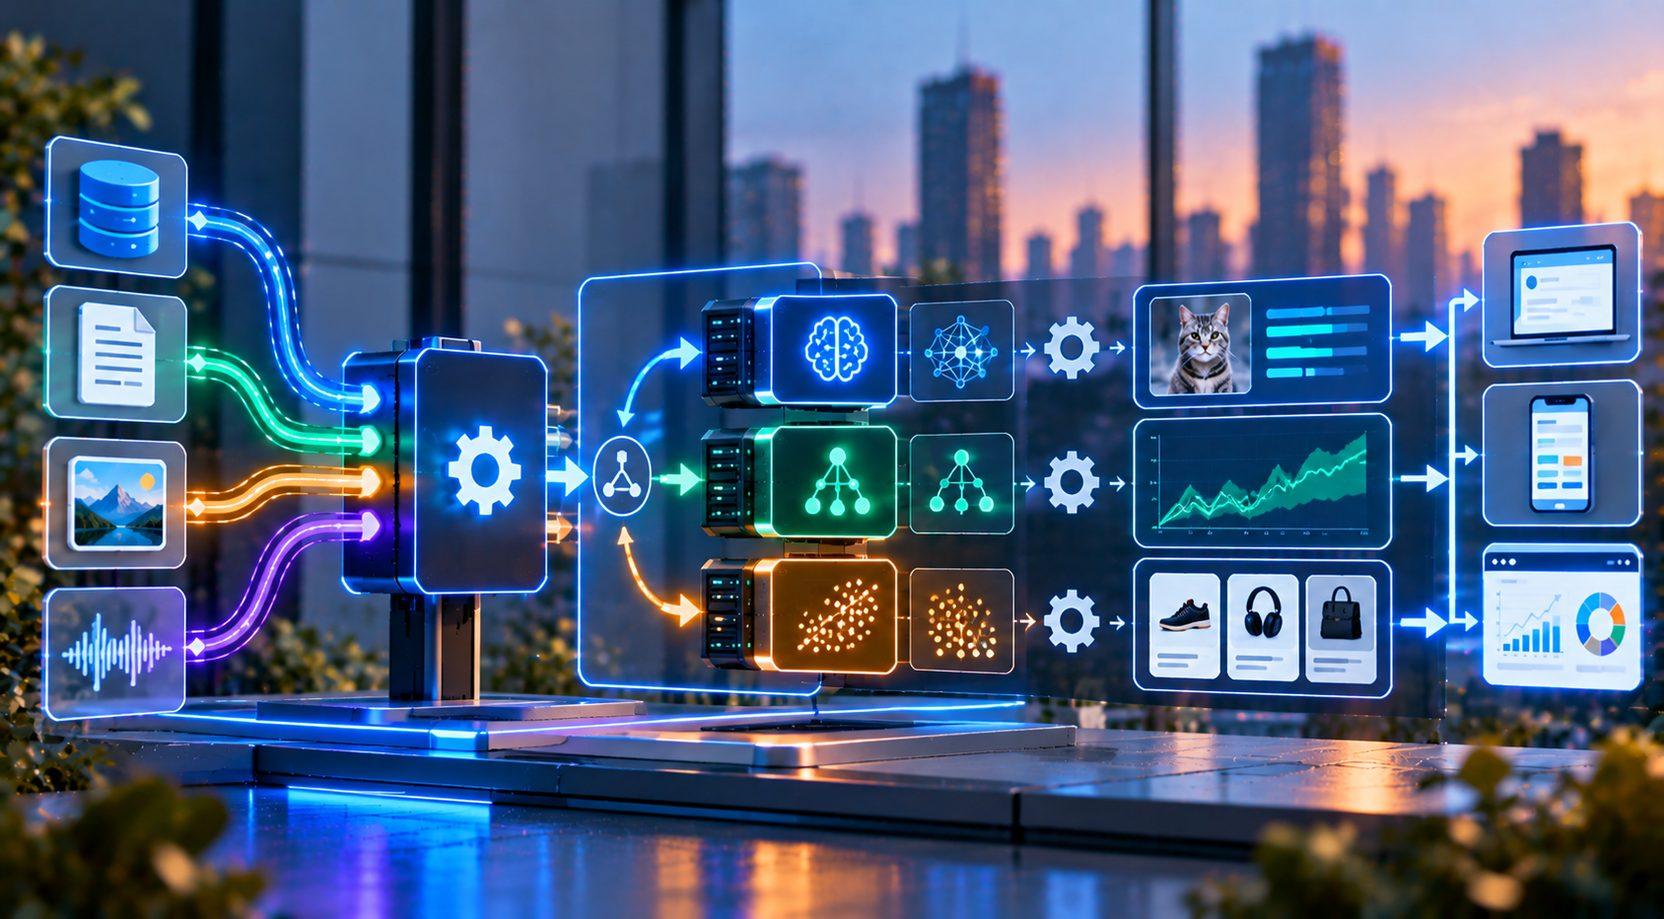
A production anomaly detection pipeline begins with reliable telemetry collection because the quality of its predictions depends on how accurately system behavior is captured, timestamped, and delivered to the detection model. Applications generate metrics, logs, traces, request events, infrastructure measurements, and deployment information at different frequencies, making ingestion architecture important for both detection accuracy and response time. Engineers need to collect these signals from relevant sources while preserving essential metadata such as service identity, environment, deployment version, region, and event timestamp so that unusual observations can be interpreted within their operational context.
Streaming platforms can process incoming events continuously, while time-series databases and observability platforms provide access to recent and historical measurements for feature generation and investigation. The architecture must account for delayed events, duplicate records, missing telemetry, and differences in sampling frequency because these problems can distort the representation of normal behavior. A detection model that interprets missing metrics as zero, for example, may generate false alerts or overlook an actual outage, making data validation and ingestion-health monitoring essential parts of the pipeline.
Feature Engineering Converts Raw Telemetry Into Useful Signals
Raw telemetry often needs to be transformed into features that represent meaningful operational behavior before an anomaly detection model can identify useful patterns. Engineers can calculate rolling averages, percentiles, rates of change, error ratios, request counts, retry frequencies, queue growth, and resource-utilization trends over appropriately selected time windows, allowing the detector to recognize changes that individual raw measurements may not reveal. Comparing current latency with a recent baseline, for example, can expose a performance regression even when the absolute value remains within a broad predefined threshold.
Contextual features can improve detection further by incorporating information about deployments, expected traffic cycles, scheduled batch jobs, service dependencies, or the criticality of the affected component. A temporary increase in CPU consumption may be expected during a planned workload, while the same increase under normal traffic could indicate resource contention or inefficient execution. Engineers should therefore ensure that the feature pipeline represents operating conditions accurately instead of expecting the anomaly model to infer every relevant contextual distinction from telemetry alone.
Feature computation must also remain efficient because expensive transformations can delay the detection process and consume resources needed by the monitored application. Sliding windows, incremental aggregation, careful sampling, and reusable feature calculations can reduce repeated processing while preserving the temporal information required for timely detection.
Observability Integration Makes Anomalies Actionable
Anomaly detection produces the greatest operational value when its outputs are integrated into existing observability and incident-response workflows rather than presented as isolated model scores. Alert records should include the affected service, anomaly score, relevant time range, baseline comparison, related metrics, and recent deployment or configuration events, allowing engineers to move from detection to investigation without reconstructing the surrounding context manually. Linking alerts to logs, distributed traces, dashboards, and dependency information can further reduce investigation time by exposing the components and requests associated with the unusual behavior.
The pipeline should also capture feedback from engineers because incident investigations provide evidence about which alerts were actionable, which represented normal variation, and which failures were missed entirely. That feedback can be used to refine thresholds, improve feature definitions, adjust contextual baselines, and evaluate whether the detection model should be retrained or replaced. However, engineer feedback should be recorded consistently because unstructured dismissal of alerts can make it difficult to distinguish a genuinely harmless event from a problem that was never investigated adequately.
Production testing remains necessary after the detection pipeline is deployed because telemetry formats, service architectures, traffic distributions, and operational expectations change over time. Engineers should monitor data-ingestion lag, scoring latency, alert volume, detection delay, false-positive frequency, and infrastructure overhead to ensure that the detector itself does not become an unreliable dependency. The principles discussed in “The Hidden Engineering Work Behind Every Successful Machine Learning Product” are relevant because effective anomaly detection depends on the surrounding data and operational infrastructure as much as the model itself.
Key Takeaway
A production anomaly detection pipeline must connect reliable telemetry ingestion, contextual feature engineering, calibrated alert thresholds, event correlation, and observability integration into a unified operational workflow. By preserving the context behind each signal, controlling false alarms without introducing excessive detection delays, and incorporating investigation feedback into continuous evaluation, engineers can turn ML-generated anomalies into actionable warnings that help identify emerging production problems before they cause widespread user impact.
Section 4: Making Anomaly Detection Reliable and Useful for Engineering Teams
Model Evaluation Must Reflect Real Production Incidents
An anomaly detection model should be evaluated according to how effectively it identifies meaningful production problems rather than how accurately it reproduces patterns in a historical dataset, because unusual observations do not automatically correspond to incidents. Engineers need representative examples of actual outages, performance regressions, dependency failures, traffic abnormalities, and harmless fluctuations to determine whether the detector can distinguish consequential anomalies from normal operational variation. When confirmed incident labels are limited, teams can combine historical incident analysis, carefully constructed scenarios, and engineering feedback to establish a useful evaluation framework without assuming that every unusual data point represents a failure.
Evaluation should account for several operational outcomes because a model that identifies every incident but generates excessive false alerts can overwhelm on-call engineers, while a conservative detector can appear reliable by avoiding alerts at the cost of missing important problems. Precision, recall, detection delay, false-alert frequency, and the proportion of incidents identified before user impact can provide complementary evidence about system effectiveness, with the most important metrics depending on the criticality of the services being monitored. Engineers should also test whether detection quality remains acceptable across different service types, traffic patterns, deployment conditions, and severity levels rather than relying exclusively on an aggregate score.
Historical evaluation alone is insufficient when the production environment changes, making controlled testing under realistic conditions an important step before deploying a new detector. Teams can replay recorded telemetry, simulate known failure scenarios, and run candidate models alongside the existing monitoring system to compare alert behavior without immediately changing incident-response workflows, allowing them to identify weaknesses in scoring, thresholds, and alert correlation before expanding deployment.
Detect Drift and Adapt to Changing System Behavior
Anomaly detection models can become less effective when the monitored environment changes because normal system behavior is not a permanent, fixed distribution. New services, infrastructure migrations, traffic growth, software deployments, and evolving usage patterns can all alter telemetry, causing a detector trained on historical observations to flag legitimate activity or overlook new forms of abnormal behavior. Engineers should therefore monitor changes in feature distributions, anomaly-score distributions, alert frequency, and confirmed incident coverage to determine whether the detector's assumptions remain appropriate for the current production environment.
Adaptation must be controlled because updating a baseline too aggressively can cause a detector to learn an emerging problem as normal behavior. If latency begins increasing gradually because of a performance regression, a system that continuously adjusts its baseline without safeguards may progressively accept the degradation and eventually stop raising meaningful alerts. A safer approach separates baseline updates from anomaly investigation, uses suitable reference windows, and applies explicit guardrails that prevent sustained or high-impact deviations from being absorbed automatically into the definition of normal operation.
Integrate Anomaly Detection Into the Engineering Lifecycle
Anomaly detection becomes more useful when it is integrated with established observability, deployment, incident-management, and reliability-engineering practices rather than maintained as an isolated ML project. Engineers should treat the detector like any other production service by monitoring its own latency, resource consumption, data-ingestion lag, scoring failures, and availability, while also checking that alerts reach the correct teams and support the expected response workflow. This prevents the monitoring system from silently becoming a new source of operational risk while attempting to detect problems elsewhere.
Deployment events and infrastructure changes should be made available to the detection pipeline because they provide valuable context for interpreting telemetry shifts. When a service's latency changes immediately after a software release, for example, correlating the anomaly with the deployment can help engineers investigate a possible regression, while the same metric change during a planned workload transition may have a different explanation. This contextual integration can improve triage even when the anomaly model cannot identify the exact root cause.
Production investigations should also strengthen future detection by recording confirmed incidents, false alarms, missed anomalies, and the evidence that helped engineers distinguish them. These findings can inform evaluation datasets, feature engineering, threshold calibration, and model updates, creating a feedback loop that improves operational usefulness over time. The broader lessons in “The Reproducibility Crisis in Machine Learning: What Engineering Teams Can Do” reinforce the importance of preserving model versions, configurations, evaluation evidence, and relevant telemetry so teams can explain why detection behavior changed and reproduce important findings.
Key Takeaway
Reliable anomaly detection requires continuous evaluation against real incidents, controlled adaptation to changing system behavior, contextual alert prioritization, and carefully governed automation that supports rather than destabilizes production operations. By integrating anomaly detection into established observability and incident-response workflows, engineering teams can reduce investigation time, improve early detection, and maintain confidence in the system as applications, infrastructure, and workloads evolve.
Conclusion
Anomaly detection for production systems is becoming an important part of modern observability because traditional monitoring mechanisms cannot always identify emerging problems through fixed thresholds and manually defined alerts. Production environments continuously change as traffic patterns evolve, software is deployed, infrastructure scales, and dependencies behave differently under varying workloads, making it difficult to define a single permanent representation of normal system behavior. Machine learning can strengthen monitoring by learning historical patterns, identifying unusual combinations of telemetry signals, and highlighting deviations that may indicate problems before they create substantial user impact.
The effectiveness of an anomaly detection system depends on more than selecting an appropriate model. Statistical baselines, time-series analysis, unsupervised learning, Isolation Forest, clustering, and autoencoders each offer different ways to identify unusual behavior, but their practical value depends on the quality of the telemetry, the relevance of the engineered features, and the operating characteristics of the monitored systems. Engineers must therefore evaluate detection techniques using representative production data and determine whether each approach provides sufficiently useful signals without introducing excessive computational overhead or alert noise.
Data engineering and observability are equally important because anomaly detection models depend on telemetry that accurately represents the system's behavior. Streaming ingestion, reliable timestamps, contextual metadata, feature aggregation, and consistent event processing allow detection pipelines to identify meaningful deviations while preserving the context needed for investigation. Without these foundations, even sophisticated models can produce misleading alerts because of missing telemetry, delayed events, incorrect feature calculations, or changes in the surrounding infrastructure.
Turning anomalies into useful operational signals requires careful alert calibration, correlation, prioritization, and integration with existing incident-response workflows. An unusual metric does not automatically represent a production incident, and several anomalous signals may originate from the same underlying failure. Engineers must therefore combine model outputs with service criticality, deployment information, dependency relationships, and corroborating telemetry to distinguish important incidents from harmless operational variation, reducing alert fatigue while preserving sensitivity to consequential problems.
Continuous evaluation is essential because the behavior that once represented normal operation can change as applications and workloads evolve. Production teams need to measure detection precision, recall, false-alert frequency, detection delay, and operational usefulness, while investigating whether changes in anomaly scores or alert volumes reflect actual incidents, legitimate workload changes, or a deterioration in the detection model itself. Feedback from incident investigations should then inform new test cases, feature improvements, and controlled model updates so that the detection pipeline becomes more effective over time.
Ultimately, the purpose of anomaly detection is not to flag every unusual observation or eliminate the need for engineers to investigate production problems. It is to identify meaningful deviations early, provide the evidence needed for investigation, and help engineering teams prioritize their attention before emerging issues develop into significant incidents. When machine learning is combined with reliable telemetry, contextual alerting, disciplined evaluation, and safe operational workflows, anomaly detection becomes a valuable extension of observability that helps production systems remain reliable as their complexity and operating conditions evolve.
Frequently Asked Questions
1. What is anomaly detection in production systems?
Anomaly detection in production systems is the process of identifying unusual patterns in application behavior, infrastructure metrics, logs, traces, traffic, or other operational data that may indicate emerging problems. Machine-learning techniques can identify deviations from historical or contextual expectations, helping engineers investigate potential incidents before they cause significant disruption.
2. How is ML-based anomaly detection different from traditional monitoring?
Traditional monitoring often relies on predefined thresholds and manually configured rules, whereas ML-based anomaly detection can learn expected behavior from historical observations and identify unusual patterns that are difficult to express through fixed conditions. The approaches complement each other because explicit rules remain useful for known failure conditions, while ML can help detect contextual, gradual, or multivariate deviations.
3. Which production metrics can machine-learning models monitor?
Anomaly detection models can analyze request latency, error rates, throughput, CPU utilization, memory consumption, disk activity, database query times, queue depth, network behavior, retry rates, and transaction volumes. The most useful signals depend on the application architecture and the operational problems engineers want to identify.
4. What is the difference between an anomaly and an incident?
An anomaly is an observation or pattern that differs meaningfully from expected behavior, while an incident is an operational event that requires investigation or corrective action. An unusual traffic spike may be legitimate, for example, whereas a smaller increase accompanied by rising errors and database latency may indicate an actual service problem.
5. Which machine-learning algorithms are commonly used for anomaly detection?
Common approaches include statistical baselines, time-series models, Isolation Forest, clustering, autoencoders, and other unsupervised or semi-supervised techniques. The appropriate method depends on factors such as available labels, telemetry characteristics, computational constraints, the relationships among monitored signals, and how quickly anomalies need to be detected.
6. How does Isolation Forest detect anomalies?
Isolation Forest identifies unusual observations by using randomized partitions to isolate individual data points. Observations that differ substantially from common patterns can often be separated with fewer partitioning steps, allowing the algorithm to generate anomaly scores without requiring a fully labeled dataset of normal and abnormal behavior.
7. What is time-series anomaly detection?
Time-series anomaly detection identifies unusual behavior in measurements collected over time, such as request latency, traffic volume, or resource utilization. It can account for trends, seasonality, recurring traffic patterns, and recent observations to detect deviations that fixed thresholds or comparisons against a single historical average might overlook.
8. What is multivariate anomaly detection?
Multivariate anomaly detection evaluates several signals together to identify unusual relationships or combinations of measurements. For example, moderately increasing latency, rising retry counts, and growing queue depth may collectively indicate an emerging dependency problem even when none of the individual metrics exceeds its configured alert threshold.
9. How can anomaly detection reduce false-positive alerts?
Engineers can reduce false positives by establishing contextual baselines, incorporating deployment and workload information, calibrating alert thresholds, requiring appropriate persistence, correlating related signals, and evaluating alerts against historical incidents. These techniques help distinguish meaningful deviations from legitimate operational variation without making the detector so conservative that it misses important failures.
10. Can anomaly detection identify problems before users are affected?
Anomaly detection can identify early changes in system behavior that may precede user-facing incidents, such as gradually increasing latency, unusual retry patterns, or growing resource contention. Its effectiveness depends on whether the monitored signals provide an early indication of the problem and whether the detection pipeline can generate actionable alerts quickly enough for engineers to respond.
11. What role does feature engineering play in anomaly detection?
Feature engineering converts raw telemetry into informative signals that represent system behavior, such as rolling averages, latency percentiles, error ratios, rates of change, queue growth, and relationships among metrics. Well-designed features help models distinguish meaningful anomalies from noise while preserving enough context to support useful alerts.
12. How should anomaly detection models be evaluated?
Engineers should evaluate models using representative telemetry and known incidents, measuring precision, recall, false-alert frequency, detection delay, and the operational importance of missed problems. Historical incident replay, controlled failure simulations, and production feedback can provide additional evidence when confirmed anomaly labels are limited or incomplete.
13. What happens when production behavior changes over time?
Changes in traffic, deployments, infrastructure, and application usage can make a previously effective anomaly detector less reliable. Engineers should monitor input distributions, anomaly-score patterns, alert frequency, and confirmed incident coverage, while updating baselines or retraining models carefully to avoid learning a developing production problem as normal behavior.
14. Can anomaly detection automatically identify the root cause of an incident?
Anomaly detection can highlight unusual behavior and help narrow the scope of an investigation, but identifying an anomaly does not automatically establish its underlying cause. Engineers typically need to combine detection results with logs, traces, dependency information, deployment records, and other contextual evidence to determine whether the problem originated from application code, infrastructure, data pipelines, or an external dependency.
15. How should anomaly detection be integrated into production observability?
Anomaly detection should integrate with telemetry ingestion, feature processing, dashboards, alerting systems, distributed tracing, and incident-management workflows so that unusual behavior can be investigated within its operational context. Engineers should monitor the detector's own latency, resource consumption, data-ingestion health, false-positive frequency, and detection effectiveness to ensure the monitoring system remains reliable and useful as production conditions evolve.