Section 1: Why Real-Time Fraud Detection Is a Different Engineering Problem
Fraud Detection Must Operate Within Transaction Latency Budgets
Traditional fraud analysis can examine historical transactions in batches, identify suspicious patterns, and investigate questionable activity after events have occurred, but real-time fraud detection must evaluate risk while a transaction is still being processed. When a customer makes a payment, the system may need to collect relevant signals, calculate features, execute a model, apply decision rules, and return an outcome before the payment workflow can continue. This creates a tightly constrained decision pipeline in which every database query, network call, feature transformation, and model operation consumes part of the available latency budget.
The challenge extends beyond making the model execute quickly because end-to-end response time depends on the entire transaction path. A classifier that produces a risk score in five milliseconds may still be unsuitable if retrieving transaction history takes another 100 milliseconds and a downstream service adds further delays. Engineers must therefore profile the complete workflow, identify its critical path, and establish latency budgets for individual components while maintaining enough capacity to handle sudden traffic increases.
Fraud detection also requires predictable performance because transaction volumes can vary significantly across merchants, markets, time periods, and customer activity patterns. Traffic bursts can increase queueing delays, overload feature services, and create contention for inference resources, making percentile latency measurements more informative than averages alone. Metrics such as p95 and p99 latency help engineers understand whether the system remains responsive for most transactions and whether a smaller fraction of requests is experiencing delays that could disrupt the payment experience.
Static Rules Cannot Capture Every Fraud Pattern
Traditional fraud systems frequently rely on explicit rules that flag transactions based on conditions such as unusually large amounts, suspicious geographic activity, repeated payment attempts, or known compromised identifiers. These rules remain useful because they are transparent, easy to audit, and effective when a specific risk pattern is already understood, but they can become difficult to maintain as fraudulent behavior changes and attackers adapt to existing controls.
Machine learning can complement rule-based detection by identifying relationships among transaction attributes, device signals, account history, behavioral patterns, and other indicators that are difficult to represent through individual rules. A transaction that appears normal when examined independently may become suspicious when considered alongside a sudden change in spending behavior, unusual device activity, or a rapid sequence of related transactions. A trained model can combine these signals into a risk score, allowing the decision system to account for patterns that would otherwise require numerous manually maintained conditions.
The strongest architecture rarely depends exclusively on either rules or ML because the two approaches solve different problems. Rules can enforce explicit business constraints and react immediately to known indicators, while predictive models can estimate risk from complex combinations of signals and previously observed examples. Combining them allows engineers to preserve transparent controls while using learned behavior to improve coverage across more complicated fraud scenarios.
This combination still requires careful evaluation because historical data may not contain examples of every emerging fraud technique, and patterns learned from previous attacks can become less useful as attacker behavior changes. The principles described in “When Machine Learning Should Not Be Used: A Guide to Better Technical Decisions” are relevant because ML should complement clear deterministic controls when those controls are effective, rather than replacing every business rule with a predictive model.
Fraud Detection Is a Continuously Changing Prediction Problem
Fraud patterns change as attackers discover new methods, customers change their behavior, payment channels evolve, and businesses introduce new products or transaction workflows. This creates a moving prediction problem in which the relationships learned from historical examples may gradually become less representative of the current environment, reducing model effectiveness even when the deployed service remains technically healthy.
Model development is further complicated by delayed labels because a transaction's true outcome may not become known until a chargeback, investigation, customer report, or other downstream event occurs. Engineers may therefore need to make real-time decisions using a model whose latest measurable quality reflects transactions from an earlier period, while newer prediction outcomes remain uncertain. This makes monitoring prediction distributions, feature statistics, decision rates, and delayed outcome metrics important for identifying potential degradation.
Fraud data also commonly presents severe class imbalance because legitimate transactions vastly outnumber fraudulent ones, making training and evaluation methods especially important.
Key Takeaway
Real-time fraud detection is a systems engineering problem that combines strict latency requirements, predictive risk scoring, explicit business rules, asymmetric error costs, and continuously changing fraud patterns. Effective production systems must optimize the complete transaction pipeline, choose decision thresholds according to business consequences, and monitor model behavior over time so that fast predictions remain useful, reliable, and appropriate as transaction patterns and attacker strategies evolve.
Section 2: Building Low-Latency Features and Real-Time Data Pipelines
Streaming Transaction Events Provide Timely Fraud Signals
Real-time fraud detection depends on how quickly a system can convert incoming transaction events into usable model features because the most informative signals may describe recent behavior rather than historical account characteristics alone. Transaction amount, merchant category, device information, account age, and geographic context can provide useful information, but patterns such as repeated payment attempts, sudden spending changes, and unusual transaction velocity often require the system to analyze events arriving continuously. Streaming pipelines allow engineers to process these events as they occur, maintain recent activity state, and make updated features available to the inference service without repeatedly scanning historical databases.
A streaming architecture can consume transaction events, update rolling aggregates, and maintain compact state representing recent customer or device behavior. For example, the system may maintain transaction counts and cumulative amounts over several time windows, allowing the model to evaluate whether a new payment differs significantly from recent activity. These features can expose suspicious patterns that would be difficult to detect by examining the current transaction independently, while avoiding the latency of recalculating every historical aggregate during the prediction request.
The challenge is ensuring that streaming computations keep pace with incoming events under realistic traffic conditions, because processing delays can make apparently recent features stale before they reach the model. Engineers need to monitor event-processing lag, duplicate events, out-of-order arrivals, failed updates, and recovery behavior so that the feature state remains reliable during traffic spikes or infrastructure interruptions. These considerations make stream processing part of the fraud detection system's decision path rather than merely an upstream analytics function.
Online Feature Retrieval Must Fit Within the Latency Budget
Even when streaming pipelines maintain useful transaction features, the inference service must retrieve the required information quickly enough to complete the decision within the transaction's response window. A fraud model may need account history, recent transaction counts, device reputation, merchant statistics, and signals derived from previous activity, but retrieving each feature independently from separate databases can introduce substantial network overhead. Online feature stores or other low-latency data services can provide a more predictable access layer by organizing frequently used features for rapid retrieval.
Feature design should therefore consider computational cost and freshness together rather than maximizing the number of available signals. A theoretically informative feature may be unsuitable for real-time scoring when it requires expensive joins, slow external lookups, or computations that cannot reliably finish within the available time. Engineers can move expensive aggregations into streaming or batch pipelines and retain only the lightweight retrieval and transformation operations needed during inference, reducing the work performed on the critical transaction path.
Feature consistency is equally important because training and inference must use compatible definitions, windows, encodings, and missing-value rules. If the training pipeline calculates transaction velocity over one time interval while the production service uses another, the model may receive values with different meanings, potentially degrading predictions without causing an obvious technical error. The principles discussed in “The Journey of a Dataset: From Raw Data to Production ML” are directly relevant because reliable predictions depend on maintaining a consistent path from raw events to the features consumed by the deployed model.
Caching and Precomputation Reduce Repeated Work
Caching and precomputation can improve fraud-scoring performance by avoiding repeated calculations for information that remains useful across multiple transactions. Account-level statistics, device reputation, merchant profiles, and selected historical aggregates may be reusable for a limited period, allowing the inference service to retrieve prepared values rather than repeatedly querying source systems or performing complex transformations. These techniques can reduce database pressure and latency, particularly when transaction volumes are high and many requests depend on the same underlying entities.
However, fraud detection requires more careful cache management than some less time-sensitive applications because recent activity can materially change a transaction's risk. If two payments arrive almost simultaneously, a delayed feature update could cause the second transaction to be scored without accounting for the first, potentially hiding a suspicious burst of activity. Engineers must therefore define freshness requirements, update strategies, and consistency guarantees for each feature, distinguishing between slowly changing attributes and signals that need near-immediate updates.
A practical architecture can combine cached historical characteristics with rapidly updated streaming features, using different refresh policies according to the risk and computational requirements of each signal. This approach avoids treating every feature as equally time-sensitive while preserving the information most important for transaction decisions. Cache invalidation, feature versioning, and monitoring should also be coordinated with model releases so that predictions are not generated from incompatible or unexpectedly stale data.
Key Takeaway
Reliable low-latency fraud detection depends on streaming transaction events, efficient online feature retrieval, carefully controlled caching, and data pipelines that preserve freshness and consistency under production load. Engineers must optimize feature computation alongside model inference because stale, missing, or delayed features can undermine the quality of a decision even when the model responds within milliseconds, making pipeline reliability a fundamental component of real-time fraud prevention.
Section 3: Designing the Model and Decision Engine for Millisecond Decisions
Selecting Models That Balance Predictive Quality and Inference Speed
A real-time fraud detection model must identify suspicious transactions accurately while operating within the strict response-time requirements of the payment workflow, making model selection an engineering decision rather than an accuracy-only exercise. Complex models can capture intricate relationships among transaction characteristics, account behavior, device signals, and historical activity, but their computational requirements may make them difficult to execute consistently under heavy transaction volume. Simpler models can offer faster predictions and easier operational management, although their ability to detect sophisticated fraud patterns may be more limited.
Engineers should therefore evaluate candidate models using both predictive and operational metrics, including precision, recall, false-positive rates, inference latency, throughput, memory consumption, and infrastructure cost. A model that performs well during offline evaluation may behave differently under production concurrency, particularly when feature retrieval and request processing compete for resources. Testing models on representative traffic and target hardware helps determine whether their predictive benefits justify their operational requirements.
Different modeling approaches can serve different responsibilities within the same fraud detection architecture, with supervised classification models learning from labeled transaction outcomes and anomaly detection techniques identifying unusual patterns that may not resemble previously observed fraud. A combined approach can use established fraud labels to recognize familiar patterns while applying anomaly signals to surface transactions that deviate substantially from normal behavior, provided both signals can be evaluated within the available latency budget.
Risk Scores and Decision Thresholds Translate Predictions Into Actions
A fraud classification model commonly produces a risk score or estimated probability that a transaction is fraudulent, but the prediction itself does not determine what the payment system should do. A separate decision engine translates the model output into an operational action by considering thresholds, business policies, transaction characteristics, and the consequences of making an incorrect decision. This separation allows the model to estimate risk while the decision layer controls how that risk affects the transaction workflow.
Threshold selection is particularly important because false positives and false negatives create different costs for the business and its customers. A low threshold may detect more fraudulent transactions but also interrupt legitimate payments, while a higher threshold may reduce unnecessary declines at the expense of allowing additional fraud to pass through. Engineers should therefore establish operating thresholds using validation data, estimated error costs, investigation capacity, and the business requirements associated with different transaction categories rather than selecting a threshold based on overall accuracy alone.
A multi-level decision policy can provide more flexibility than a single binary threshold because transactions do not always need to be approved or declined immediately. The system may automatically approve low-risk transactions, decline transactions whose risk exceeds a strict boundary, and require additional authentication or manual review for ambiguous cases, allowing the decision engine to match intervention intensity to the estimated risk. Such policies should also account for the reliability of the model's scores because poorly calibrated probabilities can lead to thresholds that do not correspond to the intended level of risk.
Combining Machine Learning With Deterministic Rules
A hybrid fraud detection architecture combines predictive model outputs with explicit rules that encode known threats, mandatory business constraints, and operational requirements. Rules can detect specific patterns such as transactions involving known compromised credentials or activity that violates predefined controls, while ML models can evaluate more complex combinations of behavioral and contextual signals that are difficult to represent through manually maintained conditions.
The decision engine must define how these sources interact because a transaction may trigger a deterministic rule while receiving a relatively low risk score from the model. Some rules may override the model for clearly prohibited activity, while others may contribute additional risk signals that influence the final decision. Keeping these responsibilities explicit improves auditability and makes it easier to investigate why a transaction was approved, declined, or sent for further verification.
Hybrid decisions also require careful management when rules and models disagree, particularly when a new rule introduces a sudden change in transaction outcomes or when a model update changes risk scores across the customer population. Engineers should evaluate the combined decision policy against representative historical cases, monitor how often individual rules and model thresholds trigger interventions, and verify that the resulting behavior stays within acceptable limits.
This approach reflects the principles discussed in “How ML Teams Choose Between Rules, Statistics, and Machine Learning,” because effective production systems use each technique where it provides the most value instead of forcing every decision through one mechanism. A well-designed fraud engine preserves the transparency of explicit controls while allowing machine learning to recognize patterns that fixed rules may fail to capture.
Key Takeaway
Real-time fraud detection depends on selecting models that balance predictive performance with inference speed, translating risk scores into carefully calibrated decisions, and combining ML predictions with deterministic controls. By optimizing the complete transaction path and defining safe behavior for uncertain predictions and infrastructure failures, engineers can make timely fraud decisions while controlling false positives, false negatives, and operational risk.
Section 4: Making Fraud Detection Reliable in Production
Monitor Model Performance Alongside Transaction Infrastructure
A production fraud detection system requires monitoring that extends beyond API availability and inference latency because a model can continue processing transactions successfully while its ability to identify fraudulent activity deteriorates. Engineers should track request volume, p95 and p99 latency, error rates, feature retrieval failures, model utilization, risk-score distributions, approval rates, decline rates, and additional-verification rates to understand how the complete transaction decision pipeline behaves under real operating conditions. Monitoring these signals together helps distinguish infrastructure problems from changes in transaction behavior or predictive quality, allowing teams to investigate a sudden increase in declined payments without automatically assuming that the model itself has become inaccurate.
Model-aware observability becomes particularly important when prediction outcomes are not immediately available, because a transaction's eventual fraud status may remain unknown until a customer reports an issue, an investigation is completed, or a chargeback arrives. During this delay, engineers can still examine changes in input features, prediction distributions, decision thresholds, and transaction segments to identify unusual behavior that warrants further investigation. However, these leading indicators should not be treated as definitive evidence of model failure because legitimate changes in customer activity can produce similar patterns without reducing predictive quality.
Delayed Fraud Labels Require Careful Evaluation
Fraud detection differs from many other classification problems because reliable labels frequently arrive after the original decision, making it difficult to measure current model performance immediately. A transaction approved today may be identified as fraudulent days or weeks later, while a transaction flagged as suspicious may eventually prove legitimate after additional verification. Evaluation systems therefore need to associate eventual outcomes with the correct transaction and model version while preserving the context that existed when the original decision was made.
Engineers can maintain evaluation datasets that are updated as trustworthy outcomes become available, allowing the team to calculate precision, recall, false-positive rates, financial losses, and other relevant metrics over appropriate observation windows. These measurements should be segmented by transaction type, merchant category, customer cohort, geography, and risk level where relevant, because aggregate performance can conceal serious weaknesses within particular groups. The system should also distinguish between transactions that have been confirmed fraudulent, transactions known to be legitimate, and transactions whose outcomes remain unresolved, preventing incomplete labels from being interpreted as definitive model errors.
The evaluation process must account for the fact that only some transactions receive extensive investigation, creating potential bias in the labels used for subsequent analysis. If the system investigates only transactions with high risk scores, the resulting dataset may contain insufficient evidence about fraudulent transactions that received low scores, making independent sampling, careful experimentation, and alternative evaluation methods important when operationally appropriate.
Adapt to Changing Fraud Patterns Without Destabilizing Decisions
Fraud detection systems must continually adapt because attackers change their techniques in response to existing controls, customer behavior evolves, and transaction environments introduce new patterns that may not appear in historical training data. This creates the distribution-shift problem described in “Machine Learning Under Distribution Shift: What Happens When the World Changes,” where a model's learned assumptions can become less representative of current conditions even when its implementation remains unchanged. Engineers should therefore monitor feature distributions, fraud rates, model scores, and confirmed outcomes to identify changes that may require investigation, recalibration, retraining, or adjustments to the decision policy.
Continuous adaptation requires careful control because automatically retraining or changing thresholds in response to short-term fluctuations can destabilize transaction decisions and create unexpected customer impact. New models should pass the same data-quality checks, offline evaluations, operational benchmarks, and controlled release procedures as other production changes, while threshold adjustments should be evaluated against the resulting trade-offs between fraud detection and false-positive rates. Teams should also account for feedback loops because the transactions selected for investigation and the decisions made by earlier models influence which outcomes become available for future training, potentially reinforcing existing blind spots.
A reliable fraud detection platform consequently combines continuous monitoring with disciplined model governance, ensuring that emerging patterns can be addressed without sacrificing reproducibility, decision traceability, or operational stability. By connecting confirmed fraud outcomes, model versions, risk thresholds, feature quality, and transaction-level decisions, engineers can improve detection over time while preserving the responsiveness required by real-time payment systems.
Key Takeaway
Production fraud detection requires continuous model-aware monitoring, evaluation that accounts for delayed labels, controlled model deployments, risk-sensitive fallback behavior, and disciplined adaptation to evolving fraud patterns. Engineers must optimize not only the speed of individual predictions but also the reliability of the complete decision process, ensuring that transactions receive timely and appropriate treatment while false positives, false negatives, infrastructure failures, and changing attacker behavior remain manageable.
Conclusion
Machine learning for fraud detection is fundamentally a real-time systems engineering challenge because the value of a prediction depends not only on its accuracy but also on whether the system can make an appropriate decision before a transaction workflow proceeds. Fraud detection platforms must process transaction events, retrieve relevant features, execute models, evaluate risk, apply decision policies, and communicate outcomes within strict latency budgets, making the entire pipeline as important as the predictive model itself.
The strongest architectures combine streaming data pipelines, low-latency feature retrieval, efficient inference, and a decision engine that translates risk scores into appropriate actions. Streaming features help models recognize recent behavioral patterns, precomputed aggregates reduce unnecessary computation, and online feature stores make useful information available without repeatedly querying historical databases. These components must maintain freshness and consistency because a fast prediction generated from stale or incorrectly constructed features can still lead to a poor transaction decision.
Model selection and threshold calibration introduce another critical engineering dimension because false positives and false negatives have different consequences for the business and its customers. A fraud detection system must identify suspicious activity without unnecessarily disrupting legitimate transactions, requiring engineers to evaluate precision, recall, false-positive rates, financial losses, and operational costs alongside inference latency. Combining machine-learning predictions with deterministic rules, additional verification, and manual review can provide more flexibility than relying exclusively on an automated binary decision.
Production reliability requires continuous monitoring because fraud patterns evolve, labels arrive late, and the behavior learned from historical transactions may become less representative of current activity. Engineers need to track model versions, feature freshness, prediction distributions, transaction outcomes, and latency while using controlled deployment strategies to evaluate new models before fully releasing them. Fallback mechanisms must also reflect business risk so that a model outage does not automatically result in every transaction being approved or declined.
The future of fraud detection will increasingly depend on adaptive decision systems that combine predictive models, deterministic controls, streaming intelligence, and risk-aware routing. These systems will need to allocate computational resources efficiently while continuously learning from newly confirmed outcomes and adjusting to changing transaction patterns without destabilizing decisions or introducing unnecessary customer friction.
Ultimately, successful real-time fraud detection requires engineers to design the model, data pipeline, serving infrastructure, and decision policy as one integrated system. When these components work together, organizations can make timely and informed transaction decisions while balancing fraud prevention, customer experience, infrastructure cost, and operational reliability.
Frequently Asked Questions
1. What is machine learning for fraud detection?
Machine learning for fraud detection uses models trained on historical transaction data and related behavioral signals to estimate the likelihood that an activity is fraudulent. These predictions help production systems identify suspicious patterns and support decisions such as approving a transaction, declining it, requesting additional verification, or sending it for manual review.
2. How does real-time fraud detection work?
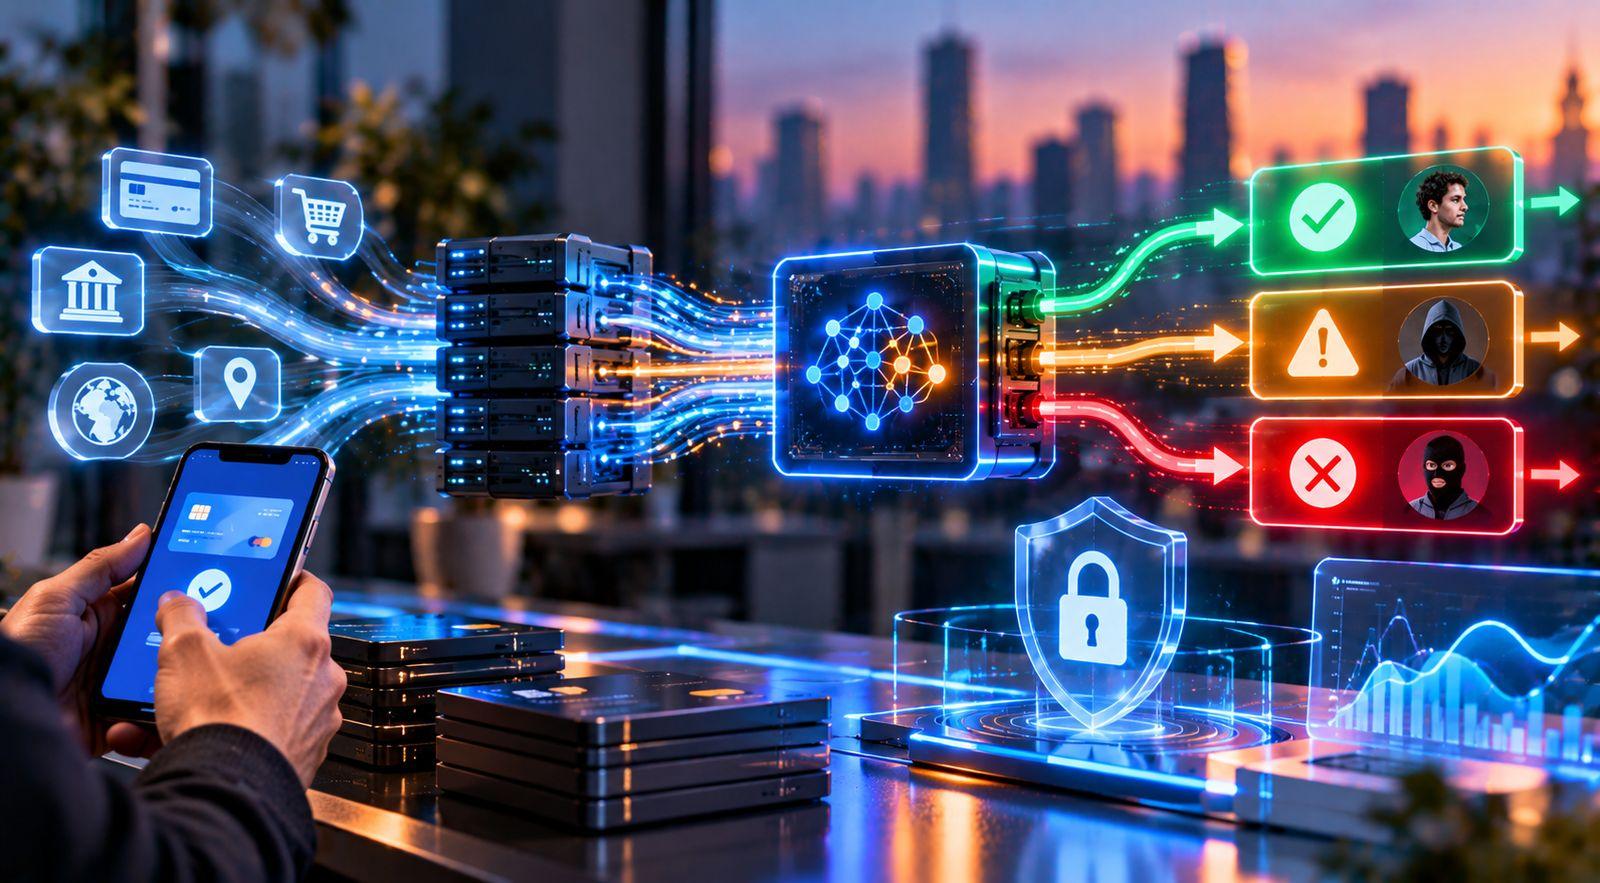
A real-time fraud detection system receives a transaction event, retrieves relevant features, runs an inference model, and passes the resulting risk score to a decision engine. The engine applies thresholds, business rules, and operational constraints to produce an outcome before the transaction workflow continues.
3. Why does fraud detection require millisecond-level inference?
Payment and transaction workflows often have strict response-time requirements because customers expect transactions to be processed without noticeable delay. The fraud detection system must therefore retrieve features, execute inference, evaluate risk, and return a decision within the available latency budget without creating bottlenecks in the broader payment infrastructure.
4. What data is commonly used in ML fraud detection?
Fraud detection models can use transaction amounts, timestamps, merchant categories, account history, device information, geographic context, transaction velocity, and behavioral patterns. The available signals depend on the application, and their usefulness depends on data quality, freshness, accessibility, and their relationship to the types of fraud the system is designed to detect.
5. What is a transaction risk score?
A transaction risk score is a numerical output representing the model's estimate of fraud risk or another related risk measure. The decision engine can use that score alongside business rules and operational requirements to determine whether a transaction should be approved, declined, or subjected to additional verification, with score interpretation depending on the model's design and calibration.
6. What is the difference between false positives and false negatives in fraud detection?
A false positive occurs when a legitimate transaction is incorrectly flagged as fraudulent, potentially causing unnecessary declines, customer friction, and lost revenue. A false negative occurs when a fraudulent transaction is incorrectly treated as legitimate, potentially allowing financial losses or additional fraud to occur, making both error types important when evaluating model quality.
7. Why is accuracy not enough to evaluate a fraud detection model?
Fraudulent transactions often represent a small proportion of total transaction volume, so a model can achieve high overall accuracy while failing to detect a meaningful amount of fraud. Engineers should also evaluate precision, recall, false-positive rates, false-negative rates, financial impact, and performance across relevant transaction categories to understand whether the system is useful in production.
8. What are velocity features in fraud detection?
Velocity features describe the frequency or cumulative magnitude of transactions over a defined time window, such as the number of payments attempted by an account or device within several minutes. These features help the model identify unusual activity patterns that may not be apparent when each transaction is evaluated independently.
9. Why are streaming pipelines important for real-time fraud detection?
Streaming pipelines process transaction events as they arrive and update features that describe recent activity. This makes timely behavioral signals available to the inference service without requiring every prediction request to scan historical transaction records or recalculate expensive aggregates.
10. What is an online feature store?
An online feature store is a data-serving layer designed to provide model features with low retrieval latency during inference. In fraud detection, it can supply information such as recent transaction aggregates, account attributes, device signals, and merchant statistics, helping the model access relevant features within strict response-time constraints.
11. Should fraud detection rely entirely on machine learning?
Not necessarily, because deterministic rules remain valuable for enforcing explicit controls and identifying known suspicious conditions, while ML models can detect more complex relationships in transaction data. Combining the approaches allows the system to preserve transparent business controls while using statistical models to estimate risk across a broader range of situations.
12. How are decision thresholds selected in fraud detection?
Decision thresholds should be selected using validation results, transaction risk, the cost of missed fraud, the impact of legitimate transactions being declined, and available investigation capacity. Engineers can establish different risk bands for automatic approval, rejection, or additional verification, allowing the intervention to reflect the estimated risk rather than applying one threshold indiscriminately.
13. How do engineers monitor fraud detection models in production?
Production monitoring can track inference latency, error rates, feature freshness, prediction distributions, approval and decline rates, additional-verification volume, and confirmed fraud outcomes. Because reliable labels may arrive later, engineers also need to monitor leading indicators and subsequently evaluate predictions against confirmed transaction outcomes as those labels become available.
14. What is model drift in fraud detection?
Model drift refers to changes that reduce the suitability or predictive effectiveness of a deployed model as transaction behavior, fraud techniques, or the surrounding environment evolves. Engineers can investigate these changes by monitoring input and prediction distributions, measuring performance against newly confirmed outcomes, and evaluating whether model recalibration, retraining, or changes to the decision policy are justified.
15. How can engineers make a fraud detection system reliable during model or infrastructure failures?
Engineers can improve reliability through explicit timeouts, resource controls, model versioning, controlled releases, monitoring, and predefined fallback policies for unavailable models or missing features. Depending on the transaction's risk and the business requirements, the system can use a compatible fallback model, enforce deterministic controls, request additional verification, or route the case for review rather than treating every inference failure as a reason to approve or decline the transaction automatically.