Section 1: Why Modern Search Systems Need Machine Learning
Keyword Matching Cannot Fully Capture Search Intent
Traditional search systems are highly effective when users express their information needs using the same terminology that appears in searchable content, because inverted indexes can efficiently locate documents containing matching terms. However, modern users rarely formulate every query with the exact vocabulary, structure, or terminology present in the documents they want to find, creating a gap between what a user writes and what the underlying content actually means. A query such as “best laptop for programming under $1,500” may need to identify products described with different language, while a technical search such as “why is my database getting slower after adding indexes” may require understanding relationships among concepts rather than matching isolated words.
Machine learning helps address this gap by learning representations and relationships from data instead of depending entirely on manually defined matching rules. Query understanding models can identify entities, intent, context, and important concepts, while semantic representations can place queries and documents into spaces where related meanings become closer even when their vocabulary differs. This allows retrieval systems to recognize relevance based on conceptual similarity rather than exact lexical overlap.
The shift toward semantic understanding does not make keyword search obsolete because exact terms remain important for identifiers, product names, technical terminology, legal language, and other cases where lexical precision is valuable. Instead, modern search systems increasingly combine traditional retrieval with learned representations, creating architectures that can preserve exact matching while expanding the system's ability to understand meaning.
Search Requires Massive Candidate Reduction Before Ranking
A production search engine may have millions, billions, or more searchable items, yet it cannot evaluate every document with an expensive machine-learning model for every query because the computational cost would make the system impractical. The first major engineering challenge is therefore candidate generation, where the system rapidly reduces an enormous corpus to a smaller collection of potentially relevant results that can be evaluated more carefully.
Traditional inverted indexes provide extremely efficient lexical retrieval by mapping terms to documents, allowing systems to identify candidates without scanning the complete corpus. Semantic retrieval introduces another mechanism in which queries and documents are represented as embeddings and compared according to vector similarity. Approximate nearest-neighbor techniques can make these searches computationally feasible at large scale, although they introduce trade-offs between recall, latency, memory consumption, and index complexity.
The candidate-generation stage becomes especially important because errors made here cannot always be corrected by later ranking models. If a highly relevant document never enters the candidate set, even the most sophisticated reranker cannot select it. Search engineers therefore need to optimize retrieval for high recall while keeping the candidate set small enough that downstream ranking remains computationally practical.
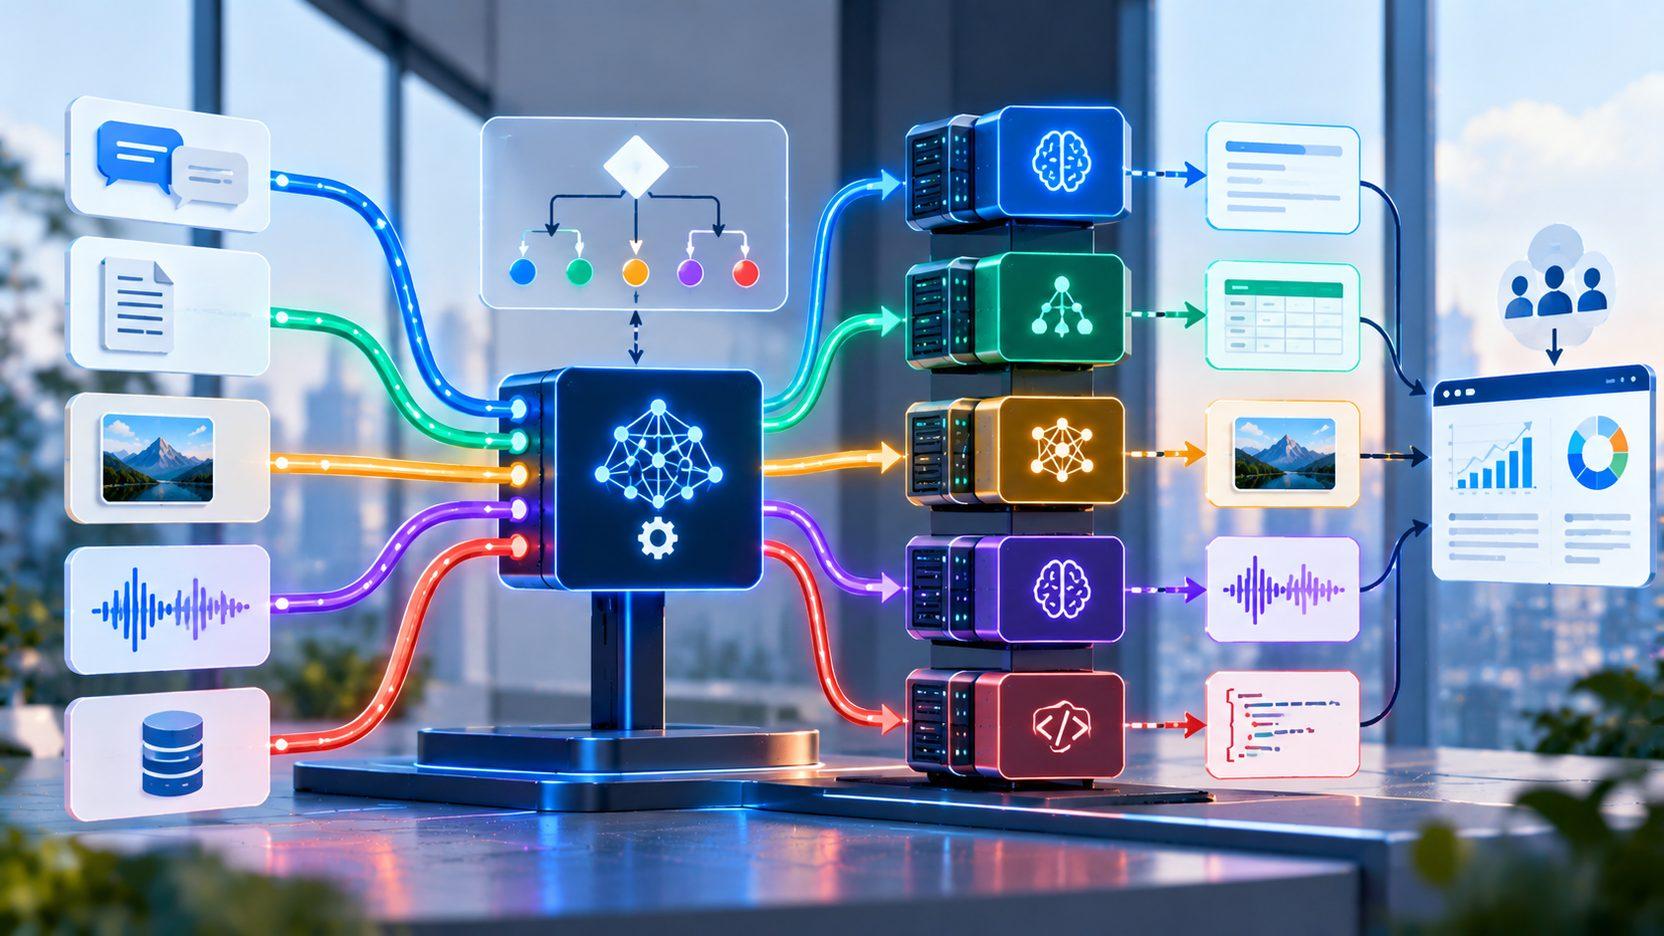
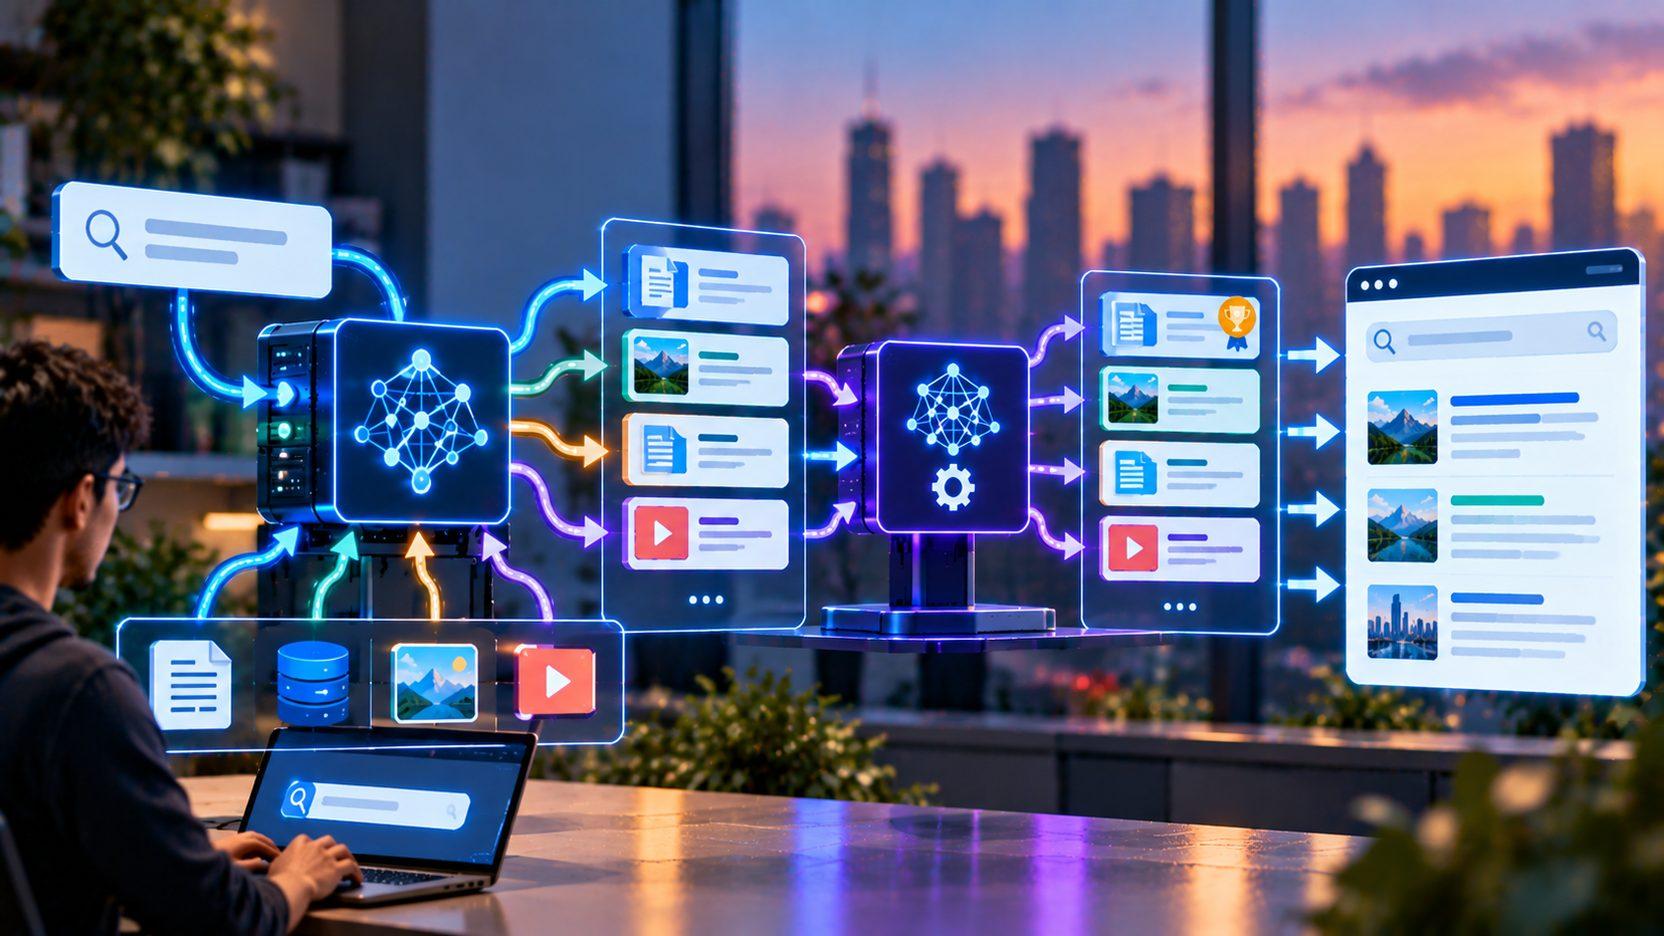
This creates an important division of labor within the search architecture, with fast retrieval mechanisms finding plausible candidates and more sophisticated ML models determining which candidates deserve the highest positions. The resulting pipeline allows expensive intelligence to be concentrated where it has the greatest impact rather than applying complex computation indiscriminately across the entire corpus.
Search Quality Depends on Continuous Learning and Evaluation
Unlike static information-retrieval systems, ML-powered search systems can change as models are retrained, indexes are refreshed, user behavior evolves, and new content enters the corpus. A ranking model that performs well today may become less effective when user expectations change, while a retrieval system may lose quality when the terminology or structure of searchable content evolves. Search therefore requires continuous evaluation rather than a one-time relevance assessment.
Engineers can evaluate retrieval quality through curated query sets, human judgments, behavioral signals, and task-specific metrics that measure whether relevant results are retrieved and ranked effectively. Metrics such as recall at a candidate stage and ranking-oriented measures at later stages provide different perspectives on system performance, allowing teams to determine whether a problem originates in retrieval, ranking, or the interaction between them.
User behavior provides another important source of evidence because clicks, reformulations, dwell time, conversions, and other interactions reveal how users respond to search results. However, these signals are not perfect labels because ranking itself influences what users see and therefore what they can interact with. A highly ranked result receives more exposure, which can make its interaction rate appear stronger even when its underlying relevance is not superior.
This creates feedback loops that search engineers must monitor carefully because optimization against historical behavior can reinforce existing ranking decisions. The principles discussed in “The Challenge of Feedback Loops in Production Machine Learning” are therefore directly relevant to intelligent search, where model predictions influence the very behavioral data used to improve future ranking models.
Key Takeaway
Modern search systems need machine learning because relevance depends on meaning, context, scale, and evolving user behavior rather than keyword overlap alone. The strongest architectures combine efficient lexical and semantic retrieval with learned ranking, contextual signals, and continuous evaluation, allowing engineers to reduce enormous search spaces quickly while still improving the relevance of the final results through increasingly intelligent models.
Section 2: How Intelligent Retrieval Pipelines Find Relevant Candidates
Query Understanding Converts User Language Into Searchable Intent
An intelligent retrieval pipeline begins before the system searches the corpus because the raw query often contains ambiguity, incomplete context, spelling variation, or multiple concepts that need to be interpreted before relevant candidates can be retrieved. Query understanding systems can identify entities, intent, language, constraints, and important terms, allowing the search engine to transform a natural-language request into representations that downstream retrieval components can process efficiently. A query such as “lightweight running shoes for winter under $150” contains several distinct signals involving product category, use case, season, budget, and potentially user preferences, making simple term matching insufficient for many search experiences.
Machine-learning models can enrich queries through classification, entity recognition, rewriting, expansion, and semantic representation. Query rewriting can transform informal language into clearer search expressions, while expansion can introduce related terminology that improves recall when users and documents use different vocabulary. Embedding models provide another representation by encoding semantic information into vectors that can support similarity-based retrieval even when the query and candidate document do not share the same exact words.
Query understanding should nevertheless remain connected to the downstream retrieval strategy because adding too much interpretation can introduce irrelevant candidates or distort precise user intent. Exact identifiers, product codes, names, technical terms, and quoted phrases may require lexical treatment even when the broader query also benefits from semantic understanding. Effective search systems therefore preserve important literal signals while enriching them with learned representations that provide additional context.
This combination reflects the evolution described in “From Search Engines to Answer Engines: The Evolution of Digital Experiences,” where understanding the intent behind a request becomes increasingly important as search experiences move beyond simple keyword matching. The query-processing layer effectively establishes the information that the retrieval system needs before candidate generation begins.
Lexical Retrieval Provides Fast and Precise Candidate Generation
Traditional lexical retrieval remains a foundational component of modern search because inverted indexes can efficiently identify documents containing particular terms without scanning the entire corpus. When a user searches for an exact product name, programming function, account identifier, or technical phrase, lexical matching can provide highly precise results with extremely low retrieval cost. These characteristics make keyword retrieval valuable even in systems that also use advanced semantic representations.
The retrieval engine can score lexical candidates using techniques such as term frequency, inverse document frequency, field weighting, and other relevance signals that distinguish important matches from incidental occurrences. Fields can also receive different weights because a match in a document title may carry more relevance than the same term appearing deep within an unrelated section. These mechanisms provide efficient first-stage retrieval while allowing engineers to encode domain-specific assumptions about which textual matches are meaningful.
Lexical retrieval can also provide important safeguards when semantic similarity produces candidates that are conceptually related but not sufficiently precise. Search systems dealing with legal documents, software documentation, medical terminology, or product catalogs may need exact terminology to remain highly influential in candidate generation. A hybrid architecture can therefore use lexical retrieval to preserve precision while allowing semantic retrieval to discover relevant content that keyword matching might miss.
The key engineering challenge is choosing how many candidates to retrieve because a larger candidate set can improve recall but increases the work required by downstream ranking models. Retrieval systems therefore need to balance candidate coverage against latency, memory use, and the computational capacity available for subsequent reranking. Candidate generation becomes a controlled funnel in which the search engine intentionally trades a small amount of recall or additional retrieval cost against the practical limits of the ranking stage.
Vector Retrieval Adds Semantic Understanding at Scale
Vector retrieval allows search systems to represent queries and documents as embeddings and identify candidates according to semantic similarity rather than exact lexical overlap. This can be useful when users express an intent using language that differs substantially from the wording in the underlying content, allowing conceptually related documents to be retrieved even when traditional term matching produces weak results. Semantic retrieval is particularly valuable for natural-language questions, conversational search, product discovery, and content collections where vocabulary varies significantly across documents.
The primary engineering challenge is scaling similarity search because a corpus containing millions or billions of embeddings cannot be exhaustively compared with every incoming query. Approximate nearest-neighbor methods reduce computational cost by organizing vectors into structures that allow the system to search a smaller portion of the space while maintaining high retrieval quality. Engineers must choose index configurations that balance recall, query latency, memory consumption, update complexity, and operational cost.
Vector retrieval also introduces model-dependent behavior because the quality of the search results depends heavily on the embedding model and the way documents and queries are represented. An embedding model trained for general semantic similarity may perform poorly for highly specialized domains, while a domain-specific model may improve relevance but require additional training and operational maintenance. Search teams therefore need evaluation datasets that reflect real query patterns when selecting or updating embedding models.
Semantic retrieval is most powerful when it complements rather than completely replaces lexical retrieval. A query can be processed through both systems, producing candidates from exact term matches and semantic similarity, after which the results can be merged, filtered, deduplicated, and passed to a downstream ranking model. This hybrid design provides broader retrieval coverage while preserving exact-match behavior where it remains valuable.
Key Takeaway
Intelligent retrieval pipelines combine query understanding, lexical search, vector retrieval, and hybrid candidate generation to transform enormous search spaces into manageable sets of plausible results. The most effective systems preserve the precision of exact matching while using semantic representations to discover conceptually relevant content, carefully balancing recall, latency, memory, and computational cost so that downstream ranking models receive a strong candidate set without making the search experience unnecessarily expensive.
Section 3: Ranking, Personalization, and Learning From Search Behavior
Learning-to-Rank Determines Which Candidates Should Appear First
Retrieval produces a set of potentially relevant candidates, but a useful search system still needs to determine which results deserve the highest positions because users rarely inspect an entire candidate set. Learning-to-rank models address this problem by estimating the relative relevance of retrieved items using signals derived from the query, document, user context, and historical interaction data. Instead of relying entirely on manually constructed scoring formulas, these models can learn relationships among multiple signals and optimize ranking behavior from examples of desirable search outcomes.
Ranking models can operate at different stages of the search pipeline depending on their computational complexity. Lightweight models can score large candidate sets quickly during an initial ranking stage, while more sophisticated neural models can rerank a smaller set of candidates after retrieval has already reduced the search space. Cross-encoder architectures, for example, can jointly process a query and candidate document to estimate detailed relevance, but their computational cost makes them more practical when applied to a limited number of candidates rather than an entire corpus.
The features used for ranking can include lexical relevance, semantic similarity, document quality, freshness, popularity, query-document interaction signals, and domain-specific attributes. A search engine may also incorporate structured constraints such as availability, price, geographic distance, permissions, or content type before or during ranking. The resulting model therefore operates within a broader decision system where predictive relevance must coexist with business and application constraints.
The goal is not necessarily to identify a universally correct order because search relevance depends on the task the user is trying to accomplish. An informational query may prioritize authoritative and comprehensive content, while a product query may emphasize availability, suitability, and price. Engineers therefore need evaluation criteria that reflect the intended search experience rather than assuming that one ranking objective is appropriate for every workload.
Reranking Adds Precision After Candidate Retrieval
A two-stage or multi-stage architecture allows search systems to use different levels of computational complexity at different points in the pipeline. The retrieval stage focuses on recall by quickly finding a broad set of potentially relevant candidates, while a reranking stage can apply more computationally expensive models to a smaller group. This structure lets engineers use sophisticated language or interaction models without requiring them to evaluate every item in the complete search corpus.
Reranking models can examine relationships that simpler retrieval scores cannot capture effectively. A query and document may share many terms while expressing incompatible meanings, or they may use different vocabulary while describing the same concept. A more expressive ranking model can analyze the relationship between the query and candidate content at a finer level, improving ordering after the initial retrieval stage has already established a manageable candidate set.
The size of the reranking set creates an important engineering trade-off because larger sets can improve the chance that the best result is considered, but they also increase inference cost and latency. Search engineers therefore need to determine how many candidates can be processed within the available response-time budget while preserving sufficient recall. This is one reason retrieval and ranking cannot be optimized independently because improvements in candidate generation directly influence the computational requirements and quality ceiling of later stages.
Reranking can also be combined with deterministic business constraints because not every ranking decision should be left entirely to a statistical model. Permissions, inventory availability, safety requirements, geographic restrictions, or contractual rules may need to be enforced regardless of model scores. The serving architecture therefore needs a clear boundary between learned relevance estimation and non-negotiable application constraints.
Search Behavior Creates a Powerful but Imperfect Feedback Signal
User interactions provide valuable evidence about search quality because actions such as clicks, reformulations, purchases, saves, dwell time, and other downstream behaviors can indicate whether retrieved results were useful. These signals can be incorporated into training datasets for ranking models, allowing future versions to learn from observed production behavior rather than relying entirely on manually labeled examples.
Behavioral signals are not equivalent to direct relevance judgments, however, because the search system itself influences what users can observe and interact with. A result placed at the top of the page receives more exposure than a result placed lower, which can increase its click probability even when its intrinsic relevance is not better. This creates a position bias in which observed interaction rates reflect both user preference and previous ranking decisions.
Search teams can address these limitations through carefully designed experimentation, randomized exposure where appropriate, human relevance judgments, debiasing techniques, and metrics that account for presentation effects. The objective is to avoid building a feedback loop in which successful historical rankings continuously reinforce themselves simply because they receive more exposure. This challenge connects directly with “Learning to Rank: The Machine Learning Behind Search and Recommendations,” where ranking models depend on learning meaningful relationships between queries, candidates, and user outcomes rather than blindly optimizing raw interaction counts.
The broader issue is that search behavior changes as the product, content corpus, and user population evolve. A ranking model trained on yesterday's interaction patterns may become less effective when new products appear, terminology changes, or user expectations shift. Continuous experimentation, monitoring, retraining, and relevance evaluation are therefore essential for maintaining search quality as the surrounding environment changes.
Key Takeaway
Ranking transforms retrieved candidates into an ordered search experience by combining relevance models, reranking, personalization, business constraints, and behavioral signals. The strongest systems use lightweight models for broad ranking and more sophisticated models for focused reranking, while carefully controlling personalization and feedback loops so that user behavior improves future search quality without allowing historical exposure patterns to distort what the system considers relevant.
Section 4: Building Search Systems That Work Reliably at Production Scale
Search Latency Requires Optimization Across the Entire Retrieval Pipeline
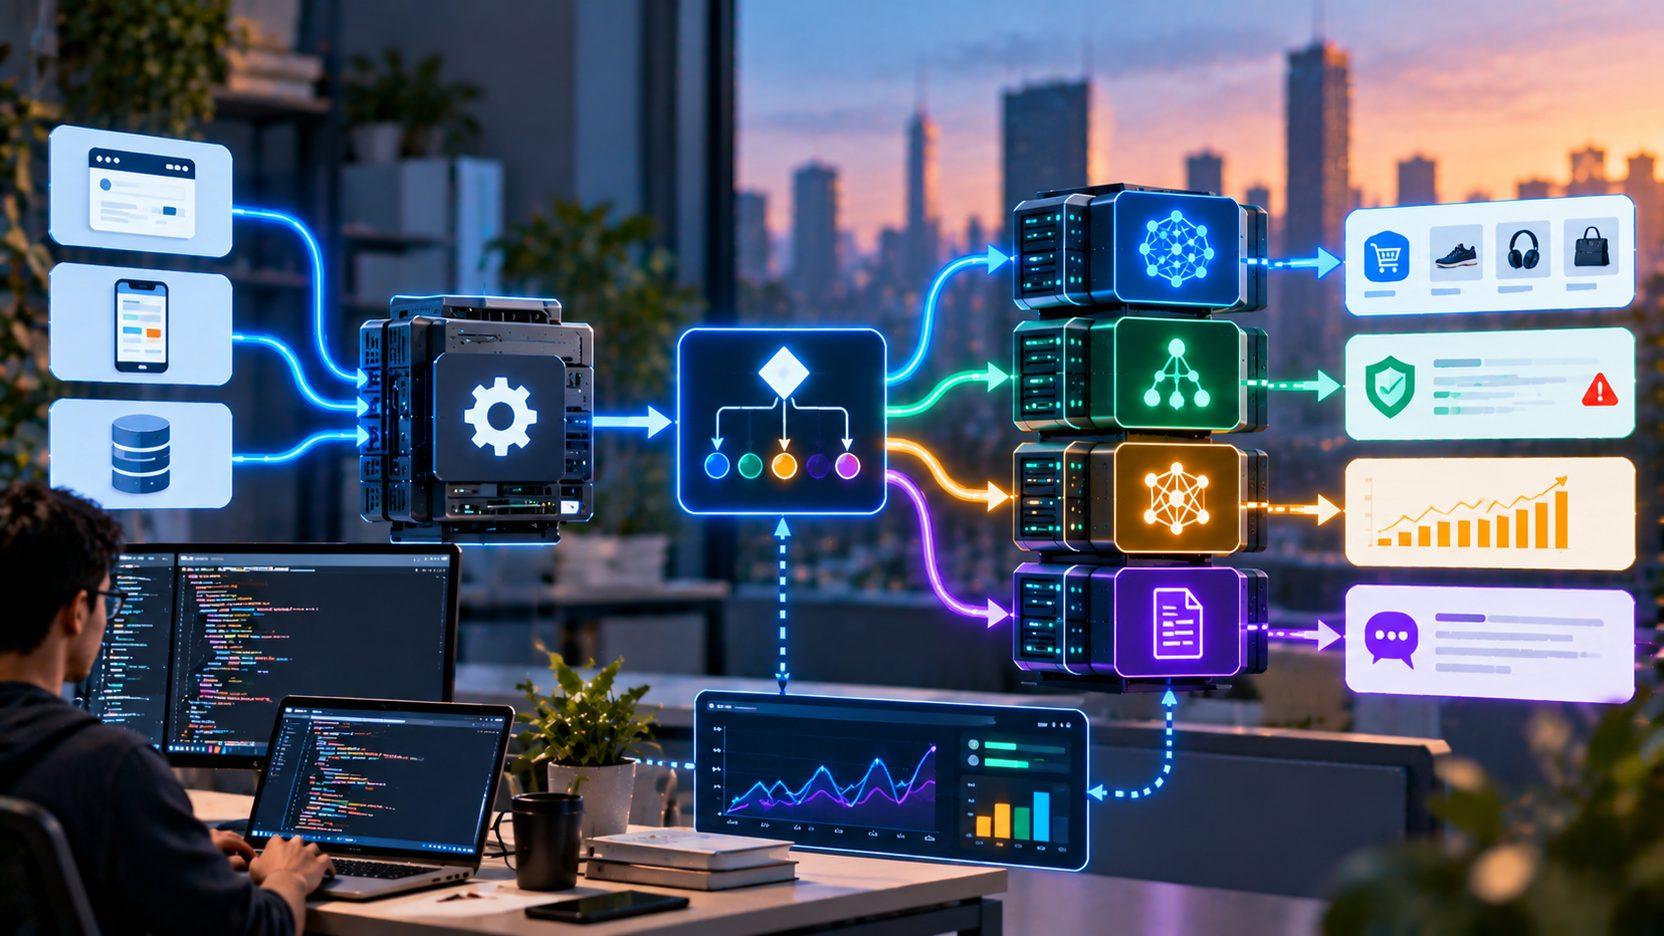
A search system can deliver excellent relevance and still provide a poor user experience when retrieval and ranking take too long, making latency a first-class design constraint alongside search quality. A production query can pass through query understanding, lexical retrieval, vector retrieval, candidate merging, filtering, ranking, reranking, personalization, and result generation before the response reaches the user, meaning that optimizing a single model does not necessarily improve end-to-end performance.
Engineers therefore need to measure latency at each stage and identify which components dominate the critical path under realistic workloads. Query-processing overhead, index access, vector search, feature retrieval, model inference, network communication, and serialization can each contribute to response time, while traffic bursts and resource contention can increase tail latency even when average performance appears acceptable. Search systems commonly need to monitor percentile-based latency because a small proportion of extremely slow requests can still affect perceived reliability at scale.
Caching can reduce repeated work when users frequently issue similar queries or when expensive retrieval and ranking results remain valid for an appropriate period. However, caching must account for personalization, freshness, permissions, and rapidly changing content because an aggressively reused result can become incorrect even while improving performance. The architecture should therefore distinguish between data that can safely be cached and signals that need to be evaluated dynamically.
These principles connect with “ML for Real-Time Systems: Engineering Models Under Strict Latency Constraints,” because search relevance does not matter if the system cannot deliver results within the application's latency budget. Intelligent retrieval pipelines must therefore treat model execution, data access, indexing, and distributed-system behavior as one integrated performance problem.
Indexing Pipelines Determine What the Search System Can Retrieve
A search engine is only as capable as the index and representations available to its retrieval stages, making indexing an important part of ML-powered search architecture. New documents, products, records, or content must be transformed into searchable representations, which may include tokenized text, structured fields, metadata, embeddings, and ranking features. These representations then need to be updated as the underlying corpus changes.
Traditional indexes can often support incremental updates efficiently, while vector indexes introduce additional considerations around embedding generation, index construction, storage, and update strategies. When a new document enters the system, the embedding pipeline may need to generate a representation before semantic retrieval can discover it, creating a dependency between content ingestion and search availability. Delayed indexing can therefore create a mismatch between what exists in the source system and what users can actually retrieve.
Freshness requirements vary significantly across search applications because a documentation platform may tolerate some indexing delay while news, inventory, or marketplace systems may require much faster updates. Engineers need to balance indexing frequency against computational cost, storage overhead, consistency requirements, and retrieval performance. Maintaining continuously updated vector indexes at very large scale can become expensive, making architectural decisions around batch updates, streaming ingestion, and partial index refreshes important.
Index quality also influences ranking quality because missing, stale, duplicated, or poorly represented content can reduce search effectiveness even when the ranking model performs correctly. Search engineers therefore need observability into document ingestion, embedding generation, index freshness, failed updates, and content coverage rather than treating indexing as a background process disconnected from relevance.
Search Quality Requires Continuous Evaluation and Experimentation
Search quality cannot be established through model accuracy alone because relevance is inherently dependent on the user's information need and the way results are presented. Engineers can use curated evaluation datasets containing representative queries and relevance judgments to measure retrieval recall and ranking quality, while behavioral signals can provide additional evidence about how the system performs in real usage. Combining offline and online evaluation allows teams to determine whether an apparent improvement in model metrics also produces a better search experience.
Offline evaluation is valuable because it provides controlled comparisons between retrieval algorithms, embedding models, ranking strategies, and query-understanding components. Engineers can test candidate systems against the same evaluation set, measure changes in retrieval and ranking metrics, and identify regressions before exposing users to a new configuration. However, offline datasets can become stale and may not fully represent changing user behavior, making continuous refresh and diverse query coverage necessary.
Online experimentation can determine whether users actually benefit from a change by comparing different search configurations through controlled traffic allocation. Metrics can include query reformulation rates, successful result interactions, downstream conversions, task completion, engagement, and latency, depending on the purpose of the search product. Experiments need careful interpretation because changes in ranking can alter exposure patterns, which means an observed increase in clicks does not automatically imply an increase in true relevance.
Search teams also need to monitor quality across important query categories rather than relying solely on aggregate results. Navigational queries, informational queries, rare queries, long-tail queries, and newly emerging terminology can behave differently, and a ranking improvement for common searches can coexist with severe degradation for less frequent but important cases. Segment-level evaluation therefore helps ensure that optimization does not improve averages while weakening the search experience for critical populations.
Key Takeaway
Production-scale ML search requires coordinated engineering across latency optimization, indexing, retrieval, ranking, experimentation, and continuous monitoring rather than isolated model improvements. By maintaining fresh searchable representations, controlling end-to-end response time, evaluating relevance through both offline and online evidence, and combining lexical, semantic, and increasingly adaptive retrieval strategies, engineers can build search systems that remain fast, relevant, scalable, and resilient as content, user behavior, and search expectations evolve.
Conclusion
Machine learning has transformed search from a system primarily focused on matching words into a multi-stage intelligence pipeline capable of understanding intent, retrieving semantically related information, ranking candidates, and adapting results to user context. The fundamental engineering challenge, however, remains unchanged: the system must find useful information quickly and reliably at production scale. What has changed is the sophistication required to achieve that objective.
Modern search systems typically combine several retrieval and ranking mechanisms because no single approach performs optimally across every query. Lexical retrieval remains valuable when exact terminology matters, while vector retrieval provides semantic recall when users and content express similar concepts differently. Hybrid retrieval can combine these complementary strengths, creating a broader candidate set for downstream ranking while preserving the precision required for identifiers, technical terminology, and other exact-match scenarios.
Candidate retrieval is only the beginning because a search system must still determine which results should appear first. Learning-to-rank models, rerankers, personalization signals, freshness, content quality, and business constraints can all influence final ordering. These signals must be balanced carefully because optimizing one dimension in isolation can create unintended consequences, such as higher engagement with lower-quality results or improved average relevance accompanied by poorer performance for important query segments.
Production engineering becomes equally important once these models operate at scale. Search latency depends on the entire retrieval pipeline, including query processing, index access, vector search, filtering, feature retrieval, ranking, and network communication. Index freshness, embedding generation, caching, resource utilization, and tail latency can affect the user experience just as strongly as the ranking model itself. Engineers therefore need to optimize search as an integrated distributed system rather than treating retrieval and ranking as isolated ML components.
Evaluation must also continue after deployment because search behavior changes as new content appears, user expectations evolve, models are retrained, and ranking decisions influence the very interaction data used for future training. Offline relevance datasets provide controlled measurements, while online experiments and behavioral signals reveal how users respond to real search experiences. Combining these forms of evidence helps teams distinguish genuine relevance improvements from changes that merely exploit historical exposure patterns.
The future of intelligent search will increasingly involve adaptive combinations of lexical retrieval, semantic retrieval, specialized ranking models, multimodal representations, and increasingly capable language models. The strongest systems will not necessarily depend on the most sophisticated model for every query; instead, they will allocate computation according to query complexity, expected value, latency constraints, and available infrastructure.
Ultimately, building an intelligent retrieval pipeline is a multidisciplinary engineering problem that combines information retrieval, machine learning, data engineering, distributed systems, experimentation, and production operations. Engineers who understand how these layers interact can build search systems that do more than retrieve documents, allowing users to find relevant information quickly, accurately, and consistently even as the underlying content and user behavior continue to evolve.
Frequently Asked Questions
1. What is machine learning for search systems?
Machine learning for search systems uses trained models to improve how search engines understand queries, retrieve candidates, rank results, personalize responses, and learn from user interactions. ML can complement traditional information-retrieval techniques rather than replacing them entirely.
2. Why is keyword search not enough for modern search?
Keyword matching can miss relevant content when users and documents use different terminology or when the query requires understanding concepts rather than exact words. Semantic models can represent meaning and identify related content even when lexical overlap is limited.
3. What is semantic search?
Semantic search retrieves results based on meaning and conceptual similarity rather than relying solely on matching exact terms. Query and document embeddings can be compared in a vector space so that content with related meanings can be retrieved even when the wording differs.
4. What is vector search?
Vector search retrieves items according to the similarity between numerical representations called embeddings. It is commonly used for semantic retrieval because queries and documents can be represented as vectors and compared using similarity measures rather than exact textual matches.
5. What is hybrid search?
Hybrid search combines multiple retrieval approaches, most commonly lexical retrieval and semantic vector retrieval. The resulting candidate sets can be merged and reranked so that the system benefits from exact matching while also recovering conceptually relevant content that keyword search might miss.
6. Why is candidate generation important?
Candidate generation reduces a potentially enormous corpus to a manageable set of plausible results that can be processed by more sophisticated ranking models. If a relevant document never enters the candidate set, a downstream reranker cannot recover it, making retrieval recall a critical property of the overall search architecture.
7. What is learning-to-rank?
Learning-to-rank uses machine-learning models to determine the relative ordering of search results. Models can combine query-document relationships, semantic similarity, freshness, popularity, user context, and other signals to estimate which candidates should appear higher in the result set.
8. What is reranking in a search pipeline?
Reranking is a later-stage ranking process that applies a more sophisticated or computationally expensive model to a smaller set of retrieved candidates. This allows systems to use detailed relevance models without applying their full computational cost to an entire search corpus.
9. How does personalization improve search?
Personalization incorporates information about the user's preferences, history, context, location, or recent behavior to adjust result ordering. It can make results more useful for individual users, although excessive personalization can reduce discovery or reinforce previously observed preferences.
10. How does user behavior help train search models?
Interactions such as clicks, query reformulations, purchases, saves, and other downstream actions can provide signals about how users respond to search results. These signals can become training data, although engineers need to account for position bias and other factors because ranking decisions influence which results users are able to interact with.
11. What is approximate nearest-neighbor search?
Approximate nearest-neighbor search is a technique for finding vectors that are highly similar to a query without comparing the query against every vector in the corpus. It reduces computational cost and makes large-scale semantic retrieval practical while introducing trade-offs among recall, latency, memory, and index complexity.
12. How do engineers evaluate search quality?
Search quality can be evaluated through curated query datasets, human relevance judgments, retrieval and ranking metrics, online experiments, and behavioral signals. A strong evaluation strategy combines offline measurements with real production evidence because no single metric captures every aspect of search usefulness.
13. Why does search latency matter so much?
Search users typically expect results quickly, making latency an important part of the overall search experience. Query processing, retrieval, vector search, filtering, feature retrieval, ranking, and network communication can all contribute to response time, so engineers need to optimize the complete pipeline rather than only the model.
14. How do feedback loops affect ML-powered search?
Ranking decisions influence which results users see and interact with, which in turn affects the behavioral data used to train future models. This can create feedback loops in which existing ranking patterns are reinforced because highly exposed results naturally generate more interaction data, making careful experimentation and debiasing important.
15. What does a production-ready ML search system require?
A production-ready ML search system requires strong query understanding, high-recall candidate retrieval, effective ranking and reranking, appropriate personalization, fresh indexing, predictable latency, scalable serving infrastructure, continuous relevance evaluation, and monitoring for changing data and user behavior. The strongest systems combine these capabilities through a layered architecture that balances search quality, performance, freshness, scalability, and operational cost.