Section 1: Why Bigger Models Are Not Always Better for Production Machine Learning
The rapid growth of machine learning has created a strong association between model scale and capability, particularly as increasingly large neural networks have delivered major improvements across language, vision, recommendation, and generative AI applications. Larger models can represent more complex relationships and often benefit from additional parameters and training data, but production environments introduce constraints that are not visible in benchmark comparisons, including inference cost, latency, memory requirements, energy consumption, deployment hardware, and operational complexity. These constraints are driving renewed interest in smaller models that can deliver the capabilities required by a specific application without carrying unnecessary computational overhead.
Model Size Does Not Determine Business Value
A model can become more capable as it grows while simultaneously becoming less attractive for a particular production workload because the additional capability may require substantially more infrastructure than the application can justify. A recommendation service processing millions of requests, for example, may receive only a marginal improvement from a much larger model while paying substantially more for compute and memory, which can make the larger architecture less attractive when total operating cost is considered.
This distinction becomes especially important when model outputs are relatively narrow in scope. A machine-learning system designed to classify equipment states, identify fraudulent transactions, forecast demand, or detect image defects may not require the broad representational capacity of a general-purpose foundation model because the downstream task can often be expressed through a focused prediction objective and a constrained input space. In such situations, a compact model can provide sufficient predictive capability while reducing latency, infrastructure requirements, and deployment complexity.
This perspective aligns with “Model Complexity vs Business Value: Finding the Right Level of ML,” because model selection should ultimately reflect the value created by additional complexity rather than assuming that a larger architecture is automatically the better engineering choice.
Large Models Can Create Production Constraints
A large model introduces several forms of operational overhead beyond the storage required for its parameters, because inference can consume substantial memory bandwidth, accelerator capacity, and energy while also increasing deployment requirements and limiting the number of requests that a system can process within a fixed infrastructure budget. These constraints become particularly important when an application requires low latency, high throughput, or continuous inference across a large user population.
Latency can become a decisive limitation for interactive applications because users experience the complete response time rather than the model's benchmark quality, while high memory requirements can restrict the number of model instances that can run concurrently and increase infrastructure costs. Edge applications face even tighter limitations because mobile devices, industrial controllers, cameras, and embedded systems may have restricted compute, storage, connectivity, and battery capacity, making a model that performs well in a centralized data center impractical for local deployment.
Large models can also increase operational complexity because every deployment may require specialized hardware, optimized runtimes, careful scaling strategies, and additional monitoring, which means that the engineering cost of maintaining the system can grow alongside the model's computational requirements.
Compact Models Can Be Better Matched to Specific Tasks
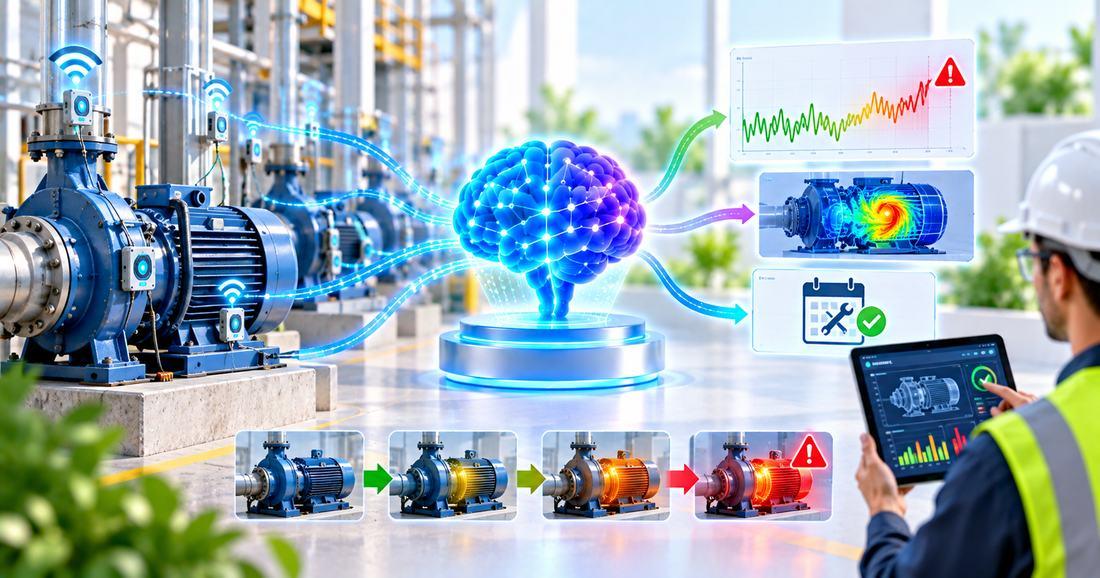
Small models become particularly attractive when the task is narrow, repetitive, and well understood because the model does not need to represent every possible capability when only a specific subset is required by the application. A fraud classifier can focus on transaction characteristics and behavioral signals, while an industrial anomaly detector can concentrate on sensor patterns associated with equipment states, allowing the architecture to optimize for the actual prediction problem rather than for general-purpose intelligence.
Task specialization can also reduce the amount of input that needs to be processed, simplify the model architecture, and make optimization techniques such as quantization, pruning, or distillation more effective because engineers know which capabilities need to be preserved and which capabilities are unnecessary for the deployment target.
This creates a practical distinction between general capability and task-specific efficiency, where a compact model can outperform a larger alternative on the dimensions that matter operationally even when the larger model remains more capable in absolute terms.
Small Models Enable More Flexible AI Architectures
The return of compact models does not imply that organizations need to choose exclusively between small and large architectures, because modern AI systems can combine models of different sizes according to the complexity and risk of individual requests. A lightweight model can handle routine cases, while a larger model can be invoked when the input is ambiguous, unusually difficult, or likely to benefit from deeper reasoning, which allows computational resources to be allocated according to actual task requirements.
This type of architecture can reduce average inference cost while preserving access to more capable models when necessary, particularly when routing decisions are based on confidence, task difficulty, input characteristics, or business importance. Compact models can also operate closer to the source of the data, which can reduce network dependency and support privacy-sensitive applications where local processing is preferable to continuously transmitting raw information to centralized infrastructure.
The broader shift is therefore not simply toward smaller models, but toward more deliberate model sizing, in which engineers select the amount of computational capability that is appropriate for each part of the system and combine models strategically when different levels of intelligence are required.
Key Takeaway
Bigger models can provide greater general capability, but production value depends on whether that additional capability justifies the associated compute, memory, latency, energy, and infrastructure requirements. Compact models are becoming increasingly attractive for focused applications because they can deliver sufficient task-specific intelligence with lower operational overhead, while model-routing architectures allow organizations to combine small and large models so that computational resources are matched to the difficulty and requirements of individual requests.
Section 2: How Engineers Make Small Models Surprisingly Capable
The recent interest in compact machine learning models is not simply a result of reducing the number of parameters in an existing architecture, because modern model-efficiency techniques can preserve much of the useful capability of a larger model while substantially reducing memory, compute, and inference requirements. Engineers can achieve this through knowledge distillation, pruning, quantization, architecture optimization, and task-specific training, with each approach targeting a different source of unnecessary computational overhead.
Knowledge Distillation Transfers Capability From Larger Models
Knowledge distillation allows a smaller student model to learn from the behavior of a larger teacher model, rather than relying only on the original training labels. The teacher can provide richer information through probability distributions, intermediate representations, generated examples, or other signals that reveal relationships a compact model might not learn as effectively from hard labels alone.
The student is trained to reproduce useful aspects of the teacher's behavior while maintaining a substantially smaller computational footprint, which can make it possible to deploy a model with much lower latency and memory requirements without completely sacrificing the capabilities learned by the larger architecture. Distillation can be especially effective when the deployment task is narrower than the capabilities of the teacher because the student can focus on the subset of behavior that matters for the application instead of attempting to reproduce the entire teacher system.
The quality of the distilled model depends heavily on the quality and diversity of the examples used during training, because a student exposed only to easy or repetitive cases may learn an incomplete approximation of the teacher. Engineers can therefore use representative production-like data, difficult examples, and targeted edge cases to ensure that the compact model captures the behavior that matters under realistic operating conditions.
Pruning, Quantization, and Architecture Optimization Reduce Unnecessary Computation
Pruning reduces model complexity by removing parameters, connections, channels, or other components that contribute relatively little to the final prediction, which can reduce storage and computation when the resulting sparse or smaller structure is supported efficiently by the deployment hardware. The key challenge is distinguishing genuinely redundant components from information that appears unimportant on average but becomes critical for particular inputs or rare classes, because aggressive pruning can improve efficiency while damaging robustness or minority-case performance.
Quantization reduces the numerical precision used to represent model parameters and, in some cases, activations, which can lower memory consumption and improve inference efficiency on hardware that supports the selected numerical formats. Lower-precision computation can be especially valuable for edge devices and high-volume inference systems, although the appropriate level of quantization depends on the model architecture, sensitivity of individual layers, and capabilities of the target hardware.
Architecture optimization approaches the problem from an earlier stage by designing models whose computational structure is efficient from the beginning, rather than taking a large model and attempting to compress it afterward. Depth, width, attention patterns, convolutional structure, parameter sharing, and input-processing strategies can all be adjusted to reduce unnecessary computation while retaining the representations required for the target task.
These techniques can be used individually, but their combination can create significantly more efficient models when the resulting quality and deployment behavior are validated carefully.
Task-Specific Training Makes Compact Models More Competitive
A major advantage of a compact model is that it does not need to solve every possible problem that a general-purpose model can address, because its architecture and training process can be optimized around a clearly defined downstream task. A model designed specifically for fraud detection, equipment monitoring, recommendation ranking, or document classification can devote its limited capacity to patterns that are directly relevant to that application.
Task-specific training can therefore compensate for the reduced capacity of a compact model by focusing learning on the information that matters most, while feature selection, targeted data sampling, and carefully designed objectives can further prevent the model from spending capacity on irrelevant variation.
This is particularly useful when the production environment is well understood because engineers can identify the input characteristics, error modes, latency requirements, and resource limits that define success, allowing the training process to optimize for the actual deployment problem rather than for broad benchmark capability.
The result is a more deliberate form of model design in which compactness is not treated as a limitation that must simply be tolerated, but as a constraint that encourages the model to learn the most valuable representations efficiently.
Model Cascades and Selective Inference Extend Compact-Model Advantages
Small models become even more powerful when they are used as part of a model cascade, where an efficient model handles straightforward cases and a larger model is invoked only when additional capability is justified. This architecture allows the system to allocate computation according to input difficulty, confidence, or business importance instead of paying the maximum inference cost for every request.
For example, a lightweight classifier can resolve routine cases while ambiguous inputs are forwarded to a more capable model, allowing the average resource requirement to remain low even when the application still needs access to advanced capabilities for difficult cases. The routing decision itself can be designed around confidence thresholds, estimated difficulty, expected value, or other signals that determine whether additional computation is likely to improve the final result.
This approach connects directly with “Model Cascades: How AI Systems Combine Multiple Models to Reduce Cost,” because compact models can serve as the efficient first layer in a broader architecture that combines several levels of computational capability while controlling average latency and inference cost.
Selective inference can also operate within a single model when only parts of the architecture need to be activated for particular inputs, which creates another path toward efficient AI by ensuring that computational resources are proportional to the complexity of the problem being solved.
Key Takeaway
Compact models can retain substantial capability through knowledge distillation, pruning, quantization, efficient architectures, and task-specific training, while cascaded and selective-inference architectures allow small models to handle routine workloads and reserve larger models for cases that genuinely require additional computation. The central engineering goal is not simply to reduce parameter count, but to remove unnecessary computation while preserving the representations, robustness, and task-specific capabilities required in the target deployment environment.
Section 3: Designing Compact ML Models for Real-World Deployment
Building a compact model is only useful when the resulting system can operate reliably within its actual deployment environment, because production constraints often involve more than parameter count and model size. Latency targets, memory limits, hardware capabilities, workload variability, data movement, energy consumption, and model quality can interact in ways that are difficult to predict from offline experiments alone, making deployment-aware design essential for extracting the practical benefits of smaller models.
Design Around the Actual Deployment Environment
The most important decision in compact-model engineering is to identify the environment in which inference will occur and optimize the model around its specific constraints, because a model that is efficient on a high-end accelerator may behave very differently on a CPU, mobile processor, embedded device, or industrial controller. Engineers should therefore evaluate memory footprint, inference latency, throughput, initialization time, and hardware utilization on representative deployment infrastructure rather than relying exclusively on theoretical complexity or parameter counts.
Edge environments make this requirement particularly important because devices may have limited memory, processing capacity, storage, connectivity, and battery power, which means that even a relatively modest computational inefficiency can affect system availability or responsiveness. Local inference can provide advantages by reducing network communication and allowing sensitive data to remain closer to its source, but the model must still fit comfortably within the device's resource budget and provide predictable behavior under realistic workloads.
Cloud deployments have different constraints because the primary challenge may be serving large volumes of requests at acceptable cost, which makes throughput, concurrency, accelerator utilization, and average inference cost especially important. A compact model can create value in this environment by allowing more instances to run on the same infrastructure or by reducing the amount of compute required per request, although the actual savings depend on the serving stack and hardware characteristics.
Balance Latency, Accuracy, and Resource Consumption
Compact-model deployment requires explicit trade-offs because reducing model size can affect predictive performance, while optimizing aggressively for latency can alter the representations available to the model. Engineers should therefore define a minimum acceptable quality level and then search for the least resource-intensive model that satisfies that requirement, rather than optimizing model compression independently from downstream performance.
The evaluation should include production-relevant conditions because a compact model may appear strong on an average validation metric while degrading disproportionately on rare cases, difficult inputs, or specific user segments, which can create operational problems that are hidden by aggregate accuracy. This is particularly important when the model is responsible for safety-sensitive classification, fraud detection, anomaly detection, or other applications where a small subset of errors can carry disproportionate consequences.
Resource measurements should also be considered alongside predictive metrics because a model with marginally better accuracy may require substantially more memory or latency, while a slightly less accurate model could support significantly greater throughput and lower cost. The appropriate choice therefore depends on the business and operational value associated with the additional predictive capability, reinforcing the principles discussed in “Model Complexity vs Business Value: Finding the Right Level of ML,” where model selection is treated as a trade-off between capability and practical value rather than a simple race for maximum performance.
Build Efficient Serving and Graceful Degradation
Even a compact model can become inefficient when surrounded by poorly designed infrastructure, because preprocessing, serialization, network transfer, memory allocation, postprocessing, and orchestration can contribute significantly to end-to-end latency. Engineers should therefore optimize the complete inference path and measure where time and resources are actually being consumed before assuming that further model compression will produce meaningful gains.
Caching can eliminate repeated computations when the same inputs, representations, or intermediate results recur frequently, while batching can improve hardware utilization when the application's latency requirements allow multiple requests to be processed together. Selective inference can further reduce average resource consumption by routing straightforward cases through a small model and escalating only uncertain or difficult cases to a larger model, allowing the system to preserve access to advanced capabilities without paying the highest cost on every request.
Production systems should also define graceful-degradation strategies because resource availability can change unexpectedly, particularly during traffic spikes, connectivity failures, hardware constraints, or temporary infrastructure problems. A compact fallback model can provide continued service when the primary model is unavailable, while reduced-resolution inputs, simplified preprocessing, or lower-cost inference modes can help maintain functionality when full computational capacity is temporarily unavailable.
Monitor Compact Models After Deployment
Model efficiency can change after deployment because traffic patterns, input distributions, software runtimes, hardware configurations, and model-serving conditions may evolve, making continuous monitoring necessary even when the underlying model parameters remain unchanged. Engineers should track latency, throughput, memory usage, compute utilization, failure rates, and, where relevant, energy consumption alongside predictive quality so that efficiency regressions are detected before they become major operational problems.
Compact models also need monitoring for capability degradation because aggressive optimization can expose weaknesses under data conditions that were underrepresented during development, particularly when quantization, pruning, distillation, or input reduction affects specific classes or edge cases differently. Comparing production performance across meaningful slices can reveal whether the efficiency improvements preserved the behavior required by the application or inadvertently created a fragile model.
Versioning is equally important because teams need to understand which compression strategy, quantization configuration, training dataset, runtime, and hardware combination produced a particular production behavior, especially when multiple compact model variants are deployed across different devices or infrastructure tiers.
Key Takeaway
Deploying compact ML models successfully requires optimization around the actual hardware and workload rather than treating model size as the only measure of efficiency. Engineers need to balance predictive quality with latency, memory, throughput, and energy, while efficient serving, selective inference, caching, graceful degradation, and continuous monitoring help preserve the advantages of smaller models after deployment. The strongest compact-model systems are designed as complete production architectures in which model efficiency and operational reliability are optimized together.
Section 4: Why Small Models Could Become a Core Part of the Future AI Stack
The return of compact machine learning models is not simply a reaction to the computational cost of large AI systems, because the deeper change is occurring in how engineers think about where intelligence should live, how much computation different tasks require, and how AI capabilities should be distributed across cloud, edge, and specialized infrastructure. As organizations deploy increasing numbers of models, the ability to select an appropriate level of model capacity for each workload can become as important as achieving the highest possible benchmark score.
Small Models Can Enable Intelligence Everywhere
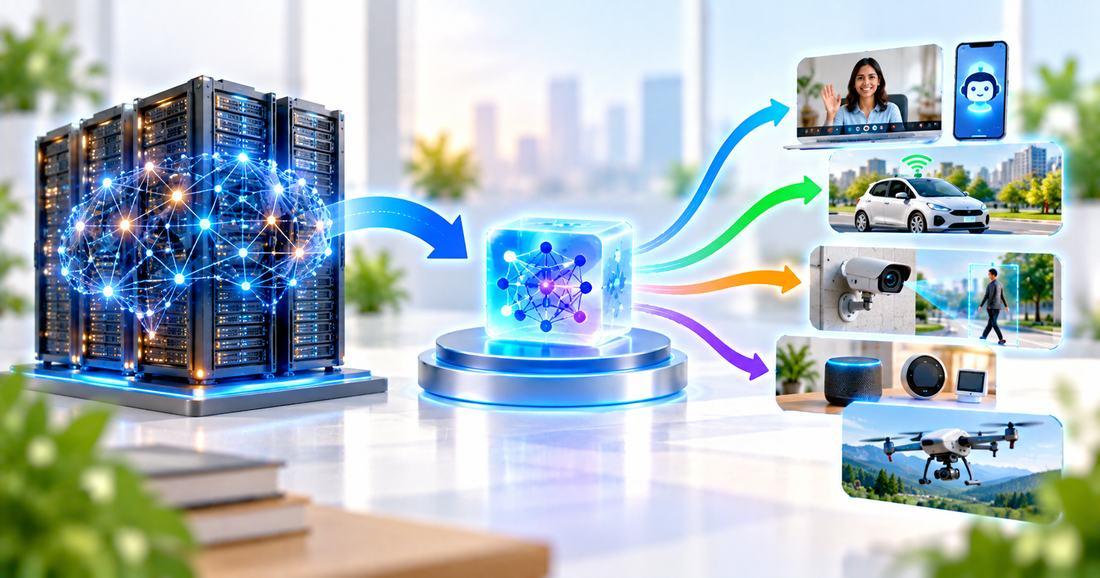
Large models depend heavily on powerful infrastructure, while compact models can make sophisticated machine learning practical in environments where compute, memory, connectivity, or energy are limited, creating opportunities for intelligence to operate directly on mobile devices, industrial equipment, cameras, vehicles, embedded systems, and other edge environments.
Local inference can reduce the need to transmit raw information to centralized systems, which can improve responsiveness and potentially reduce bandwidth requirements while also supporting applications where keeping data close to its source is operationally or privacy-wise advantageous. A factory camera, for example, can perform an initial visual inspection locally and transmit only relevant events for additional centralized analysis, while a mobile application can perform classification or personalization without continuously sending every input to a remote service.
This distributed architecture can also improve resilience because an edge device does not necessarily need continuous connectivity to perform every inference, although the system still needs appropriate mechanisms for model updates, monitoring, synchronization, and recovery when local resources become unavailable.
The broader trend is therefore toward distributed intelligence, where model capability is placed at the location that best matches the application's latency, privacy, connectivity, and resource requirements rather than assuming that every inference should be performed in a centralized environment.
Small Models Can Improve the Economics of AI at Scale
The economic value of compact models becomes especially visible when inference volume is high, because even small reductions in per-request compute can accumulate into substantial infrastructure savings when multiplied across millions or billions of predictions.
A recommendation service, search system, fraud detector, or enterprise classification pipeline may execute continuously, which means that a modest improvement in average inference efficiency can reduce accelerator demand, increase throughput per server, lower energy consumption, or allow the same infrastructure budget to support more workloads. These benefits can become more significant than a small improvement in benchmark accuracy when the additional model capability does not materially change downstream business outcomes.
Compact models can also improve organizational scalability because teams can deploy more specialized models without requiring every application to consume the infrastructure associated with a large general-purpose architecture. A business may use a lightweight model for classification, another compact model for ranking, and a larger model only for complex cases, creating a portfolio in which compute is allocated according to task requirements rather than applied uniformly.
This economic perspective is closely connected with “The Economics of Machine Learning: Measuring the True Cost of a Model,” because the practical value of a model depends not only on what it can predict, but also on how much infrastructure, energy, maintenance, and operational complexity are required to deliver those predictions at production scale.
Small Models Will Become Part of Hybrid AI Architectures
The future of AI is unlikely to be divided into systems that use only small models or only large models, because different components of an application can require different levels of capability. Compact models can become highly effective first-stage components that perform classification, filtering, routing, retrieval, anomaly detection, or confidence estimation before deciding whether more expensive computation is necessary.
A customer-support system, for example, can use a small classifier to identify routine requests and resolve them through deterministic workflows, while ambiguous requests can be passed to a larger language model for more extensive reasoning. A computer-vision pipeline can use an efficient detector to identify whether a scene requires detailed inspection, while a larger model is activated only when the initial result indicates that additional analysis is justified.
This creates an architecture in which model size becomes a routing decision rather than a fixed property of the entire application, allowing organizations to combine efficiency with access to advanced capabilities when those capabilities are actually required.
The approach also makes small models valuable as monitoring and safety layers because a compact model can independently check outputs, detect anomalies, validate classifications, or identify situations in which a larger system may require additional scrutiny, creating redundancy without duplicating the full computational cost of the primary model.
Efficient Intelligence Could Become a Core Design Principle
The long-term importance of compact models may ultimately come from a broader change in AI engineering philosophy, where efficiency is treated not as a post-development optimization but as an inherent characteristic of useful intelligence. Engineers may increasingly evaluate models through a multidimensional objective that includes predictive quality, latency, memory, energy, cost, robustness, and deployment flexibility, which can make a compact model more attractive even when a larger alternative achieves a higher raw benchmark score.
This perspective also encourages architectures that perform only the computation necessary for a given problem, which can involve sparse activation, conditional computation, selective inference, compressed representations, and hardware-aware execution rather than simply reducing the number of parameters after training.
Key Takeaway
Compact machine learning models could become a core part of the future AI stack because they enable distributed intelligence, improve the economics of high-volume inference, and provide efficient components for hybrid architectures that dynamically allocate computation according to task difficulty. The long-term shift is not simply toward smaller models, but toward fit-for-purpose intelligence, where model capacity, resource consumption, and business value are designed together so that every unit of computation contributes meaningful capability.
Conclusion
The resurgence of compact machine learning models is not simply a reaction to the increasing cost of large AI systems, because it reflects a broader realization that model size should be determined by application requirements rather than treated as an objective in itself.
Large models remain extremely valuable when broad knowledge, complex reasoning, or difficult generalization tasks justify their computational requirements, but many production applications do not need that level of capability. A fraud classifier, industrial anomaly detector, recommendation ranker, demand forecasting model, or embedded vision system may benefit more from a model that is fast, efficient, predictable, and specifically optimized for its task.
This creates a more practical definition of model quality.
A useful production model needs to provide sufficient predictive capability while operating within acceptable limits for latency, memory, compute, energy, cost, and deployment complexity.
Compact models can perform well under these constraints because modern engineering techniques allow teams to preserve important capabilities while eliminating unnecessary computation. Knowledge distillation can transfer useful behavior from larger models, pruning can remove low-value components, quantization can reduce numerical precision and memory requirements, and architecture optimization can create models that are efficient by design rather than compressed only after training.
Task-specific training can further improve this efficiency because a compact model does not need to represent every capability of a general-purpose system when the application requires only a narrow set of functions. By focusing learning on the inputs, behaviors, edge cases, and operational conditions that matter for the target task, engineers can use limited model capacity more effectively.
The architecture surrounding the model matters just as much.
A small model can become part of a model cascade in which it handles routine inputs and forwards difficult cases to a larger model. This allows organizations to preserve access to advanced capabilities without paying the highest computational cost for every request.
The result is a more flexible AI architecture in which model size becomes a deployment decision rather than a fixed characteristic of the entire application.
Frequently Asked Questions
1. Why are small machine learning models becoming popular again?
Compact models are becoming increasingly attractive because many production applications prioritize low latency, lower inference cost, reduced memory usage, energy efficiency, and deployment flexibility alongside predictive performance.
2. Are small models better than large models?
Neither model size is universally better because the appropriate architecture depends on the task, required capability, deployment environment, latency target, and resource budget. A large model may be appropriate for complex reasoning, while a compact model may be more suitable for a narrow production task.
3. What is a compact machine learning model?
A compact machine learning model is an architecture designed or optimized to provide useful predictive capability with relatively low requirements for parameters, compute, memory, latency, or energy compared with larger alternatives serving a similar task.
4. How can a small model achieve good performance?
Compact models can benefit from knowledge distillation, pruning, quantization, efficient architectures, task-specific training, high-quality data, and selective computation, allowing them to preserve important capabilities without maintaining unnecessary model capacity.
5. What is knowledge distillation?
Knowledge distillation is a technique in which a smaller student model learns from a larger teacher model, using information such as teacher predictions or intermediate representations to transfer useful behavior into a more compact architecture.
6. What is model pruning?
Model pruning removes parameters, connections, channels, or other components that contribute relatively little to the required task, potentially reducing model size and computation while attempting to preserve important predictive behavior.
7. How does quantization help small models?
Quantization uses lower-precision numerical representations for model parameters or activations, which can reduce memory consumption and improve inference efficiency when the target hardware supports the selected numerical formats.
8. Why are small models useful for edge AI?
Edge devices often have limited compute, memory, storage, battery capacity, and network connectivity, making compact models better suited to local inference where low latency, reduced data transfer, and continuous operation are important.
9. Can small models work with large language models?
Yes, compact models can complement larger language models by performing classification, routing, filtering, retrieval, safety checks, or other narrow tasks before or after the larger model is invoked, which can reduce average inference cost.
10. What is a model cascade?
A model cascade is an architecture in which multiple models with different levels of capability handle inputs at different stages, allowing lightweight models to resolve straightforward cases while more expensive models are reserved for ambiguous or difficult inputs.
11. How do small models reduce AI infrastructure costs?
Compact models generally require fewer computational resources per inference, which can reduce memory requirements, accelerator usage, energy consumption, and infrastructure costs, particularly when the model serves high volumes of requests.
12. Can compact models improve AI latency?
They can, particularly when their architecture requires less computation and memory movement, although actual latency depends on the model, hardware, runtime, input size, batching strategy, and surrounding inference pipeline.
13. What are the limitations of small machine learning models?
Compact models may have lower capacity for highly complex tasks, can lose important capabilities during aggressive compression, and may become less robust on difficult or rare inputs if optimization focuses too heavily on reducing resource consumption.
14. How should engineers choose between a small and large model?
Engineers should compare candidate models across predictive quality, robustness, latency, memory, throughput, energy, infrastructure cost, maintenance complexity, and the actual business value of additional capability rather than selecting a model based on size alone.
15. What is the future of compact machine learning models?
Compact models are likely to become a core component of heterogeneous AI architectures in which different model sizes are deployed according to task complexity, resource availability, latency requirements, privacy considerations, and business value, while larger models remain available for situations that genuinely require greater capability.